<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" xml:lang="en_US"><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://www.fratepietro.com/feed.xml" rel="self" type="application/atom+xml" /><link href="https://www.fratepietro.com/" rel="alternate" type="text/html" hreflang="en_US" /><updated>2026-09-07T15:50:39+02:00</updated><id>https://www.fratepietro.com/feed.xml</id><title type="html">Antonello Fratepietro</title><subtitle>Cloud engineer and developer passionate about building scalable Cloud and AI infrastructure. Writings on software architecture, distributed systems, and engineering leadership.</subtitle><author><name>Antonello Fratepietro</name><email>antonello.f at gmail dot com</email></author><entry><title type="html">gitgui: a real git GUI inside cmux, next to Pi</title><link href="https://www.fratepietro.com/2026/gitgui-terminal-git-gui-cmux-pi/" rel="alternate" type="text/html" title="gitgui: a real git GUI inside cmux, next to Pi" /><published>2026-09-03T00:00:00+02:00</published><updated>2026-09-07T00:00:00+02:00</updated><id>https://www.fratepietro.com/2026/gitgui-terminal-git-gui-cmux-pi</id><content type="html" xml:base="https://www.fratepietro.com/2026/gitgui-terminal-git-gui-cmux-pi/"><![CDATA[<p>I wrote <a href="/2026/cmux-pi-unsloth-local-glm-setup/">The Local Agent Trio: cmux + Pi + Unsloth Studio</a> about splitting your local stack into cmux, inference, and Pi. Git stayed in the shell.</p>

<p>Pi runs <code class="language-plaintext highlighter-rouge">git status</code> and <code class="language-plaintext highlighter-rouge">git diff</code> fine. You still lose the commit graph, the staged file list, inline diffs, and hunk buttons when you review a refactor. I kept Alt-Tabbing to Fork or squinting at <code class="language-plaintext highlighter-rouge">git diff</code> output. I wanted Sourcetree in the same cmux grid as the agent.</p>

<p>So I built <a href="https://github.com/antonellof/gitgui">gitgui</a>, one Rust binary that paints a GUI into your terminal pane with the <a href="https://sw.kovidgoyal.net/kitty/graphics-protocol/">kitty graphics protocol</a>. Pixels, not a TUI. Graph, sidebar, diff viewer, commit box, editor, conflict resolver. cmux, Ghostty, kitty, WezTerm. Over SSH it sends zlib plus base64 frames.</p>

<p><em>Updated 2026-09-07 for v0.6.0: the UI moved from egui to <a href="https://iced.rs">iced</a>, the panes drag, resize and hide, merge conflicts get a three-way resolver, the layout is remembered per repository, and the same binary opens a desktop window in terminals without kitty graphics. Plus a folder switcher, zoom keys and SHA-256 repositories.</em></p>

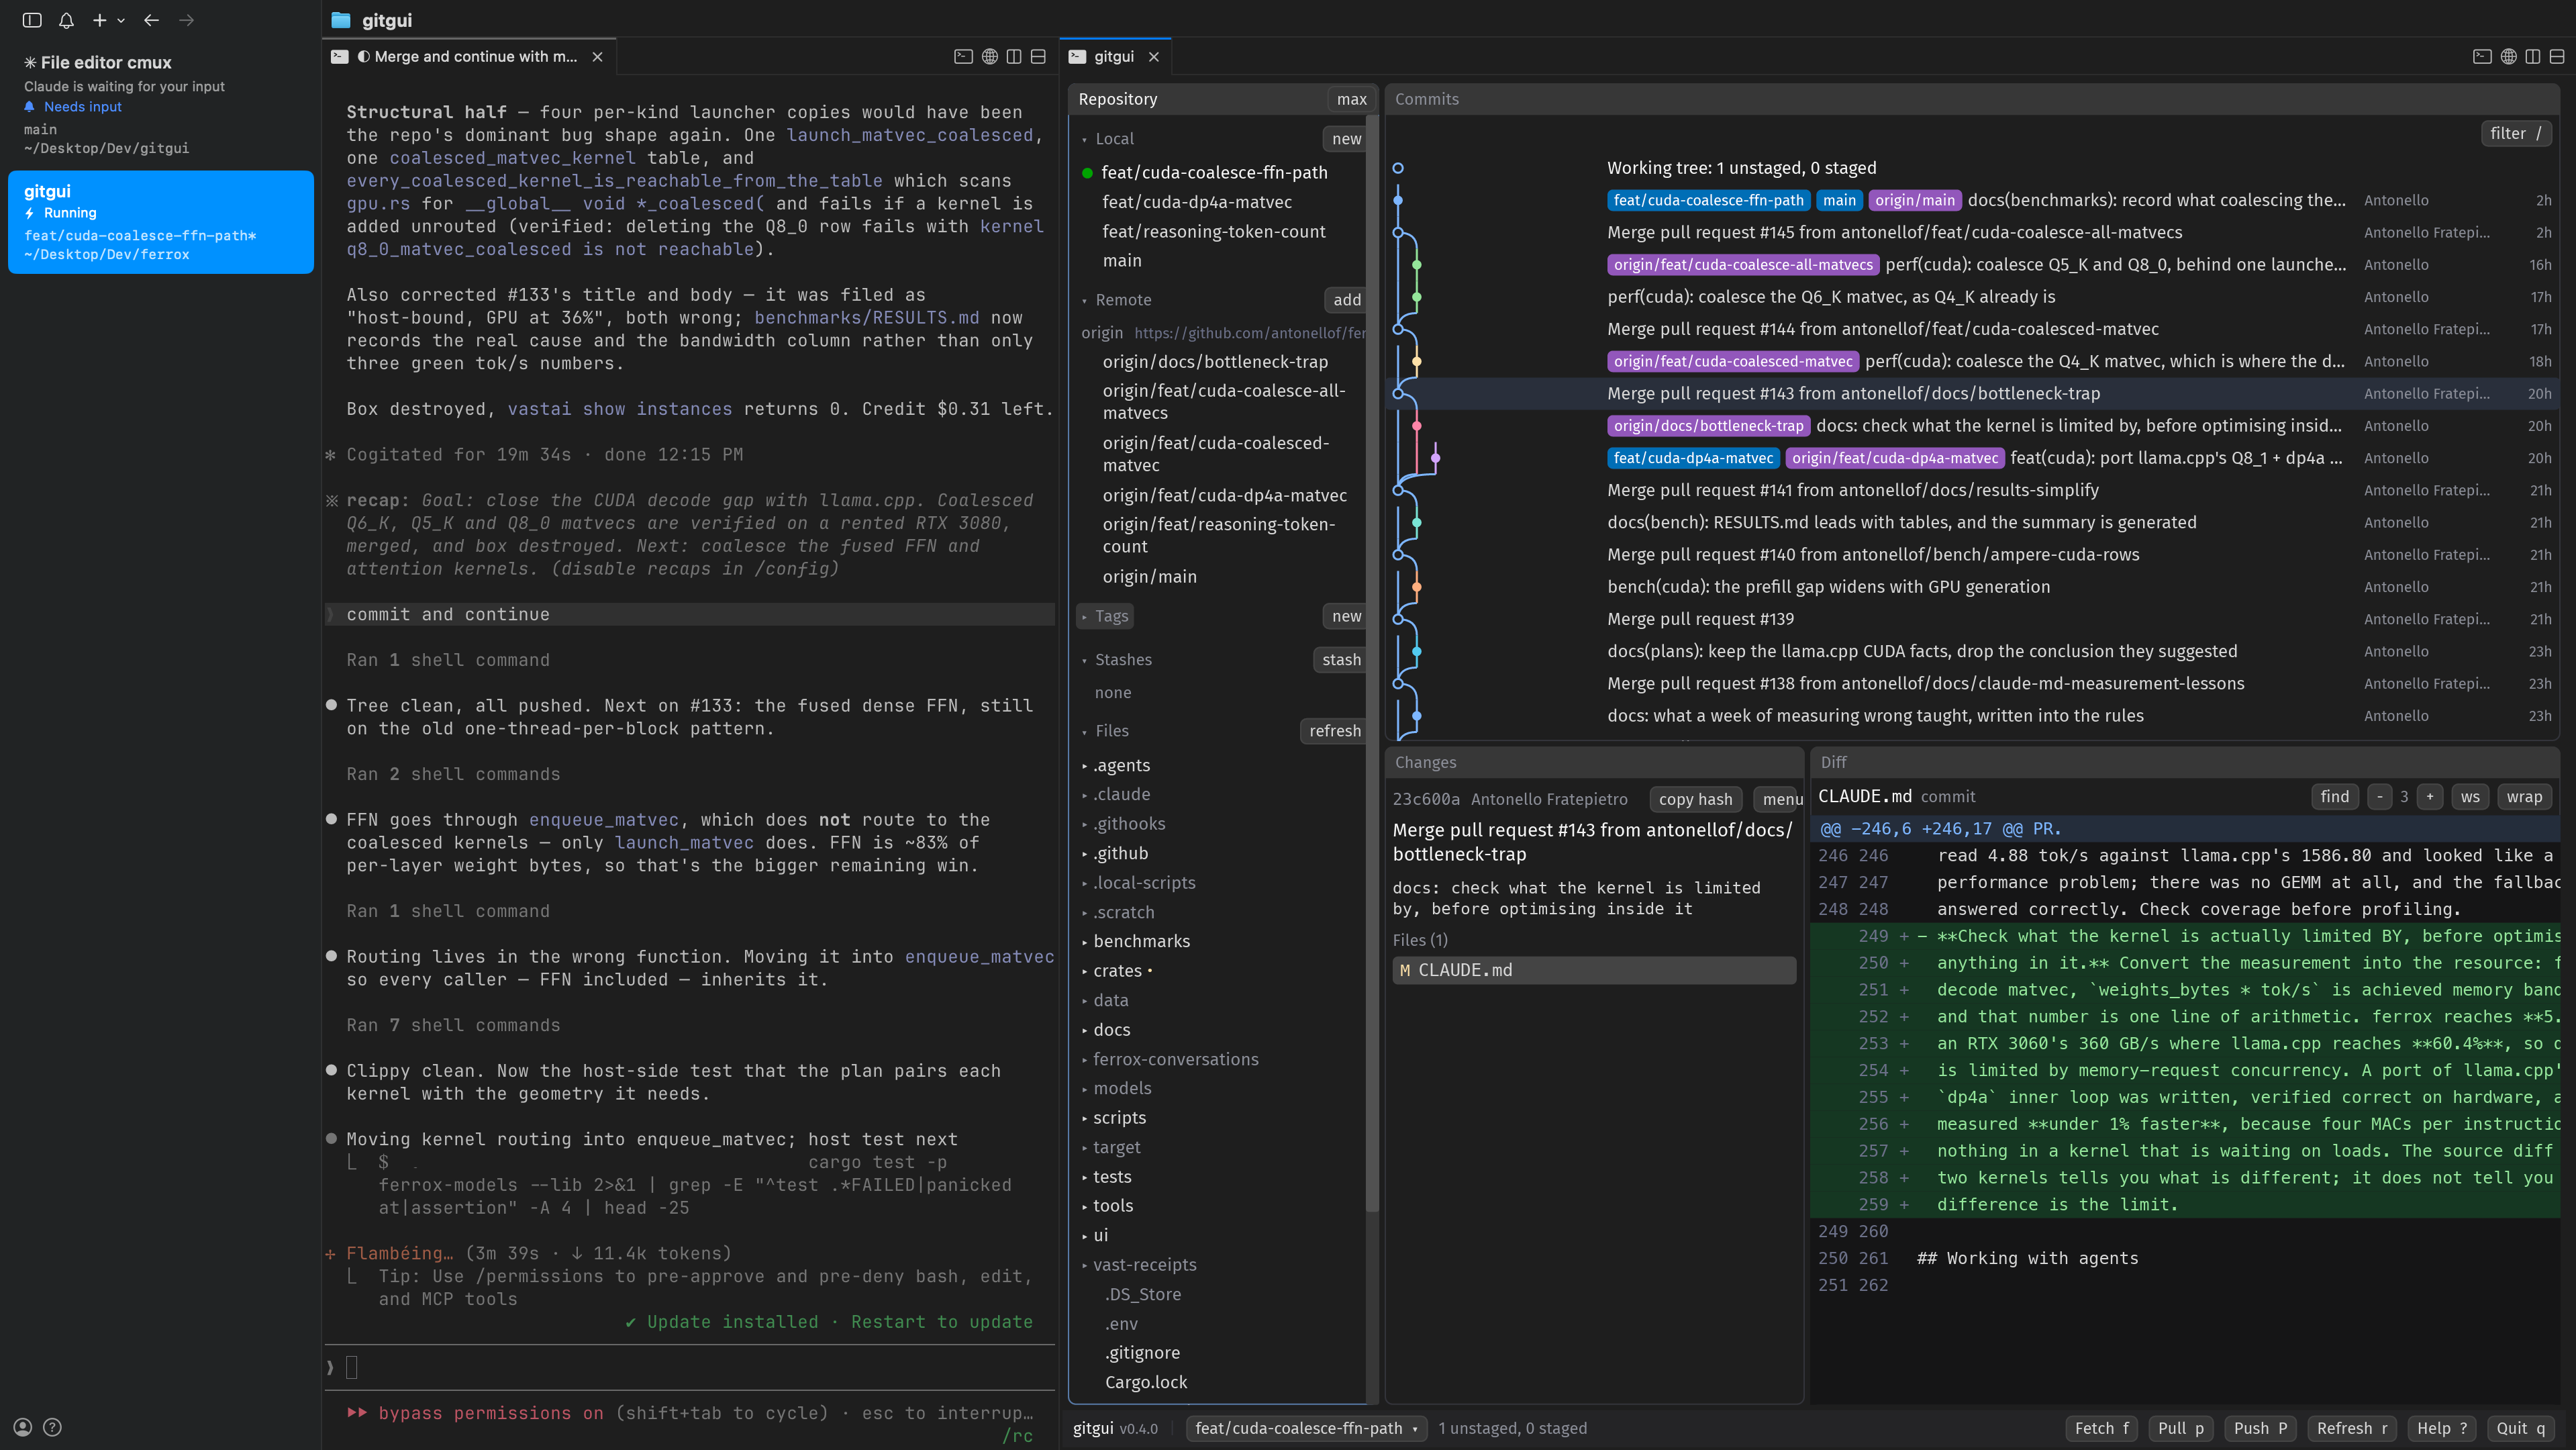
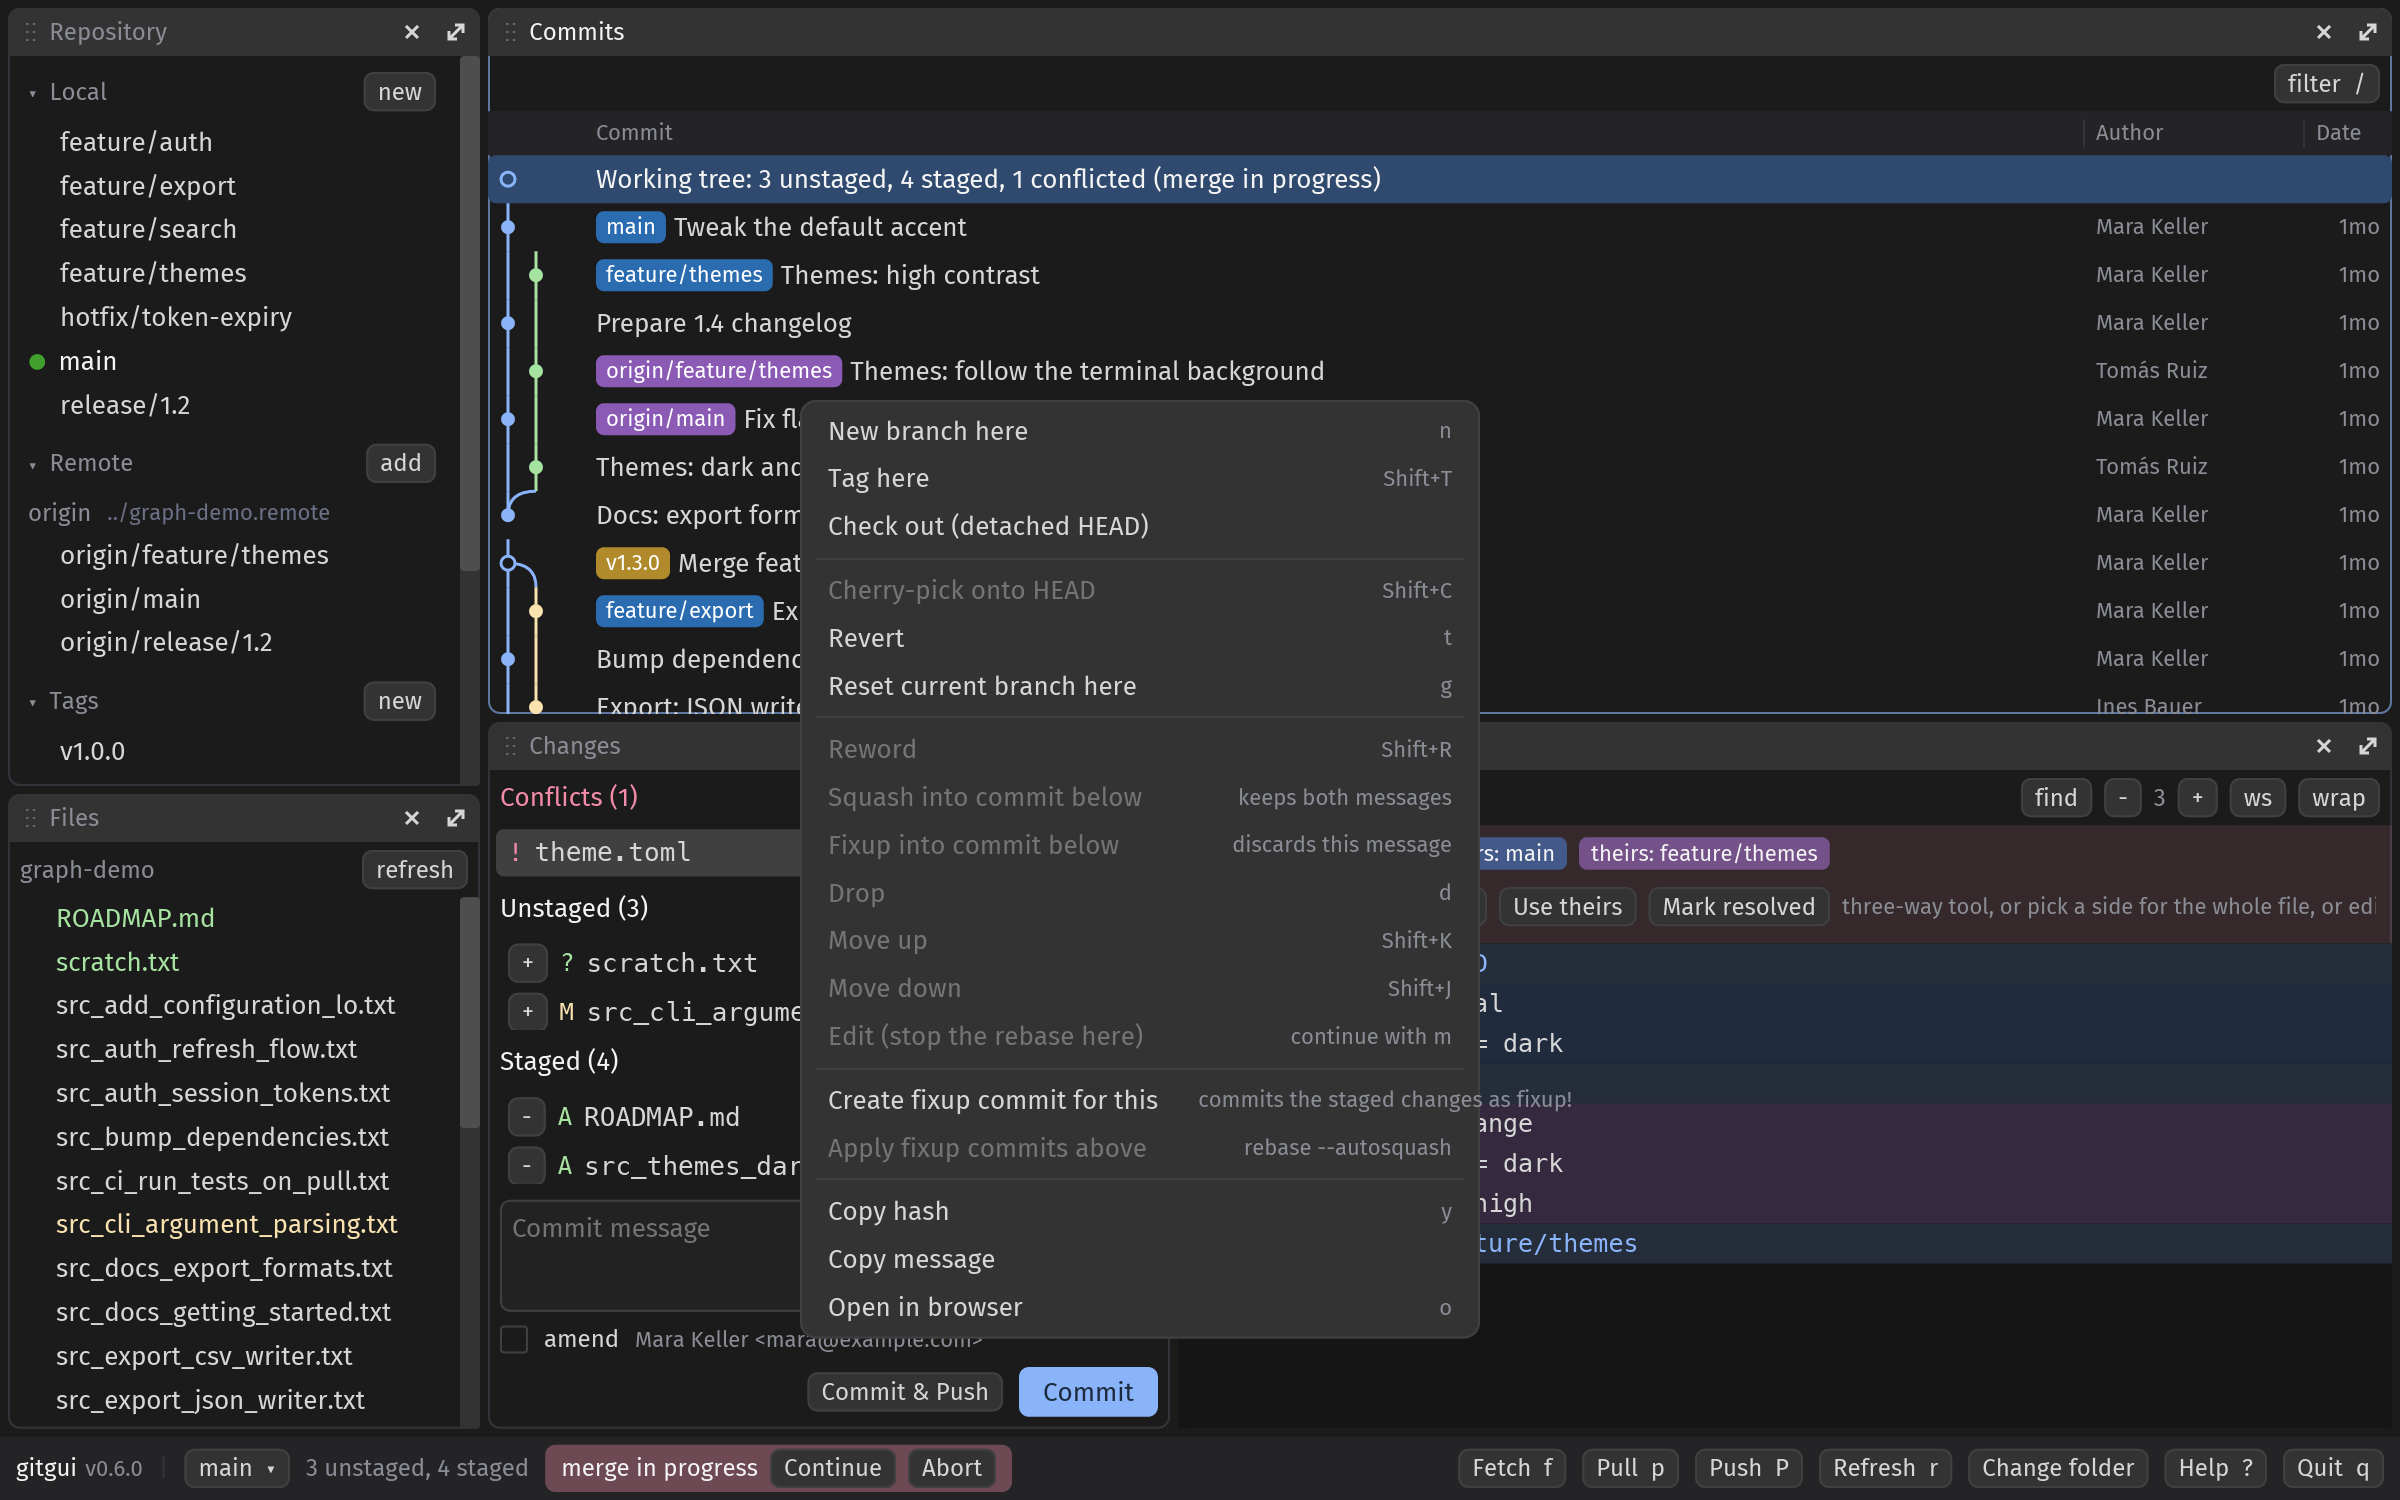
<p>This is my daily layout: the agent on the left, gitgui v0.6.0 on the right, same cmux workspace, same checkout.</p>

<p><img src="/assets/images/posts/gitgui-cmux-claude.png" alt="gitgui in a cmux split next to Claude Code: repository sidebar, commit graph with branch lanes, changes and diff" /></p>

<p>The agent edits the repo. gitgui shows branch lanes, unstaged files, and hunk buttons. One workspace. One checkout.
cmux + agent + gitgui = 😍</p>

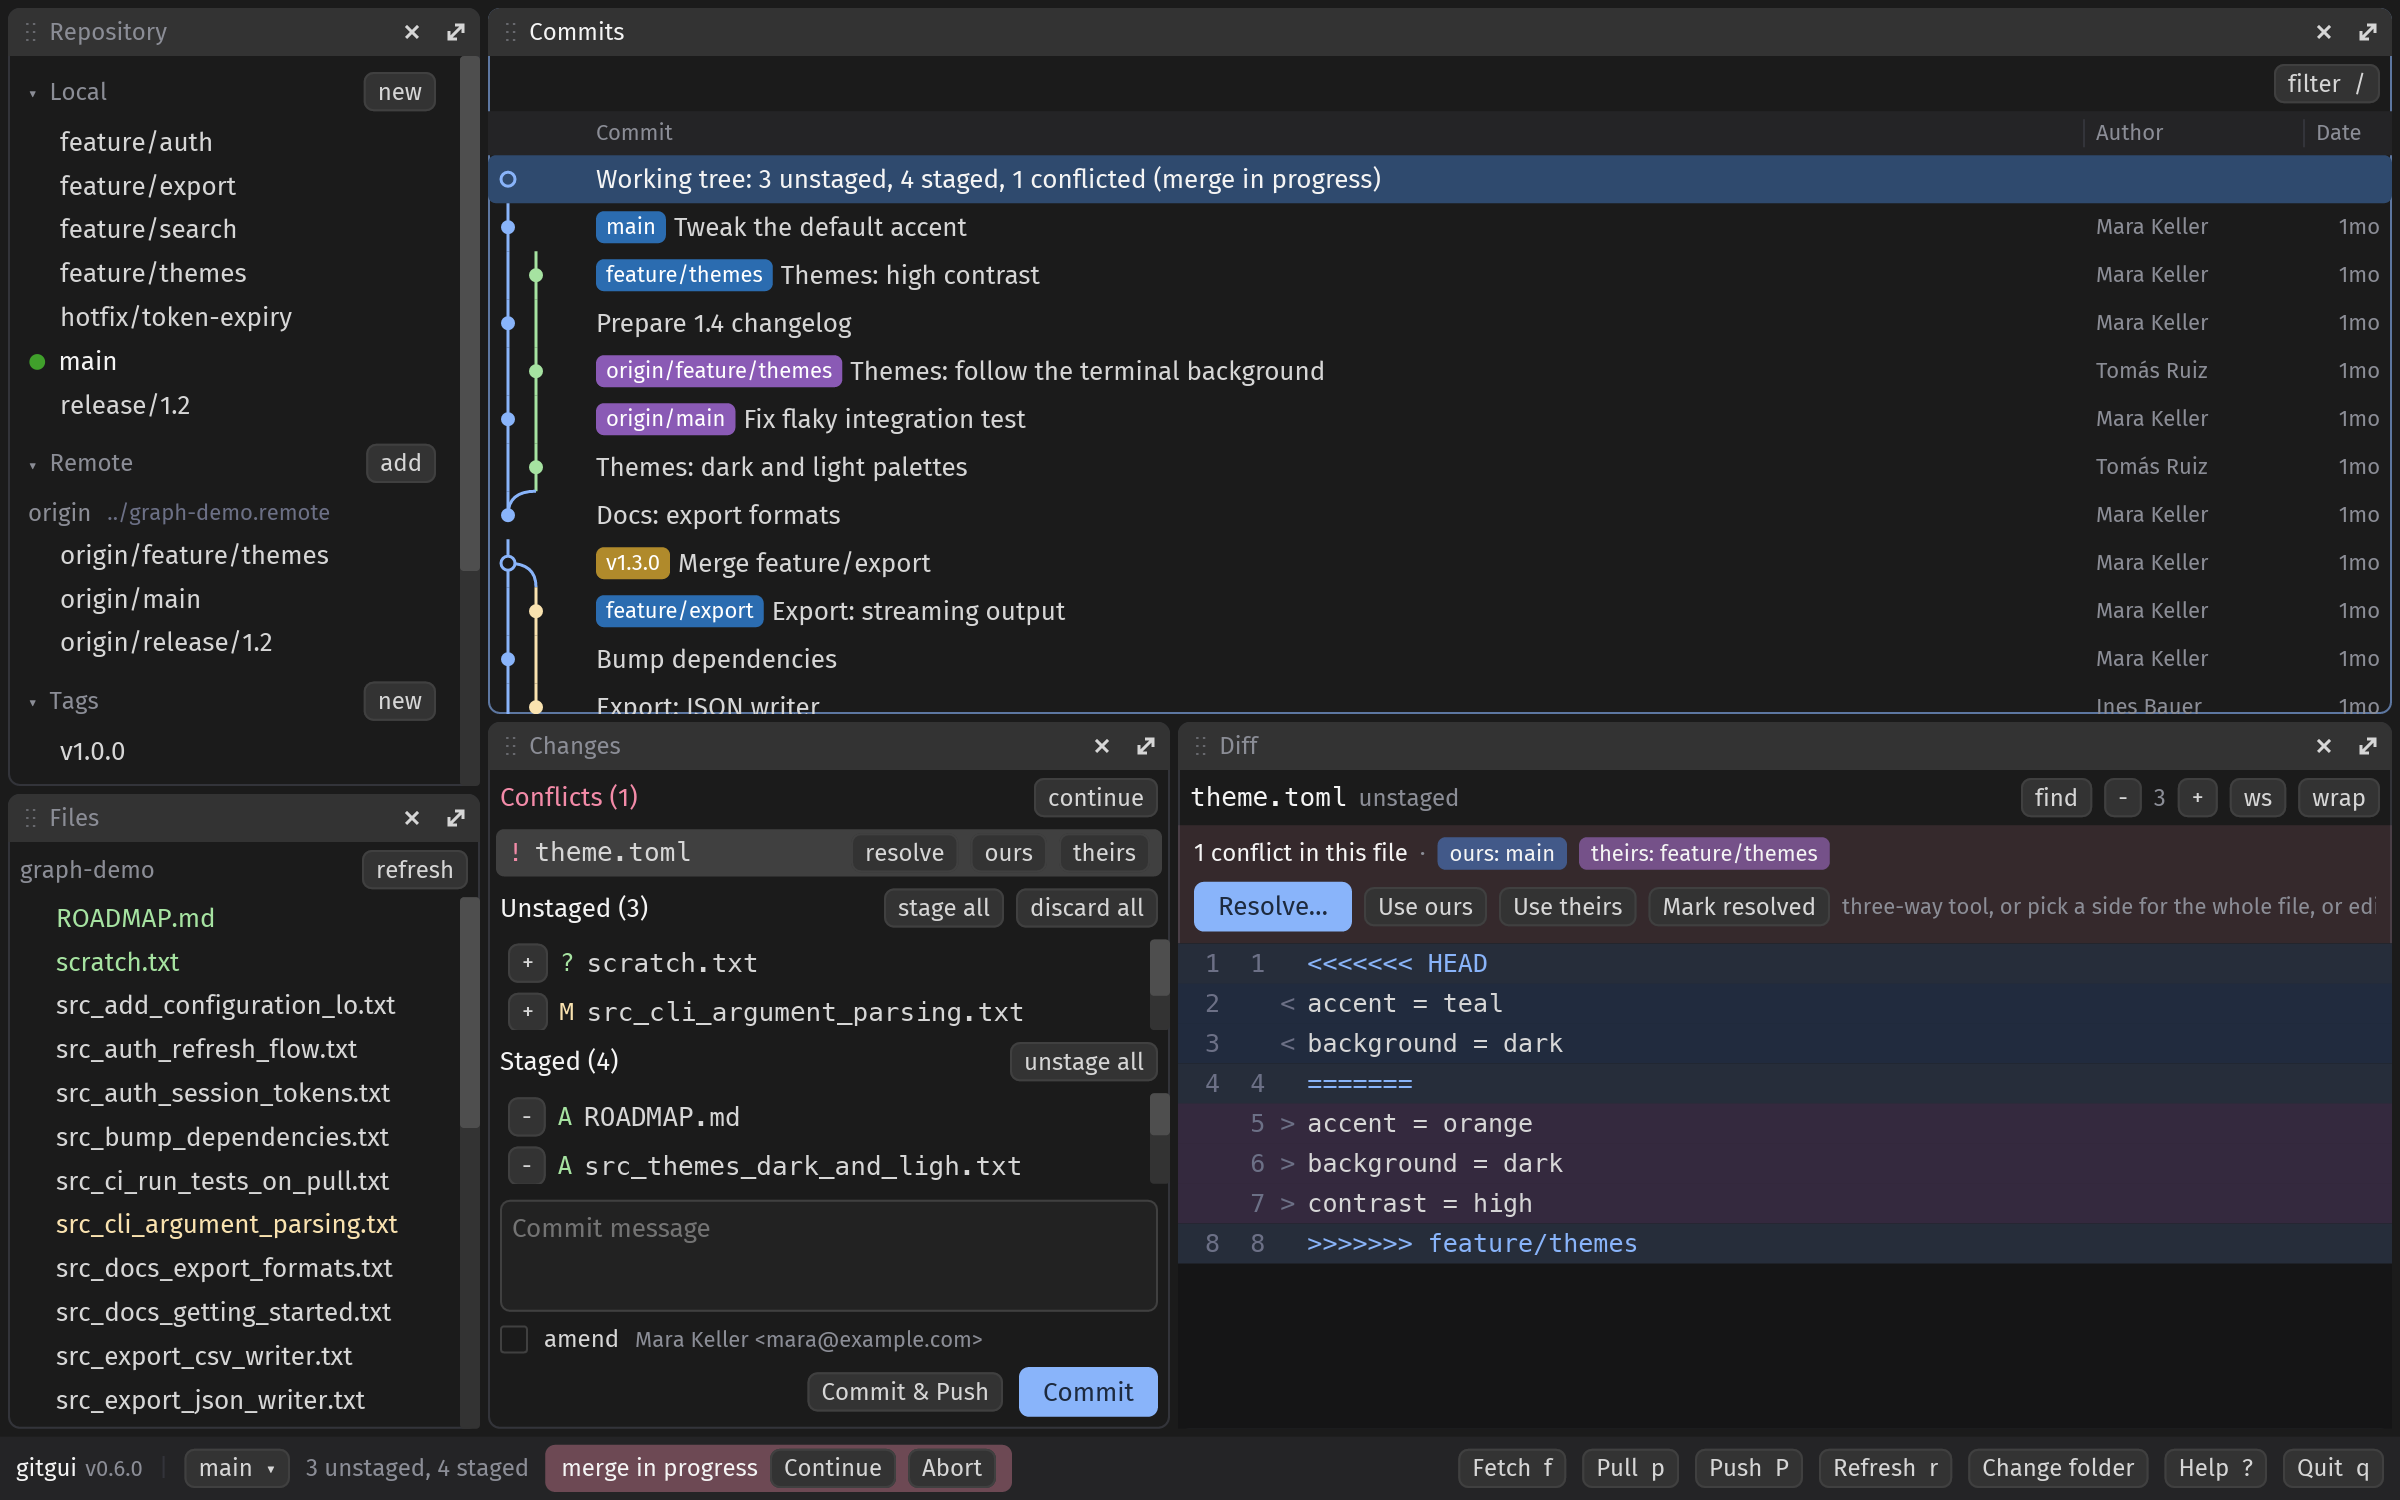
<p>On a repo with branches, tags, a stash and a merge stopped on a conflict it looks like this:</p>

<p><img src="/assets/images/posts/gitgui-panes.png" alt="gitgui v0.6.0: repository sidebar, file tree, commit graph with branch lanes, changes with a conflict, diff with the conflict banner" /></p>

<h2 id="why-stay-inside-the-terminal">Why stay inside the terminal?</h2>

<p>cmux is a pane grid. You already split shell, Pi, and sometimes a browser. Fork or GitKraken pull you out: different font, different shortcuts, another app fighting for focus.</p>

<p>lazygit and gitui help for quick commits. They fall short when you read a three-file refactor with colored hunks, click Stage hunk on one block, and scan merge lanes on a graph. I wanted mouse clicks and a graph without leaving the grid.</p>

<p><a href="https://github.com/zenbu-labs/terminal-browser">terminal-browser</a> and <a href="https://github.com/zenbu-labs/terminal-code">terminal-code</a> proved the pattern: render pixels in the terminal, read pixel mouse events back. gitgui uses <a href="https://iced.rs">iced</a> instead of Chromium, driven without a window.</p>

<p>Three steps:</p>

<ol>
  <li>Build the iced UI, draw it with the tiny-skia software renderer straight into an RGBA framebuffer</li>
  <li>Send the framebuffer as a kitty graphics image each frame</li>
  <li>Map kitty keyboard and SGR mouse events into iced events</li>
</ol>

<p>Your terminal never prints UI text. It shows a picture. Locally frames go through POSIX shared memory. On my Mac a 1600×1000 frame at 2x costs about 6 ms.</p>

<h2 id="what-you-get-in-v060">What you get in v0.6.0</h2>

<ul>
  <li><strong>Panes you arrange</strong>: repository, files, commits, changes and diff on an iced pane grid. Drag a title bar to move a pane, drag the gaps to resize, maximize with the arrows or <code class="language-plaintext highlighter-rouge">1</code> to <code class="language-plaintext highlighter-rouge">5</code>, hide a pane with its x and bring it back from the footer. The commit list’s columns resize from the header. The layout, hidden panes, collapsed sections and zoom are saved per repository in <code class="language-plaintext highlighter-rouge">.git/gitgui.json</code> and come back on the next start.</li>
  <li><strong>Commit graph</strong> with branch lanes, ref pills, filter by summary, author or hash.</li>
  <li><strong>Staging by file, hunk or line</strong>: click, Shift+click or drag lines in the diff, then Stage or Discard just those. Search in the diff, adjust context, ignore whitespace, wrap.</li>
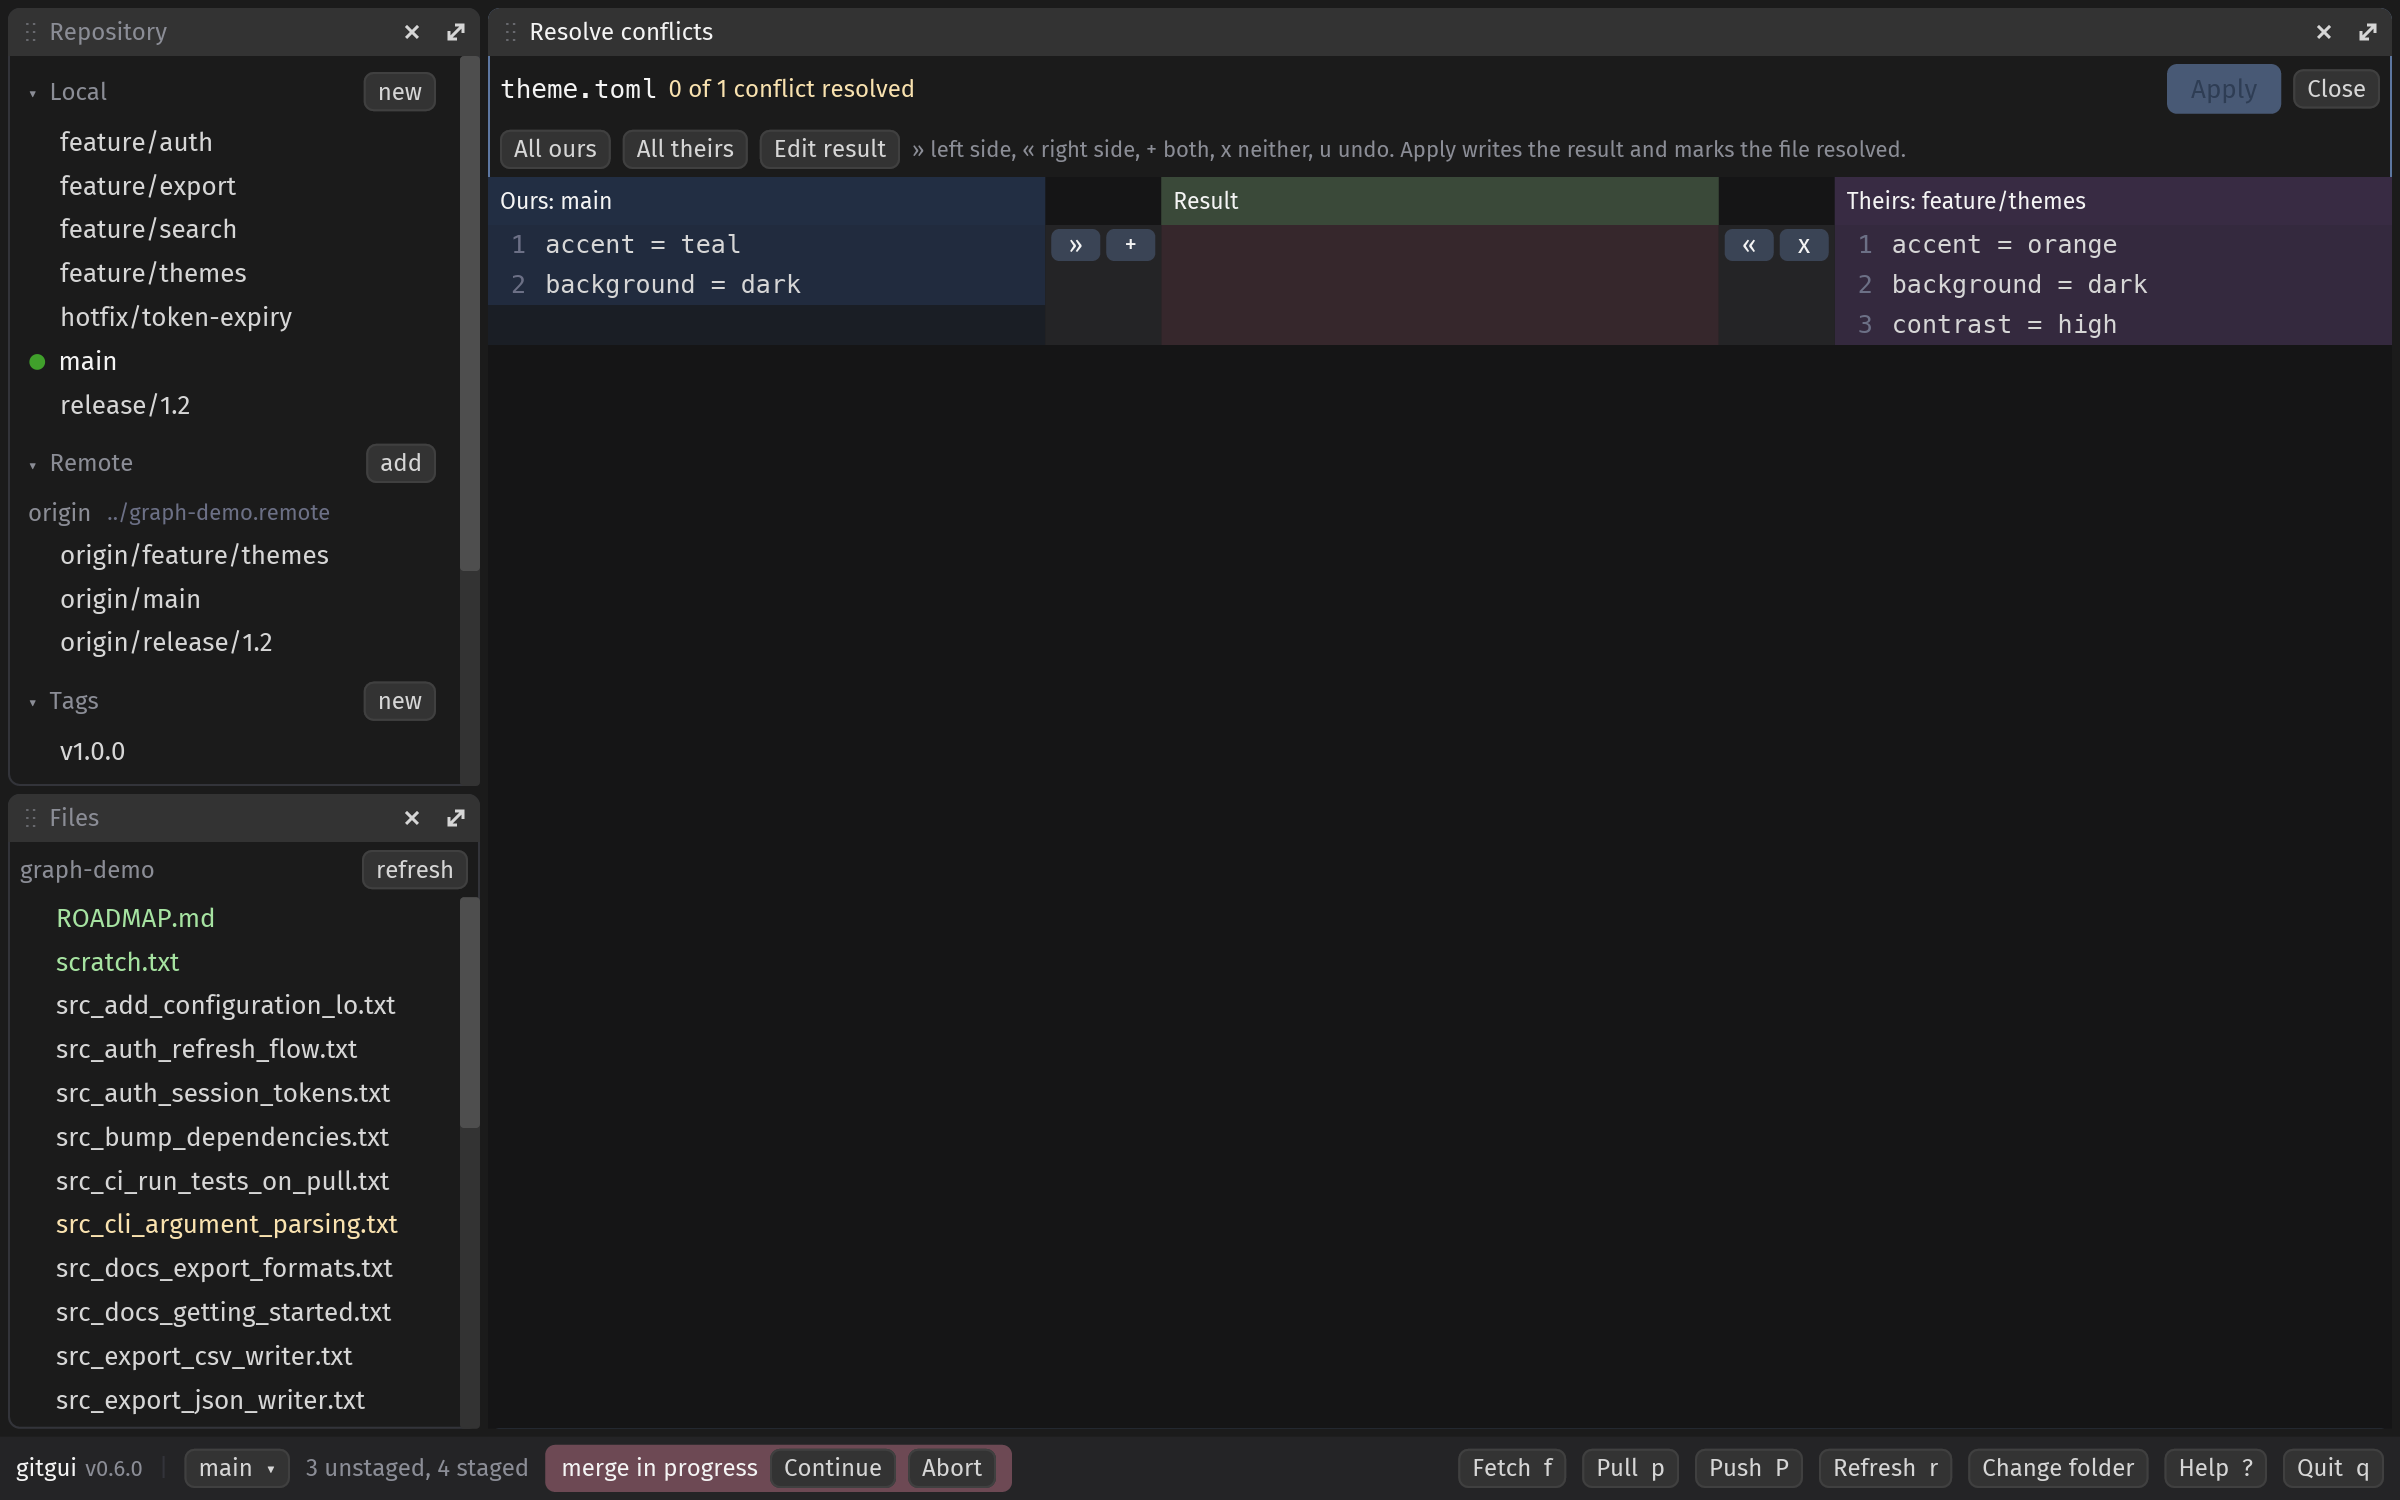
  <li><strong>Three-way conflict resolver</strong>: ours, result, theirs side by side with per-conflict take-left, take-right, keep-both, drop buttons, accept-all, edit the result, apply and mark resolved. Conflicted files also get a banner with whole-file ours / theirs.</li>
</ul>

<p><img src="/assets/images/posts/gitgui-merge.png" alt="Three-way conflict resolver: ours, result, theirs with per-conflict buttons" /></p>

<ul>
  <li><strong>History rewriting from the commit menu</strong>: reword, squash, fixup, drop, move up / down, edit, autosquash. gitgui runs <code class="language-plaintext highlighter-rouge">git rebase</code> with itself as the sequence editor, so no editor pops up in your pane.</li>
  <li><strong>Branches, remotes, tags, stashes</strong> in a collapsible sidebar: checkout, create, rename, delete, merge, rebase onto, fast-forward, upstream, open pull request, delete on remote, fetch one remote, push a tag, apply / pop / drop / branch from stash.</li>
  <li><strong>File tree</strong> of the whole working tree, folders listed on demand, changed files colored. Click a file and it opens in the built-in editor.</li>
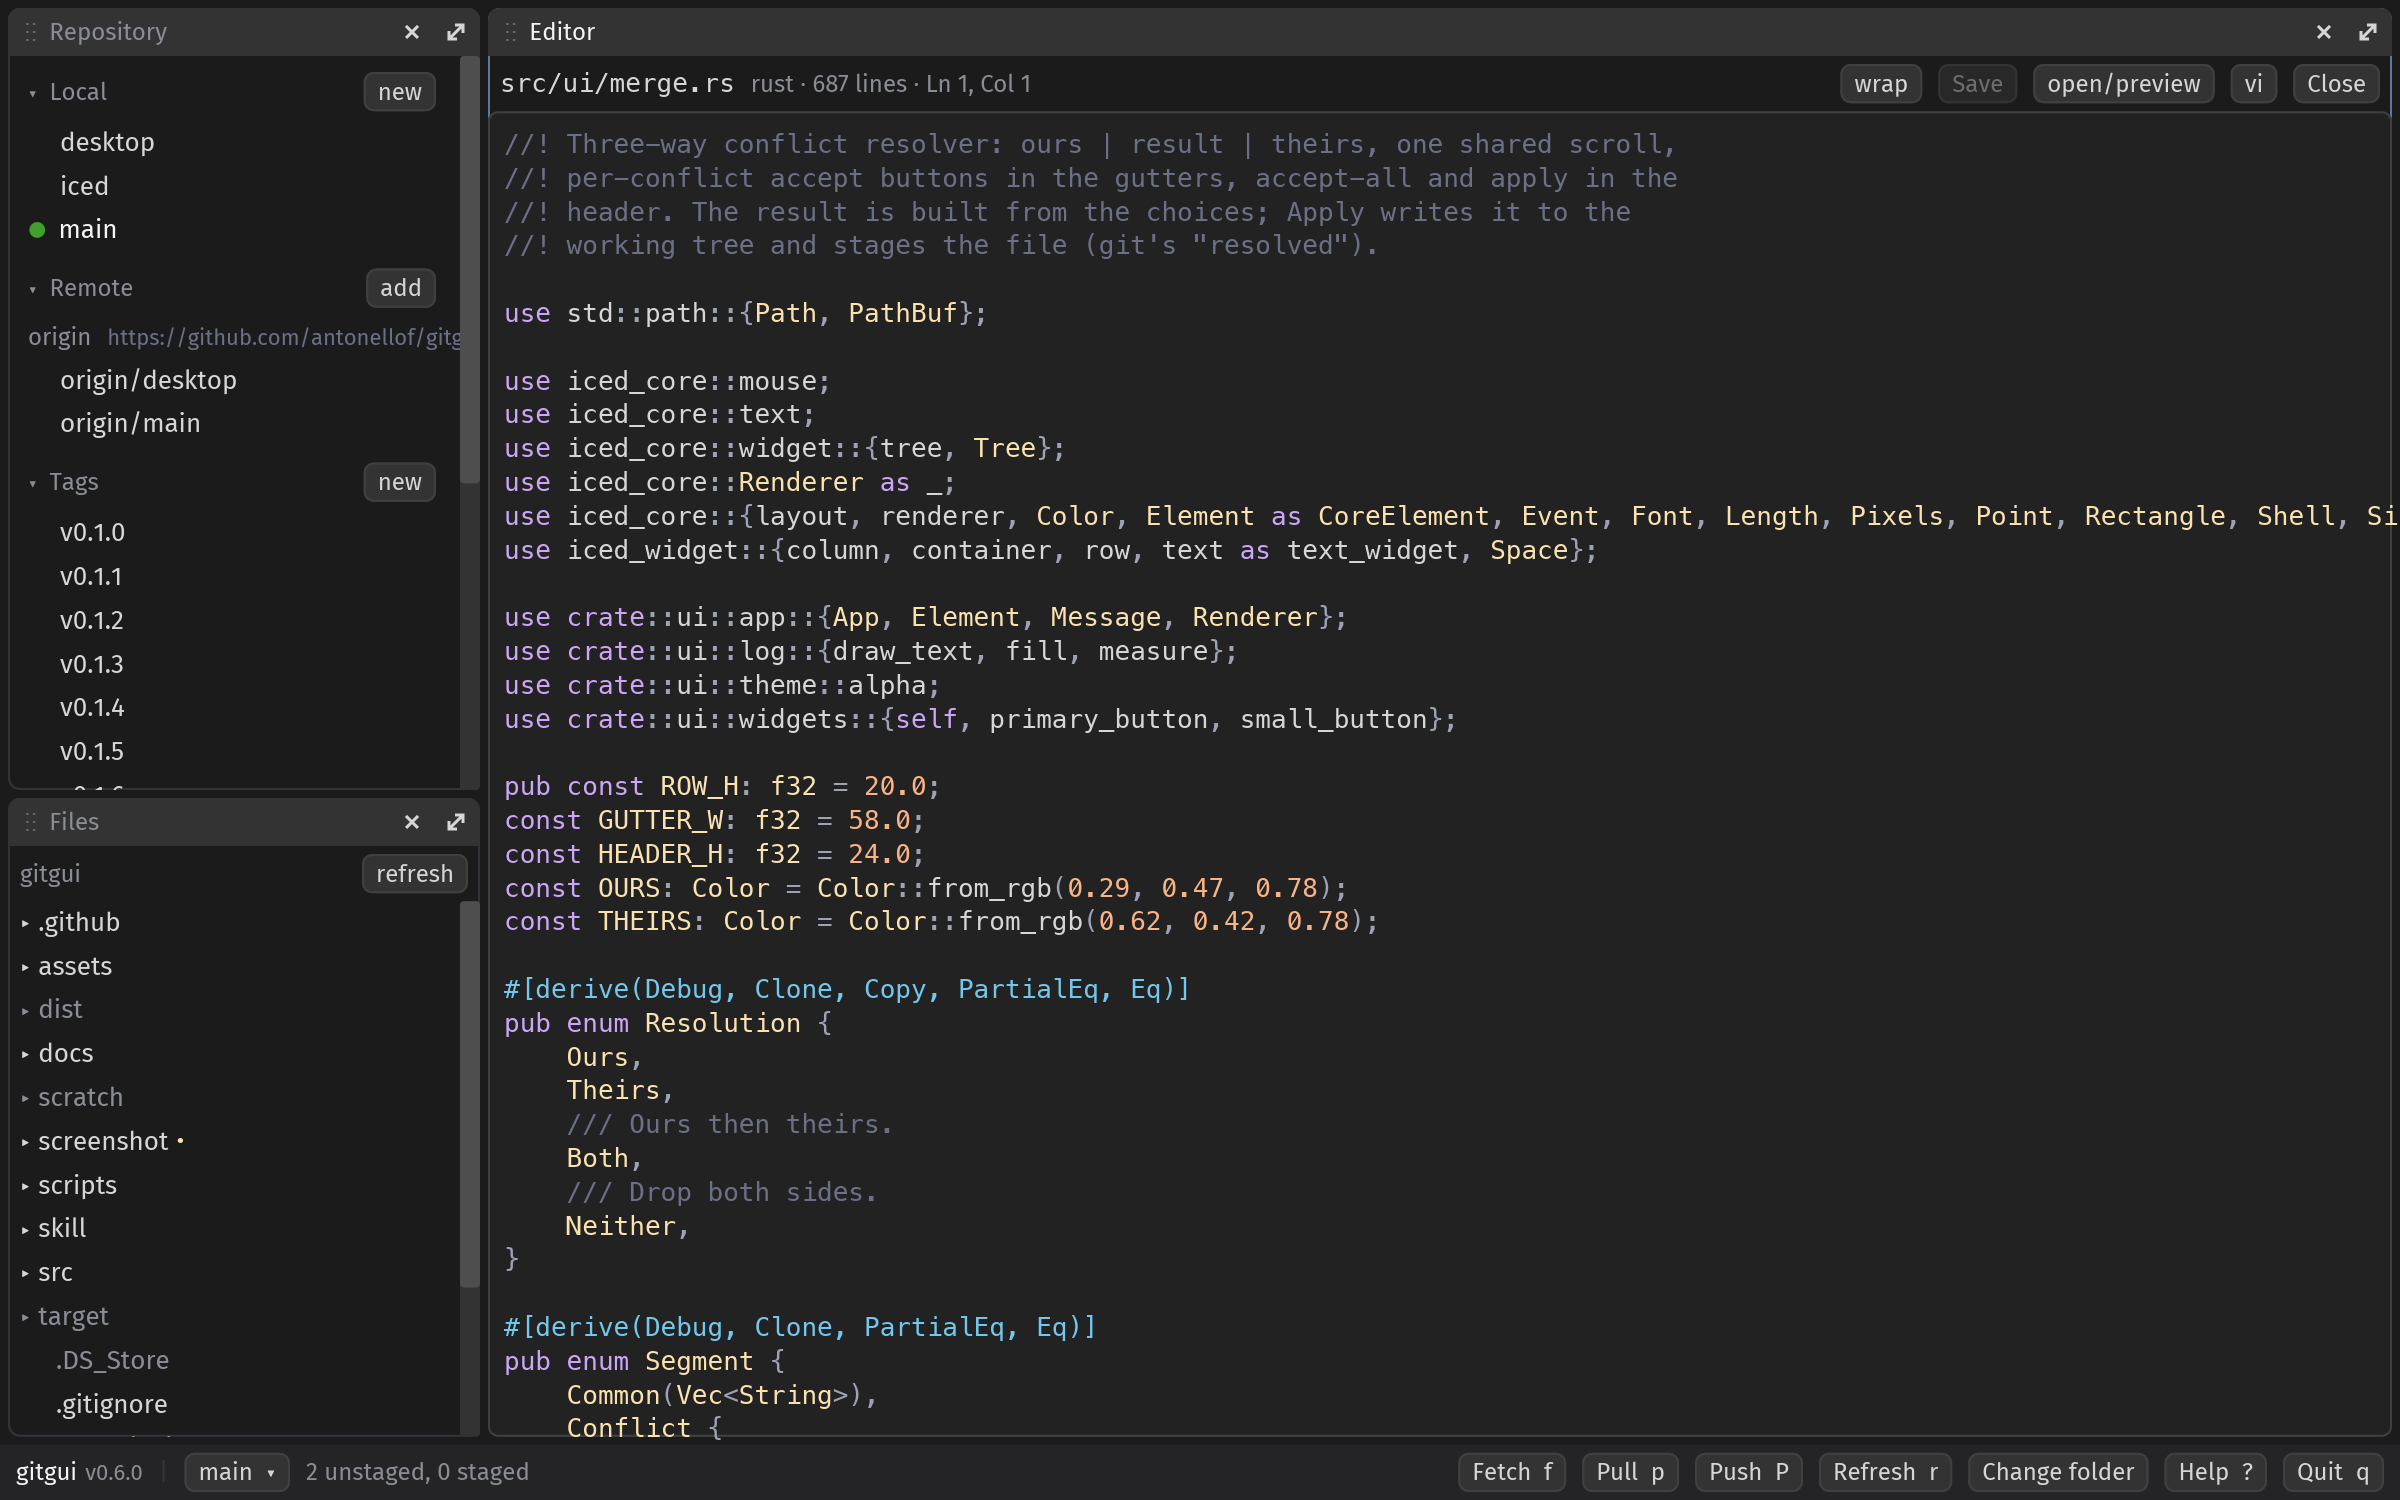
  <li><strong>Editor</strong> on iced’s text editor with syntax colors for the common languages, undo, <code class="language-plaintext highlighter-rouge">Ctrl+S</code>. <code class="language-plaintext highlighter-rouge">Shift+E</code> opens the file in your own editor in a new cmux split (<code class="language-plaintext highlighter-rouge">--editor</code>, <code class="language-plaintext highlighter-rouge">git config gitgui.editor</code>, <code class="language-plaintext highlighter-rouge">$EDITOR</code>; GUI editors like <code class="language-plaintext highlighter-rouge">code</code> open detached). <code class="language-plaintext highlighter-rouge">Shift+O</code> opens cmux’s file preview.</li>
</ul>

<p><img src="/assets/images/posts/gitgui-editor.png" alt="Built-in editor with syntax colors next to the repository sidebar" /></p>

<ul>
  <li><strong>Merge and rebase state</strong> in the footer with continue / abort / skip.</li>
  <li><strong>Change folder</strong> from the footer or <code class="language-plaintext highlighter-rouge">Ctrl+O</code>: a folder dialog with git repositories marked, so one gitgui pane follows you across projects. Zoom with <code class="language-plaintext highlighter-rouge">Ctrl+=</code> / <code class="language-plaintext highlighter-rouge">Ctrl+-</code>.</li>
  <li><strong>SHA-256 repositories</strong> (<code class="language-plaintext highlighter-rouge">git init --object-format=sha256</code>) open, diff and commit like any other; libgit2 is built with its SHA-256 support.</li>
  <li><strong>Branch switcher</strong>, publish to GitHub through <code class="language-plaintext highlighter-rouge">gh</code>, initialize a non-git folder, auto refresh every 2 s when the repo changes.</li>
  <li><strong>Agent socket</strong>: <code class="language-plaintext highlighter-rouge">gitgui ls</code>, <code class="language-plaintext highlighter-rouge">gitgui action '{"cmd":"status"}'</code>, so Pi or Cursor query status, select commits, stage paths, fetch, push, or save a PNG screenshot.</li>
</ul>

<p><img src="/assets/images/posts/gitgui-menu.png" alt="Commit menu: cherry-pick, revert, reset, reword, squash, fixup, drop, move" /></p>

<p>Keys are single letters and Ctrl combinations terminals do not steal. cmux keeps Cmd+*. <code class="language-plaintext highlighter-rouge">?</code> lists them all. Quit with q or Ctrl+C, or click Quit in the footer.</p>

<h2 id="and-outside-cmux-a-desktop-window">And outside cmux: a desktop window</h2>

<p>Not every terminal speaks kitty graphics. Terminal.app, iTerm2, the VS Code terminal, tmux. Since v0.6.0 the same binary notices that and opens a native window instead, still the same iced UI and the same tiny-skia renderer, through winit and softbuffer, no GPU. <code class="language-plaintext highlighter-rouge">gitgui --window</code> forces it, and <code class="language-plaintext highlighter-rouge">scripts/bundle-macos.sh</code> wraps it as <code class="language-plaintext highlighter-rouge">gitgui.app</code> with the logo as its icon, so it also launches from Finder. Started outside a repository it shows the logo and a Change folder button.</p>

<p>The terminal split, cmux’s file preview and agent screenshots stay terminal-only; keys, panes, the state file and the agent socket work the same.</p>

<h2 id="install">Install</h2>

<p>You need macOS or Linux. In a kitty-graphics terminal gitgui draws into the pane; anywhere else it opens a desktop window.</p>

<p>Quick start:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>curl <span class="nt">-fsSL</span> https://raw.githubusercontent.com/antonellof/gitgui/main/scripts/install.sh | bash
</code></pre></div></div>

<p>That one-liner works on public repos. Private repo? Clone with <code class="language-plaintext highlighter-rouge">gh</code> and run the script locally:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>gh repo clone antonellof/gitgui
<span class="nb">cd </span>gitgui
bash scripts/install.sh
</code></pre></div></div>

<p>Pin a release:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">GITGUI_VERSION</span><span class="o">=</span>0.6.0 bash scripts/install.sh
</code></pre></div></div>

<p>The script pulls a release binary when GitHub has one. Otherwise it builds from source with cargo (Rust 1.95+). Success looks like:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>installed: ~/.local/bin/gitgui

run in a kitty-graphics terminal (cmux, Ghostty, kitty):
  gitgui                  open repo in current directory
  gitgui /path/to/repo    open a specific repo
  gitgui --split right .  open in a new terminal split

quit with q or Ctrl+C
</code></pre></div></div>

<p>Check terminal support:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>gitgui <span class="nt">--probe</span>
</code></pre></div></div>

<h2 id="cmux--pi--gitgui">cmux + Pi + gitgui</h2>

<p>Same workspace as the trio post. One extra split.</p>

<p>Pane A, Pi:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">cd</span> ~/Projects/my-app
pi
</code></pre></div></div>

<p>Pane B, gitgui, from the agent pane:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>gitgui <span class="nt">--split</span> right <span class="nb">.</span>
</code></pre></div></div>

<p>cmux runs <code class="language-plaintext highlighter-rouge">new-split right</code> and <code class="language-plaintext highlighter-rouge">send</code> with the gitgui command. Or split by hand and type <code class="language-plaintext highlighter-rouge">gitgui</code> in the new pane.</p>

<p>Give your agent the skill file:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">mkdir</span> <span class="nt">-p</span> ~/.cursor/skills/gitgui
<span class="nb">ln</span> <span class="nt">-sf</span> ~/path/to/gitgui/skill/SKILL.md ~/.cursor/skills/gitgui/SKILL.md
</code></pre></div></div>

<p>Drive the GUI from the shell:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>gitgui <span class="nb">ls
</span>gitgui action <span class="s1">'{"cmd":"status"}'</span>
gitgui action <span class="s1">'{"cmd":"stage","paths":["src/main.rs"]}'</span>
gitgui action <span class="s1">'{"cmd":"fetch"}'</span>
gitgui action <span class="s1">'{"cmd":"commit_and_push","message":"fix layout"}'</span>
gitgui action <span class="s1">'{"cmd":"screenshot","path":"/tmp/frame.png"}'</span>
</code></pre></div></div>

<p>Run <code class="language-plaintext highlighter-rouge">action</code> from the pane where gitgui lives and it finds the instance via the controlling tty. Writes queue on a background git thread. Poll status until busy hits zero.</p>

<p>A typical session: Pi edits and runs tests on the left. gitgui auto-refreshes on the right. You stage hunks, click Commit or Commit &amp; Push, or use Ctrl+Enter / Ctrl+Shift+Enter. Switch branches from the status bar when Pi opens a feature branch. Or Pi stages through <code class="language-plaintext highlighter-rouge">gitgui action</code> and you type the commit message yourself.</p>

<h2 id="inside-the-binary">Inside the binary</h2>

<p>One Rust process. Three threads.</p>

<p>stdin reader blocks on terminal bytes and feeds a parser for kitty keys, SGR mouse, paste, resize.</p>

<p>main loop runs iced without a window: it builds the UI, feeds it the terminal events, applies the messages, and lets tiny-skia draw straight into the framebuffer that goes out as kitty graphics. The commit log, the diff and the conflict resolver are custom widgets that draw only their visible rows.</p>

<p>git worker uses libgit2 for reads and index writes. fetch, pull, and push shell out to <code class="language-plaintext highlighter-rouge">git</code> so your credential helper and SSH agent stay untouched. A background poll every 2 s refreshes the snapshot when files change on disk, so Pi edits show up without a manual refresh.</p>

<p>The UI reads an immutable RepoSnapshot. The worker swaps in a new snapshot after each command. Rendering never calls git.</p>

<p>iced 0.14 (<code class="language-plaintext highlighter-rouge">iced_core</code>, <code class="language-plaintext highlighter-rouge">iced_runtime</code>, <code class="language-plaintext highlighter-rouge">iced_widget</code>, <code class="language-plaintext highlighter-rouge">iced_renderer</code> on tiny-skia; the <code class="language-plaintext highlighter-rouge">iced</code> umbrella crate with winit only for the window mode), git2 with libgit2’s SHA-256 support, libc for termios and shm, serde for the agent API. No Electron. No GPU backend. No tokio. Spec and protocol bytes live in <a href="https://github.com/antonellof/gitgui/blob/main/docs/SPEC.md">docs/SPEC.md</a> and <a href="https://github.com/antonellof/gitgui/blob/main/docs/PROTOCOLS.md">docs/PROTOCOLS.md</a>.</p>

<h2 id="one-refactor-start-to-finish">One refactor, start to finish</h2>

<p>Pi touches three files. You want the graph to update, one hunk staged and one left alone, and a commit message you wrote yourself. All inside cmux.</p>

<p>Before gitgui: <code class="language-plaintext highlighter-rouge">git diff</code> in the shell for small diffs, Alt-Tab to Fork for a graph, lazygit when you want speed over pixels.</p>

<p>Now: <code class="language-plaintext highlighter-rouge">gitgui --split right .</code> once per session. Tab between Pi and gitgui. Edits from Pi land in the unstaged list within a couple of seconds. Stage one hunk, leave another, or select three lines and stage just those. Type a message, hit Commit &amp; Push, or fetch first from the footer. Need a feature branch? Click the branch name, pick from the list, stash if you have WIP. Merge came back with conflicts? Click Resolve, take a side per conflict, Apply, Continue. Want to fix a typo in a file Pi touched? Click it in the tree, edit, <code class="language-plaintext highlighter-rouge">Ctrl+S</code>.</p>

<p>cmux still rings when Pi waits on you. Mouse clicks hit the right widgets. SSH sessions use the direct transport and the same UI.</p>

<h2 id="what-it-still-skips">What it still skips</h2>

<p>cmux and Ghostty are the main targets. kitty works. tmux and Zellij do not pass kitty graphics through; there, and in any terminal without them, gitgui opens its desktop window instead of drawing into the pane.</p>

<p>Ghostty on macOS has no stable split-from-child API. <code class="language-plaintext highlighter-rouge">gitgui --split</code> prints a keybind hint and runs in the current pane when needed.</p>

<p>The editor has no line-number gutter yet, and the resolver’s result column is not editable in place: press Edit result to hand-edit the merged file.</p>

<p>If you already run cmux and Pi, gitgui is the git pane I wished existed. Install it, split right, keep the graph beside the harness.</p>

<hr />

<p>gitgui: <a href="https://github.com/antonellof/gitgui">github.com/antonellof/gitgui</a>. cmux: <a href="https://cmux.dev">cmux.dev</a>. Pi: <a href="https://pi.dev">pi.dev</a>. Related: <a href="/2026/cmux-pi-unsloth-local-glm-setup/">The Local Agent Trio: cmux + Pi + Unsloth Studio</a>.</p>]]></content><author><name>Antonello Fratepietro</name><email>antonello.f at gmail dot com</email></author><category term="How-To" /><category term="gitgui" /><category term="cmux" /><category term="Pi Agent" /><category term="Git" /><category term="Rust" /><category term="iced" /><category term="kitty graphics" /><category term="macOS" /><category term="Agentic AI" /><summary type="html"><![CDATA[I wanted a Sourcetree-class git GUI in the same cmux window as my coding agent. gitgui v0.6.0 renders pixels in the terminal with Rust and iced: draggable panes, a three-way conflict resolver, a code editor, history rewriting, and a desktop window wherever the terminal has no graphics. Pi drives it over a Unix socket.]]></summary></entry><entry><title type="html">Ferrox on Metal: at parity with llama.cpp, and past it</title><link href="https://www.fratepietro.com/2026/ferrox-metal-parity-llama-cpp/" rel="alternate" type="text/html" title="Ferrox on Metal: at parity with llama.cpp, and past it" /><published>2026-08-24T00:00:00+02:00</published><updated>2026-08-24T00:00:00+02:00</updated><id>https://www.fratepietro.com/2026/ferrox-metal-parity-llama-cpp</id><content type="html" xml:base="https://www.fratepietro.com/2026/ferrox-metal-parity-llama-cpp/"><![CDATA[<p><img src="/assets/images/ferrox/ferrox-logo.webp" alt="Ferrox" width="380" /></p>

<p><a href="https://github.com/antonellof/ferrox">Ferrox</a> is a pure-Rust inference engine for GGUF models. Dense and mixture-of-experts, on CPU, Apple Metal, or CUDA. No bindings to llama.cpp, no wrapper around ggml. You get a CLI with llama.cpp-style flags and an OpenAI-compatible HTTP server you point your existing tools at.</p>

<p>I wrote it for one reason. I want mixture-of-experts models running on machines too small to hold them in VRAM, with expert-level residency rather than layer offload: watch which experts fire, keep those resident, evict the rest. Doing that well means designing the router, the KV cache, and the memory manager together. Every speed claim gets pinned against llama.cpp on the same machine, same file, same backend.</p>

<p>The <a href="/2026/ferrox-rust-gguf-inference-engine/">first post</a> covers the design. This one covers what changed since.</p>

<p><em>Kept current with the <a href="https://github.com/antonellof/ferrox/releases/latest">latest release</a>. Since this went up: Metal passed llama.cpp on decode as well as prefill, speculative decoding stays lossless at any temperature, streams survive a dropped connection, and one binary now does every job. Those are at the end.</em></p>

<h2 id="moe-prefill-on-metal-got-24x-faster">MoE prefill on Metal got 2.4x faster</h2>

<p>OLMoE-1B-7B went from 587 tok/s to 1402 tok/s on 512-token prefill. Against llama.cpp on the same machine and the same file, the gap closed from 2.62x behind to 1.11x.</p>

<p><em>Where it stands at v0.12.0, re-measured in one session with a warmup rep: OLMoE prefill is 1.09x and its decode is at parity.</em></p>

<p>Ferrox runs a whole transformer layer inside one Metal command encoder. Dense layers already joined this fused stack. MoE layers did not, so each one paid host-side projections, a separate command buffer for attention, a round trip to the CPU to pick experts, and another command buffer to run them. Roughly 112 command buffers per prefill.</p>

<p>MoE layers now live in the same stack. Two kernels were missing and are new: a router GEMM for F32 weights, which every MoE GGUF ships, and a batched top-k softmax. The old one handled a single token at a time, which suits decode and wastes a 512-token prompt.</p>

<p>Decode improved too. Profiling found the expert router taking 3.6 ms of 8.5 ms per token, more than the experts it selects. Two of my own kernels ran serial work on a chip with thousands of lanes. Rewriting them dropped GPU time per token by 25 percent.</p>

<p>The same work extended the flash-attention kernel to 256-dimension heads. The biggest single winner was Qwen3-0.6B: 1936 tok/s to 3400 tok/s.</p>

<h2 id="the-measurement-i-was-most-wrong-about">The measurement I was most wrong about</h2>

<p>The decode work left a note in my plan saying the remaining 2.4 ms per token went on barriers, roughly eight per layer. So I replaced the blanket barriers with a hazard tracker that synchronises only the memory ranges a kernel touches, ported from ggml.</p>

<p>Worth about 1 percent. The reason is the useful part.</p>

<p>Barrier counts came out at 0.99 per tracked operation before and after. A single-token decode layer is a strict dependency chain, so a range tracker has nothing to overlap and only narrows each barrier’s scope. The arithmetic agrees: Llama-3.2-1B at Q4_K_M is 0.8 GB, and 6.1 ms per token works out to 130 GB/s against the M2 Pro’s 200 GB/s. Decode is already limited by weight bandwidth, not by synchronisation.</p>

<p>My own earlier note was wrong. I wrote that into the plan so the next attempt captures the attention kernel instead of touching synchronisation again.</p>

<p>Verifying the change took 54 runs of the CPU-versus-Metal check across dense, MoE, sliding-window and QK-norm models at four prompt lengths. A missing barrier is a race. One green run proves nothing.</p>

<h2 id="try-it">Try it</h2>

<p>The only build flag you need is your GPU. Everything else is in the binary, and that binary is 19 MB with no interpreter or wheels under it.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>cargo <span class="nb">install </span>ferrox-cli <span class="nt">--features</span> metal

<span class="c"># Same argument shape as `hf download`, and no Python involved.</span>
ferrox download bartowski/Llama-3.2-3B-Instruct-GGUF <span class="se">\</span>
  Llama-3.2-3B-Instruct-Q4_K_M.gguf <span class="nt">--local-dir</span> models

<span class="c"># Chat model. Ferrox applies the checkpoint's own chat template.</span>
ferrox <span class="nt">-m</span> models/Llama-3.2-3B-Instruct-Q4_K_M.gguf <span class="se">\</span>
  <span class="nt">-p</span> <span class="s2">"Explain quantization in two sentences"</span> <span class="nt">-n</span> 128 <span class="nt">-dev</span> metal <span class="nt">-ngl</span> all

<span class="c"># Raw completion, no chat wrapping.</span>
ferrox <span class="nt">-m</span> models/Llama-3.2-3B-Instruct-Q4_K_M.gguf <span class="se">\</span>
  <span class="nt">-p</span> <span class="s2">"The capital of France is"</span> <span class="nt">-n</span> 32 <span class="nt">--temp</span> 0 <span class="nt">--no-cnv</span>

<span class="c"># OpenAI-compatible server on 127.0.0.1:8383.</span>
ferrox serve <span class="nt">-m</span> models/Llama-3.2-3B-Instruct-Q4_K_M.gguf <span class="nt">-dev</span> metal <span class="nt">-ngl</span> all

<span class="c"># Benchmark against llama-bench, side by side.</span>
ferrox bench <span class="nt">-m</span> models/Llama-3.2-3B-Instruct-Q4_K_M.gguf <span class="nt">-p</span> 512 <span class="nt">-n</span> 128 <span class="nt">-r</span> 3 <span class="nt">--compare</span>
</code></pre></div></div>

<p>Point any OpenAI client at <code class="language-plaintext highlighter-rouge">http://127.0.0.1:8383/v1</code> and it works. Anthropic Messages and Responses live on the same server, so <code class="language-plaintext highlighter-rouge">codex</code> and Anthropic-shaped clients work without a shim.</p>

<p>The engine publishes as <code class="language-plaintext highlighter-rouge">ferrox-inference</code>, since the name <code class="language-plaintext highlighter-rouge">ferrox</code> belongs to an unrelated crate. Twelve crates, all live, all sharing one version. Take the facade for the whole stack, or <code class="language-plaintext highlighter-rouge">ferrox-gguf</code> alone if you only want to read GGUF files.</p>

<div class="language-toml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">[</span><span class="n">dependencies</span><span class="k">]</span>
<span class="n">ferrox-inference</span> <span class="o">=</span><span class="w"> </span><span class="s">"0.13"</span>
</code></pre></div></div>

<h2 id="where-ferrox-beats-llamacpp">Where Ferrox beats llama.cpp</h2>

<p>Decode on Metal at v0.12.0, same M2 Pro, same GGUF, both engines measured in one session with a warmup rep and the host load recorded at both ends. Ratio is llama divided by ferrox, so under 1.0 means Ferrox is faster.</p>

<table>
  <thead>
    <tr>
      <th>Model</th>
      <th>ferrox tok/s</th>
      <th>llama.cpp tok/s</th>
      <th>Ratio</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Qwen2.5-0.5B Q8_0</td>
      <td>212.92</td>
      <td>131.24</td>
      <td>0.62x</td>
    </tr>
    <tr>
      <td>SmolLM2-135M Q8_0</td>
      <td>332.37</td>
      <td>219.63</td>
      <td>0.66x</td>
    </tr>
    <tr>
      <td>Qwen3-0.6B Q8_0</td>
      <td>165.68</td>
      <td>116.92</td>
      <td>0.71x</td>
    </tr>
    <tr>
      <td>TinyLlama-1.1B Q8_0</td>
      <td>127.49</td>
      <td>98.89</td>
      <td>0.78x</td>
    </tr>
    <tr>
      <td>Gemma-3-1B Q8_0</td>
      <td>96.51</td>
      <td>83.36</td>
      <td>0.86x</td>
    </tr>
    <tr>
      <td>Phi-4-mini Q4_K_M</td>
      <td>51.97</td>
      <td>47.98</td>
      <td>0.92x</td>
    </tr>
    <tr>
      <td>Llama-3.2-1B IQ4_XS</td>
      <td>160.14</td>
      <td>148.44</td>
      <td>0.93x</td>
    </tr>
  </tbody>
</table>

<p>Eight of the twelve Metal decode rows are ahead of llama.cpp and the other four sit within 3 percent of it, so no Metal row is red any more. Qwen2.5-0.5B runs 62 percent faster. Small models gain most, because the per-token fixed cost dominates and that is where the fused Metal stack pays off. Prefill closed too: every dense <code class="language-plaintext highlighter-rouge">pp512</code> row lands between 0.98x and 1.10x.</p>

<p>CPU is the other story, and Ferrox loses across it: all 16 comparable rows land between 1.41x and 5.06x. The cause is measured and the fix is written, waiting on a clean benchmark window. Full table either way in <a href="https://github.com/antonellof/ferrox/blob/main/benchmarks/RESULTS.md">benchmarks/RESULTS.md</a>, generated from checked-in raw timings rather than typed by hand.</p>

<h2 id="new-model-support">New model support</h2>

<p>gpt-oss runs on CPU, with attention sinks, alternating sliding-window attention, a biased router, and the swiglu clamp. I checked every layer against reference logits from llama.cpp rather than against my reading of the spec.</p>

<p>The low-bit quantization tiers landed: IQ2_XS, IQ2_S, IQ3_S, and IQ1_M. IQ3_S matters most, since IQ3_M mixes are largely made of it. All four decode bit-exact against llama.cpp’s own dequantization. F16 checkpoints load now as well, which they never did before.</p>

<p>Phi-4-mini runs correctly on CPU and Metal. Partial rotary, LongRoPE factor sets and rope attention scaling all work, and the Metal RoPE kernels took <code class="language-plaintext highlighter-rouge">rot_dim</code> and <code class="language-plaintext highlighter-rouge">mscale</code> uniforms so the GPU path stopped being refused. A second bug turned up on the way: <code class="language-plaintext highlighter-rouge">rope_freqs</code> was sized by the head width instead of by <code class="language-plaintext highlighter-rouge">n_rot</code>.</p>

<p>Rotary embeddings now use the right layout for 24 more architectures, including exaone, nemotron, starcoder2, minicpm3, openelm, plamo, and dots1. Getting this wrong produces plausible text with subtly wrong attention, so I pinned the whole table against llama.cpp’s reference with a test. Measured against golden logits, error dropped from 1.1e-2 to 1e-6.</p>

<h2 id="chat-templates-come-from-the-checkpoint">Chat templates come from the checkpoint</h2>

<p>Ferrox used to sniff a model into one of six families and render an approximation. Anything outside those six fell back to plain text, and tool-calling formats were unreachable.</p>

<p>Every GGUF already carries its chat template as a Jinja string, so Ferrox evaluates that instead. Four real templates lifted from actual checkpoints are pinned in tests with exact expected output.</p>

<p><em>Update: this section originally said half of it shipped, with the evaluator written and no call site using it. Both front ends run it now. A checkpoint whose family nobody hand-wrote a renderer for is framed the way it was trained, and <code class="language-plaintext highlighter-rouge">chat_template_kwargs</code> and <code class="language-plaintext highlighter-rouge">reasoning_effort</code> pass through to it. The effort is quantized onto the gears that checkpoint actually grades, probed from its own template at load rather than read from a table keyed by model name.</em></p>

<p>One consequence I had not thought about: plenty of templates emit the BOS token themselves, and Unsloth strips it from the ones it bakes into a GGUF. Whether a loader double-adds BOS becomes a property of the checkpoint rather than of the code. I measured it across 26 local checkpoints instead of reasoning about it. Zero doubled today, but only because every prepend site had a guard. Remove the guard and 6 of the 26 double.</p>

<h2 id="ferrox-studio">Ferrox Studio</h2>

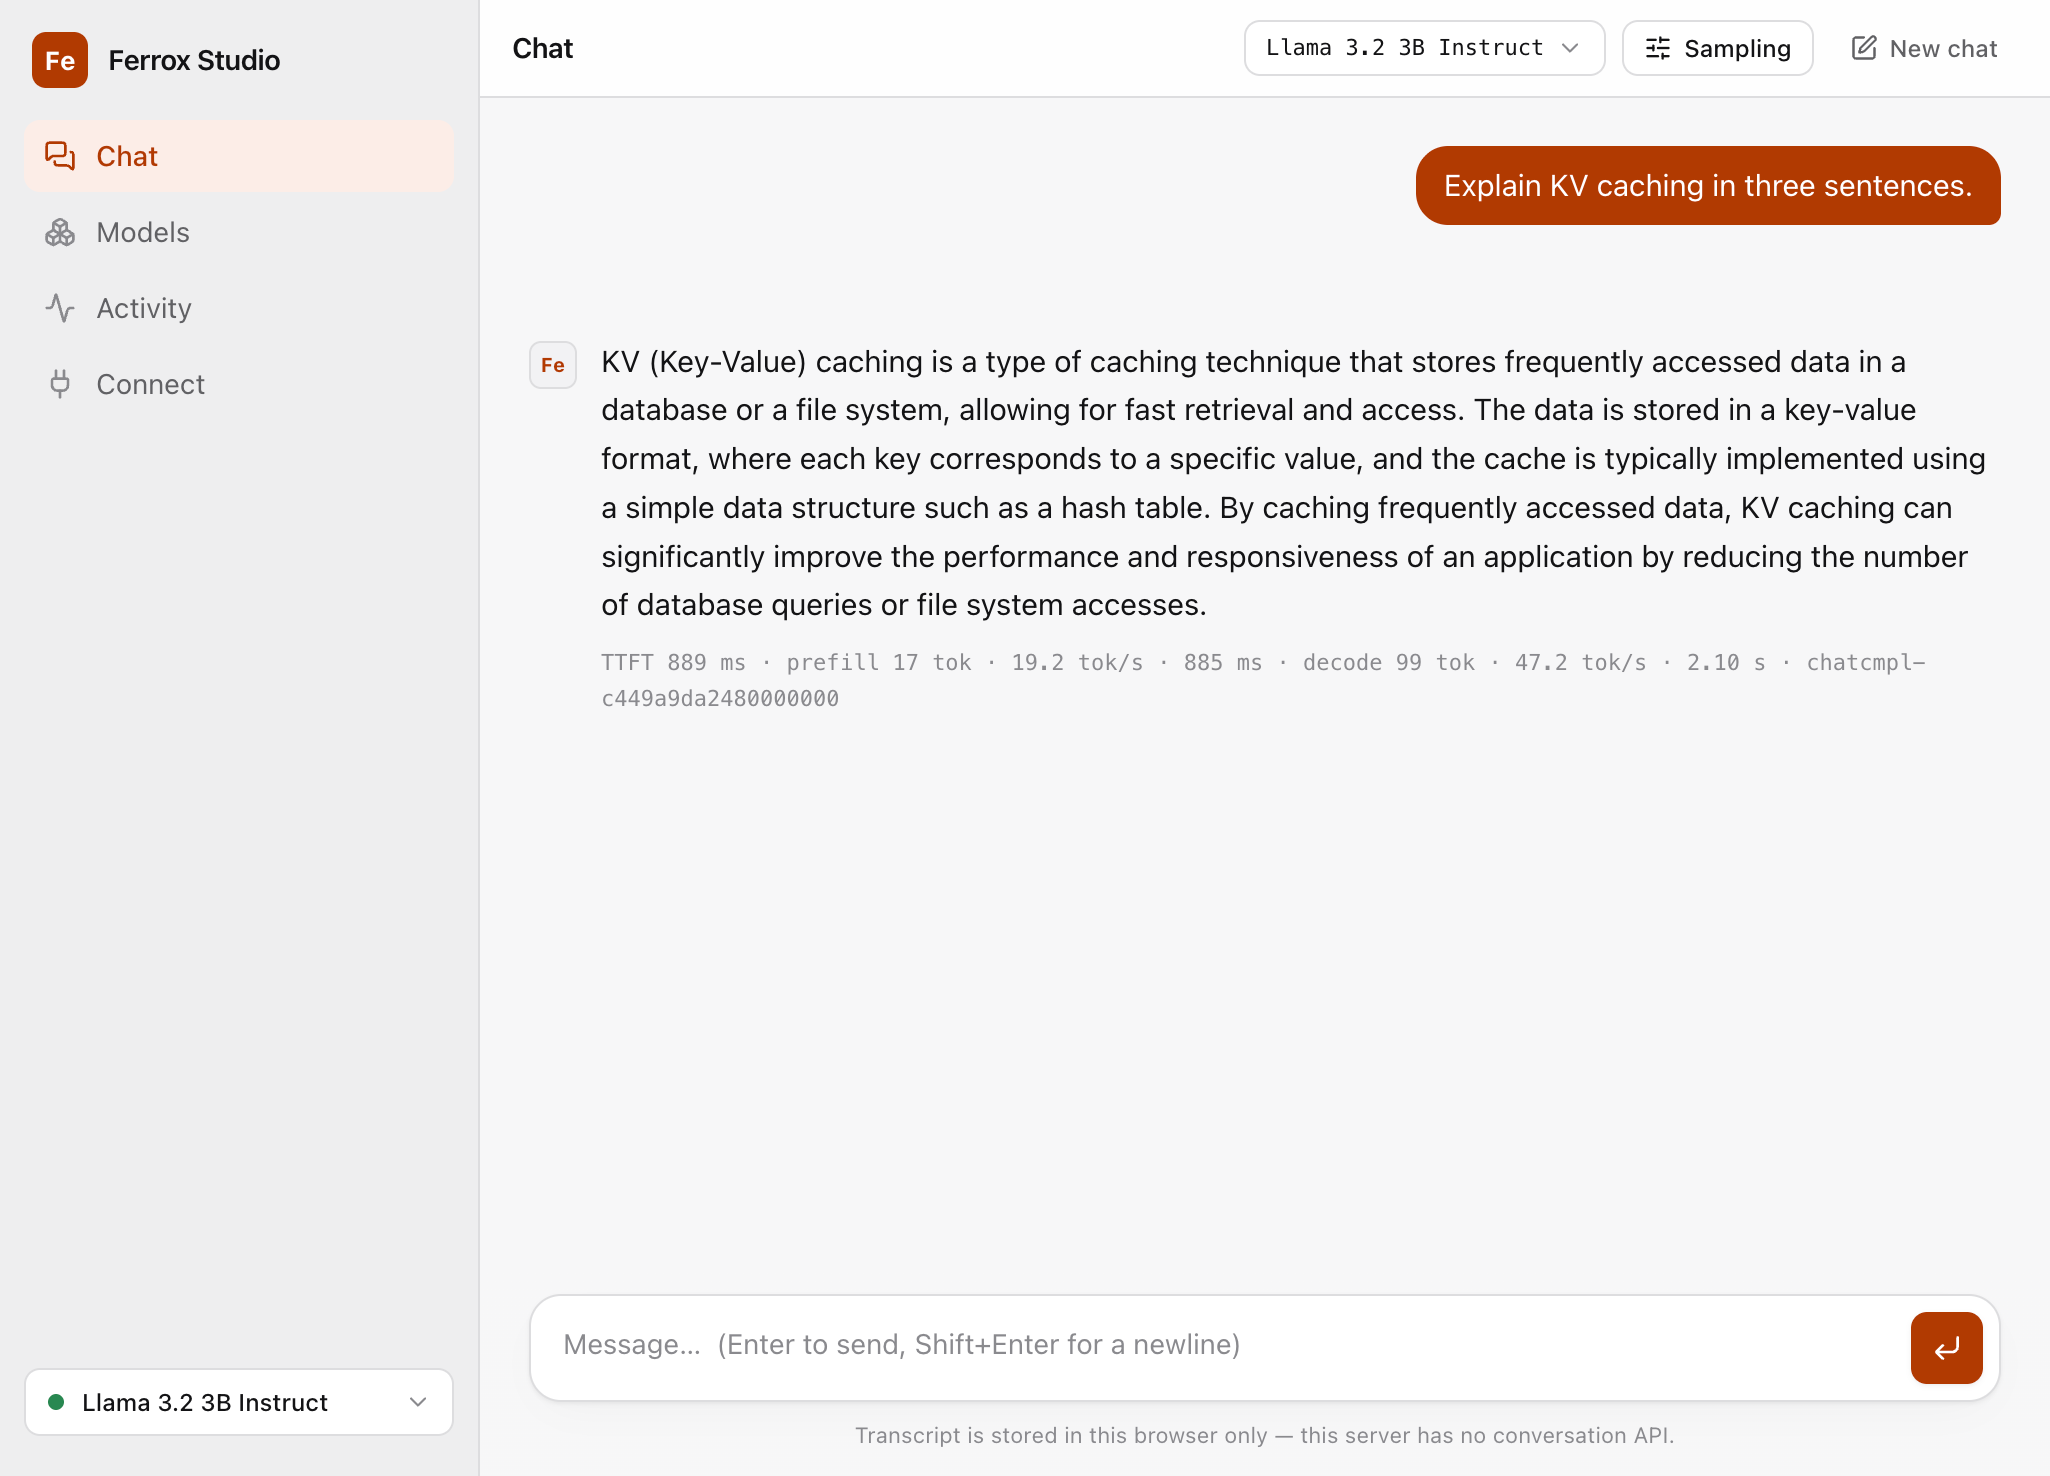
<p><img src="/assets/images/ferrox/ferrox-studio-chat.png" alt="Ferrox Studio chat screen: a sidebar with Chat, Models, Activity and Connect, a model selector reading Llama 3.2 3B Instruct, and an answer about KV caching with a stat line underneath reading TTFT 889 ms, prefill 17 tok at 19.2 tok/s, decode 99 tok at 47.2 tok/s" /></p>

<p>A web UI ships alongside the server, rebuilt this week on React, Tailwind, and assistant-ui: streaming chat with markdown and code blocks, a model manager, a live request log, and a Connect screen generating curl and Python snippets from your running server.</p>

<p>It runs as its own app rather than inside the server binary. <code class="language-plaintext highlighter-rouge">npm run dev</code> in <code class="language-plaintext highlighter-rouge">ui/</code> proxies to the API, so the server serves the API and nothing else.</p>

<p>Every screen goes through the public HTTP API, so anything the UI does, your own client does too. The stats under each answer come from the server’s own timings rather than a browser stopwatch, so time-to-first-token and decode rate are the real numbers. That is the grey line under the answer above: <code class="language-plaintext highlighter-rouge">TTFT 889 ms · prefill 17 tok · 19.2 tok/s · decode 99 tok · 47.2 tok/s</code>, from a 3B on Metal.</p>

<p>Model output never becomes markup. I seeded an answer containing a script tag, an image with an onerror handler, and a javascript: link, then checked the DOM: zero script or image elements, no globals set, the link href emptied, all three shown as text.</p>

<h2 id="serving-under-real-load">Serving under real load</h2>

<p>The parts deciding whether a server behaves with several clients at once:</p>

<ul>
  <li>Chunked prefill as a resumable state machine, so a long prompt stops stalling replies already in flight.</li>
  <li>Admission on an integer KV block budget instead of a byte watermark, with strict FIFO so a large request cannot starve behind small ones.</li>
  <li>Cancellation drained at a step boundary, so a cancelled row leaves through the same exit every row uses rather than being ripped out mid-batch.</li>
  <li>Stop sequences in two layers, matching single tokens by id before detokenization.</li>
  <li>A radix tree over reference-counted KV pages, so two conversations sharing a system prompt share its pages instead of copying them per request.</li>
  <li>Queue depth capped with a 503 and a Retry-After, so retry storms cannot grow memory without bound.</li>
</ul>

<p>Models load, unload, and swap at runtime. A request already running finishes against the weights it started with.</p>

<h2 id="two-tools-worth-stealing">Two tools worth stealing</h2>

<p><code class="language-plaintext highlighter-rouge">ferrox parity</code> compares first-token logit distributions against llama.cpp’s own library. Greedy text comparison does not work for this, because ordinary floating-point drift flips one near-tied token and everything after it differs. Comparing distributions separates a wrong graph from a rounding difference.</p>

<p><code class="language-plaintext highlighter-rouge">ferrox bench</code> refuses to time a run on a busy machine. Known-good rows read 25 to 45 percent low under load, wider than most gaps worth chasing. The load average now goes into every receipt, and a run above the bar stops rather than publishing noise.</p>

<p>The loader also refuses checkpoints it cannot compute. It records every tensor name a loader reads and fails the load on leftovers, so a model needing a graph feature Ferrox lacks gets a clear refusal instead of confident wrong tokens.</p>

<h2 id="what-is-next">What is next</h2>

<p>Ranked, with measurements attached, in <a href="https://github.com/antonellof/ferrox/tree/main/docs/plans">docs/plans</a>:</p>

<ul>
  <li>CPU decode, the widest remaining gap. The cause is measured: Rayon forks and joins per operation while llama.cpp runs a persistent thread pool. A replacement pool is written and waiting on a clean benchmark window.</li>
  <li>CPU prefill. The blocked attention kernel is 53 percent of non-idle samples on SmolLM2 against roughly 8 percent of the model’s FLOPs, because pass one does a dot product per query per KV position with no K reuse across the query block.</li>
  <li><a href="https://inco.ai/blog/dflash2/">dFlash</a> speculative decoding, where a drafter emits a whole block of tokens in one pass instead of one at a time.</li>
  <li>AMD Strix Halo, where a large unified memory pool suits keeping MoE experts resident.</li>
</ul>

<p>Every speed number gets measured against llama.cpp on the same host, same file, same backend. If there is no receipt, the table says so. I do not invent numbers.</p>

<h2 id="shipped-since-this-was-written">Shipped since this was written</h2>

<p>Six things landed after this post went up.</p>

<p><strong>Speculative decoding is lossless at any temperature.</strong> It used to accept a draft token only when the target’s argmax matched, which is correct at temperature 0 and quietly wrong above it. Verification now uses the speculative-sampling rejection rule. Drafters plug in through a <code class="language-plaintext highlighter-rouge">Drafter</code> trait, and acceptance length plus the per-position accept rate are reported, so a drafter that decays toward the end of a block shows up instead of being averaged away.</p>

<p><strong>Streams survive a dropped connection.</strong> <code class="language-plaintext highlighter-rouge">GET /v1/stream/{request_id}</code> replays with Last-Event-ID, and there is a polling sibling for proxies that buffer SSE. Two features collided here and only one of them wins: an orphan deadline cancels generation when nobody has read for 30 seconds, and a resumable stream exists precisely so a dropped socket does not cancel. The deadline still detects and logs, and only cancels streams that are not resumable.</p>

<p><strong>The server prices its KV budget before loading.</strong> Weights plus context times per-token KV against the device budget, with <code class="language-plaintext highlighter-rouge">FERROX_CB_MAX_CONTEXT</code> and <code class="language-plaintext highlighter-rouge">FERROX_CB_KV_BLOCKS</code> derived when unset. A request that cannot fit gets a typed 400 naming which ceiling binds, rather than an OOM later.</p>

<p><strong>One binary does every job.</strong> <code class="language-plaintext highlighter-rouge">cargo install ferrox-cli --features metal</code> now gives you completions, <code class="language-plaintext highlighter-rouge">ferrox serve</code>, <code class="language-plaintext highlighter-rouge">ferrox download</code>, <code class="language-plaintext highlighter-rouge">ferrox bench</code> and <code class="language-plaintext highlighter-rouge">ferrox verify</code>. There is no feature flag to discover beyond your GPU. I had kept <code class="language-plaintext highlighter-rouge">serve</code> behind a flag to spare a completion-only user 98 crates and a C crypto library, and that rule was costing more than it saved: it had already put a false claim in the README, and it was hiding a headline capability where nobody would find it. <code class="language-plaintext highlighter-rouge">ferrox-server</code> stays published for anyone who wants the server alone.</p>

<p><strong>Fetching a model needs no Python.</strong> <code class="language-plaintext highlighter-rouge">ferrox download</code> takes <code class="language-plaintext highlighter-rouge">hf download</code>’s exact argument shape, so a command copied off a model card runs unchanged. It resolves IPv4 first, because Hugging Face publishes AAAA records that black-hole on some networks, reads <code class="language-plaintext highlighter-rouge">HF_TOKEN</code> for gated repos, and asks for a byte range so an interrupted download resumes. Bytes land on a <code class="language-plaintext highlighter-rouge">.partial</code> name and are renamed only after the last one arrives, so the loader never opens a truncated file as a whole GGUF.</p>

<p><strong>A model too large for the machine is refused before it loads,</strong> naming the checkpoint’s size, the memory available, and what expert streaming would cost. I shipped the opposite first: streaming turned itself on when the weights did not fit. Then OLMoE answered “Paris.” resident and “amongst amongst, and of” streamed, deterministically, at temperature 0. Auto-enabling was withdrawn the same day. Streaming stays an explicit opt-in until it returns the right tokens, because “your model does not fit” is a bad outcome and “your model answers nonsense” is a much worse one.</p>

<h2 id="ai-full-disclosure">AI full disclosure</h2>

<p>This software is developed with strong assistance from Cursor, Grok 4.5, GPT 5.6, and Claude Fable 5, with humans leading the ideas, testing, and debugging. We say this openly because it shaped how the project was built. If you are not happy with AI-developed code, this software is not for you. The acknowledgement below is equally important: this would not exist without <a href="https://github.com/ggerganov/llama.cpp">llama.cpp</a> and GGML, largely written by hand.</p>

<h2 id="acknowledgements-to-llamacpp-and-ggml">Acknowledgements to llama.cpp and GGML</h2>

<p>Ferrox does not link against GGML, but exists thanks to the path opened by the llama.cpp project and the kernels, quantization formats, GGUF ecosystem, and hard-won engineering knowledge developed there. Half of this work is “I read how llama.cpp did it and ported the idea”, which is deliberate and is the project’s default method. We are thankful and indebted to llama.cpp and its contributors. Some source-level pieces are retained or adapted here under the MIT license, notably IQ quantization codebook tables, and many other pieces were written independently against that public design. We keep the GGML authors’ copyright notice in <a href="https://github.com/antonellof/ferrox/blob/main/docs/THIRD_PARTY_NOTICES.md">docs/THIRD_PARTY_NOTICES.md</a>.</p>

<h2 id="closing">Closing</h2>

<p>Ferrox is Apache-2.0. Try it, and open an issue with the GGUF name, the backend, and your <code class="language-plaintext highlighter-rouge">ferrox bench</code> output if something runs slow or wrong.</p>

<ul>
  <li><a href="https://github.com/antonellof/ferrox">github.com/antonellof/ferrox</a></li>
  <li><a href="https://github.com/antonellof/ferrox/releases/latest">latest release</a></li>
  <li><a href="https://crates.io/crates/ferrox-inference">ferrox-inference on crates.io</a></li>
  <li><a href="https://github.com/antonellof/ferrox/blob/main/benchmarks/RESULTS.md">benchmarks/RESULTS.md</a></li>
  <li><a href="/2026/ferrox-rust-gguf-inference-engine/">the first post</a>, on why the engine exists</li>
</ul>]]></content><author><name>Antonello Fratepietro</name><email>antonello.f at gmail dot com</email></author><category term="Projects" /><category term="Rust" /><category term="AI" /><category term="LLM" /><category term="Local Inference" /><category term="Performance" /><category term="Metal" /><category term="MoE" /><summary type="html"><![CDATA[How the Metal backend in my pure-Rust GGUF engine caught llama.cpp and went past it: MoE prefill 2.4x faster, a fused command encoder, and the measurement I was most wrong about.]]></summary></entry><entry><title type="html">Ferrox: a Rust GGUF engine, measured against llama.cpp</title><link href="https://www.fratepietro.com/2026/ferrox-rust-gguf-inference-engine/" rel="alternate" type="text/html" title="Ferrox: a Rust GGUF engine, measured against llama.cpp" /><published>2026-08-05T00:00:00+02:00</published><updated>2026-08-05T00:00:00+02:00</updated><id>https://www.fratepietro.com/2026/ferrox-rust-gguf-inference-engine</id><content type="html" xml:base="https://www.fratepietro.com/2026/ferrox-rust-gguf-inference-engine/"><![CDATA[<p><img src="/assets/images/ferrox/ferrox-logo.webp" alt="Ferrox" width="380" /></p>

<p><em>Written August 2026, at v0.4. Ferrox has moved a long way since, so the sections below carry update notes where the numbers changed.</em></p>

<p>I built <a href="https://github.com/antonellof/ferrox">Ferrox</a> over the last couple of weeks. It is a pure-Rust inference engine for GGUF models: dense and MoE, on CPU, Apple Metal, or CUDA. No bindings to llama.cpp. No wrapper around ggml.</p>

<h2 id="where-ferrox-is-now">Where Ferrox is now</h2>

<p>Many releases later, the <a href="https://github.com/antonellof/ferrox/releases/latest">current one</a> is published on <a href="https://crates.io/crates/ferrox-inference">crates.io</a>. The short version:</p>

<ul>
  <li><strong>Metal caught llama.cpp and went past it.</strong> Every dense <code class="language-plaintext highlighter-rouge">pp512</code> row sits between 0.98× and 1.10×, and 8 of the 12 <code class="language-plaintext highlighter-rouge">tg128</code> rows are faster. CPU is still behind on all 16 comparable rows, 1.41× to 5.06×.</li>
  <li>One binary does everything: completions, <code class="language-plaintext highlighter-rouge">ferrox serve</code> for the OpenAI and Anthropic compatible API, <code class="language-plaintext highlighter-rouge">ferrox download</code>, <code class="language-plaintext highlighter-rouge">ferrox bench</code>, <code class="language-plaintext highlighter-rouge">ferrox verify</code>. The only build flag you need is your GPU.</li>
  <li><code class="language-plaintext highlighter-rouge">ferrox download</code> fetches a model with <code class="language-plaintext highlighter-rouge">hf download</code>’s exact syntax, so a command copied off a model card runs unchanged. No Python.</li>
  <li>Twelve real checkpoints answer correctly on Metal, two of them MoE.</li>
  <li>A web UI, Ferrox Studio, running as its own app against the same public API any other client uses.</li>
  <li>Published as <code class="language-plaintext highlighter-rouge">ferrox-inference</code>, with every layer available on its own if you want the GGUF reader and nothing else.</li>
</ul>

<p>The middle of that stretch has its own post: <a href="/2026/ferrox-metal-parity-llama-cpp/">Ferrox on Metal</a>.</p>

<h2 id="why-another-engine">Why another engine</h2>

<p>llama.cpp is excellent. I am not trying to catch up with every feature it has.</p>

<p>What I want is MoE on machines that cannot fit the whole model in VRAM. Not layer offload. Expert-level residency: watch which experts fire during decode, keep those resident, evict the rest. To do that well the router, the KV cache and the memory manager have to be designed together. That is about the only good reason to write a runtime from scratch. If you only need “run a Llama GGUF on my Mac”, use llama.cpp.</p>

<h2 id="what-it-does-today">What it does today</h2>

<p>One binary with flags close to llama.cpp (<code class="language-plaintext highlighter-rouge">-m</code>, <code class="language-plaintext highlighter-rouge">-p</code>, <code class="language-plaintext highlighter-rouge">-n</code>, <code class="language-plaintext highlighter-rouge">-ngl</code>, <code class="language-plaintext highlighter-rouge">--ctk</code>, …). <code class="language-plaintext highlighter-rouge">ferrox serve</code> starts the HTTP server from the same executable, and <code class="language-plaintext highlighter-rouge">ferrox-server</code> still ships on its own for anyone who prefers two.</p>

<p><em>Update: this originally listed two binaries. <code class="language-plaintext highlighter-rouge">serve</code> is a default feature now, so one <code class="language-plaintext highlighter-rouge">cargo install</code> gets completions, the server, the downloader, bench and verify. The server answers Anthropic Messages and Responses beside the OpenAI routes.</em></p>

<p>That binary is 19 MB, or 14 MB stripped, with no runtime under it. No interpreter, no virtualenv, no wheels to resolve, nothing to activate before you can run a model. It sits in the same ballpark as llama.cpp’s own core, which is 14 MB of executables and shared libraries on this Mac. Against the Python serving stacks it is a different category: PyTorch alone measures 402 MB here, and vLLM sits on top of that.</p>

<p>Weights stay quantized on mmap. Dequant happens inside the matmul, not as a separate pass. Same idea as llama.cpp, which is why an 8B model fits on a laptop without thirty gigabytes of RAM.</p>

<p>Verified families, meaning a real checkpoint answered correctly and stopped, not merely “it loads”: Llama 3.x, TinyLlama, SmolLM2, Qwen2.5/Qwen3, Gemma-2/3/4, Phi-4-mini, Mistral-7B, Yi, DeepSeek-R1 distills, OLMoE and Qwen1.5-MoE. gpt-oss runs on CPU. MLA / DeepSeek-style stacks are partial.</p>

<p>That is about twelve architectures with evidence behind them, out of 150 rows in the catalog. The rest refuse to load, naming the tensor or the hyperparameter they need, or are marked unproven. I chose that. llama.cpp hand-writes 140 per-architecture graphs, and that hand-written work is the whole reason its coverage is wider than mine. Until Ferrox has done the same work for a family, it stops with an error rather than running a graph that is merely close enough to compile and handing back fluent text computed the wrong way. A refusal you can read is coverage. Confident wrong tokens are not.</p>

<h2 id="build-download-run">Build, download, run</h2>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># --features metal on Apple silicon, cuda on Linux + NVIDIA, nothing on CPU.</span>
cargo <span class="nb">install </span>ferrox-cli <span class="nt">--features</span> metal

<span class="c"># Same argument shape as `hf download`, without the Python.</span>
ferrox download bartowski/Llama-3.2-1B-Instruct-GGUF <span class="se">\</span>
  Llama-3.2-1B-Instruct-Q4_K_M.gguf <span class="nt">--local-dir</span> models

<span class="c"># Ferrox wraps the prompt in the checkpoint's own chat template.</span>
ferrox <span class="nt">-m</span> models/Llama-3.2-1B-Instruct-Q4_K_M.gguf <span class="se">\</span>
  <span class="nt">-p</span> <span class="s2">"What is 2+2?"</span> <span class="nt">-n</span> 64 <span class="nt">--temp</span> 0 <span class="nt">-dev</span> metal <span class="nt">-ngl</span> all

<span class="c"># Serve on 127.0.0.1:8383 and point any OpenAI client at /v1.</span>
ferrox serve <span class="nt">-m</span> models/Llama-3.2-1B-Instruct-Q4_K_M.gguf <span class="nt">-dev</span> metal <span class="nt">-ngl</span> all
</code></pre></div></div>

<p>The <a href="https://github.com/antonellof/ferrox">README</a> lists known-good GGUFs to start from. Prefer <code class="language-plaintext highlighter-rouge">Q4_K_M</code> day to day, <code class="language-plaintext highlighter-rouge">Q8_0</code> for tiny tests. On Metal, <code class="language-plaintext highlighter-rouge">--ctk q8_0</code> shrinks the KV cache if you need longer context.</p>

<p>A model too large for the machine is refused before it loads, naming the checkpoint’s size, the memory you have, and what expert streaming would cost. Streaming is opt-in: it is slower than keeping experts resident, and it still returns wrong tokens on real MoE checkpoints. Running out of memory is a bad outcome. Answering nonsense is a worse one.</p>

<h2 id="numbers-with-receipts">Numbers, with receipts</h2>

<p>I do not trust speed claims without a method. <code class="language-plaintext highlighter-rouge">ferrox bench</code> runs the same <code class="language-plaintext highlighter-rouge">pp512</code> prefill and <code class="language-plaintext highlighter-rouge">tg128</code> decode workloads as <code class="language-plaintext highlighter-rouge">llama-bench</code>, on the same Mac (M2 Pro), the same GGUF and the same backend. Every run writes a JSON file of raw timings, those files are checked into the repo, and <a href="https://github.com/antonellof/ferrox/blob/main/benchmarks/RESULTS.md"><code class="language-plaintext highlighter-rouge">benchmarks/RESULTS.md</code></a> is generated from them rather than typed by hand. Gap = <code class="language-plaintext highlighter-rouge">llama / ferrox</code>. Under 1.0 means Ferrox is faster.</p>

<p>Engine decode on Metal, M2 Pro, measured at v0.12.0 in a single session:</p>

<table>
  <thead>
    <tr>
      <th>Model</th>
      <th>tg128 Ferrox</th>
      <th>tg128 llama.cpp</th>
      <th>Gap</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Llama-3.2-3B Q4_K_M</td>
      <td>62.7</td>
      <td>64.7</td>
      <td>1.03×</td>
    </tr>
    <tr>
      <td>Llama-3.2-1B Q4_K_M</td>
      <td>149.4</td>
      <td>149.7</td>
      <td>1.00×</td>
    </tr>
    <tr>
      <td>OLMoE-1B-7B Q4_0</td>
      <td>152.0</td>
      <td>151.6</td>
      <td>1.00×</td>
    </tr>
    <tr>
      <td>Mistral-7B Q4_K_M</td>
      <td>32.9</td>
      <td>32.4</td>
      <td>0.99×</td>
    </tr>
    <tr>
      <td>Gemma-3-1B Q8_0</td>
      <td>96.5</td>
      <td>83.4</td>
      <td>0.86×</td>
    </tr>
    <tr>
      <td>Qwen2.5-0.5B Q8_0</td>
      <td>212.9</td>
      <td>131.2</td>
      <td>0.62×</td>
    </tr>
  </tbody>
</table>

<p>Metal is at or past llama.cpp on both tests. Every dense <code class="language-plaintext highlighter-rouge">pp512</code> row lands between 0.98× and 1.10×, 8 of the 12 <code class="language-plaintext highlighter-rouge">tg128</code> rows are ahead, and no Metal row is red. OLMoE reaches parity on prefill and decode as well, so MoE is no longer the column I did not want to publish.</p>

<p>CPU is the whole remaining gap, and Ferrox loses across it: all 16 comparable rows land between 1.41× and 5.06×. The cause is measured. Rayon forks and joins per operation while llama.cpp runs a persistent thread pool, and Ferrox is ahead at a single thread on Mistral-7B, so it scales badly rather than computing slowly. A replacement pool is written and waiting on a clean benchmark window.</p>

<p>Re-run it yourself:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ferrox bench <span class="nt">--suite</span> <span class="nt">--fit-host</span> <span class="nt">--skip-missing</span>
</code></pre></div></div>

<p>It stops rather than time a run on a machine too busy, too hot, or too short on memory for the number to mean anything. If there is no receipt, the table says so. I do not invent numbers.</p>

<h2 id="what-i-learned-so-far">What I learned so far</h2>

<p>A few things that stuck, after many evenings staring at tok/s:</p>

<ul>
  <li><strong>Decode and prefill are different problems.</strong> Getting tg128 to parity did not make pp512 follow. Prefill needed its own answer: simdgroup-MMA flash attention, batched GEMM, and a fused command encoder that runs a whole layer without returning to the host.</li>
  <li><strong>MoE Metal needs its own path.</strong> A dense kernel wearing a MoE costume loses. Expert placement, <code class="language-plaintext highlighter-rouge">mul_mm_id</code> and fused encode groups took OLMoE to parity on both tests.</li>
  <li><strong>Fair comparison is harder than it looks.</strong> Forcing both engines to the same thread count made llama.cpp look worse on this Mac, because it already prefers performance cores. The suite no longer forces <code class="language-plaintext highlighter-rouge">-t</code>.</li>
  <li><strong>CUDA was quietly broken.</strong> <code class="language-plaintext highlighter-rouge">--features cuda</code> on the CLI did not enable CUDA in <code class="language-plaintext highlighter-rouge">ferrox-core</code>. Prefill never hit the GPU.</li>
</ul>

<p><em>Update: CUDA compiles and runs, and nobody has benchmarked it. No pinned host, no receipts, so treat a Windows or Linux install as CPU-only in practice. Saying that plainly in the docs was easier than pretending otherwise.</em></p>

<p>None of this is glamorous. It is the work.</p>

<h2 id="what-is-next">What is next</h2>

<p>From the <a href="https://github.com/antonellof/ferrox/blob/main/docs/ROADMAP.md">roadmap</a>:</p>

<ol>
  <li>CPU, the widest remaining gap, with the persistent thread pool ready to measure.</li>
  <li>Run bigger models on the same hardware (Qwen3 35B-A3B-class on a box that today only likes 8B). Expert streaming has to return the right tokens first.</li>
  <li>Hybrid CPU/GPU expert placement, and tighter KV.</li>
  <li>CUDA tuning. It builds and runs, with no serious pass yet.</li>
  <li>Grammar and JSON-schema constrained decoding, Docker images.</li>
</ol>

<p>If you want to point an IDE or agent at the local server, there is a short cookbook: <a href="https://github.com/antonellof/ferrox/blob/main/docs/AGENTS_COOKBOOK.md"><code class="language-plaintext highlighter-rouge">docs/AGENTS_COOKBOOK.md</code></a>.</p>

<h2 id="ai-full-disclosure">AI full disclosure</h2>

<p>This software is developed with strong assistance from Cursor, Grok 4.5, GPT 5.6, and Claude Fable 5, with humans leading the ideas, testing, and debugging. We say this openly because it shaped how the project was built. If you are not happy with AI-developed code, this software is not for you.</p>

<p>The acknowledgement below is equally important: this would not exist without llama.cpp and GGML, largely written by hand.</p>

<h2 id="acknowledgements-to-llamacpp-and-ggml">Acknowledgements to llama.cpp and GGML</h2>

<p>Ferrox does not link against GGML, but it exists thanks to the path opened by the <a href="https://github.com/ggml-org/llama.cpp">llama.cpp</a> project and the kernels, quantization formats, GGUF ecosystem, and hard-won engineering knowledge developed there. We are thankful and indebted to llama.cpp and its contributors. Their implementation, kernels, tests, and design choices were an essential reference while building this pure-Rust GGUF / MoE inference path.</p>

<p>Some source-level pieces are retained or adapted here under the MIT license, notably IQ quantization codebook tables, and many other pieces (GGUF layouts, quant/dot semantics, CLI and server conventions) were written independently against that public design. For this reason, and because we are genuinely grateful, we keep the GGML authors’ copyright notice in <a href="https://github.com/antonellof/ferrox/blob/main/docs/THIRD_PARTY_NOTICES.md"><code class="language-plaintext highlighter-rouge">docs/THIRD_PARTY_NOTICES.md</code></a>.</p>

<h2 id="closing">Closing</h2>

<p>Ferrox is Apache-2.0. Stars are nice. PRs and failed pins are more useful. If you try it and something is slow or wrong, open an issue with the GGUF name, backend, and the <code class="language-plaintext highlighter-rouge">ferrox bench</code> output.</p>

<p><strong>Links</strong></p>
<ul>
  <li><a href="https://github.com/antonellof/ferrox">github.com/antonellof/ferrox</a></li>
  <li><a href="https://crates.io/crates/ferrox-inference">ferrox-inference on crates.io</a></li>
  <li><a href="https://github.com/antonellof/ferrox/blob/main/benchmarks/RESULTS.md">benchmarks/RESULTS.md</a></li>
  <li><a href="https://github.com/antonellof/ferrox/blob/main/docs/FEATURES.md">docs/FEATURES.md</a></li>
  <li><a href="https://github.com/antonellof/ferrox/blob/main/docs/MODELS.md">docs/MODELS.md</a></li>
  <li><a href="https://github.com/antonellof/ferrox/blob/main/docs/THIRD_PARTY_NOTICES.md">docs/THIRD_PARTY_NOTICES.md</a></li>
  <li><a href="https://news.ycombinator.com/item?id=49180302">HN discussion</a></li>
</ul>]]></content><author><name>Antonello Fratepietro</name><email>antonello.f at gmail dot com</email></author><category term="Projects" /><category term="Rust" /><category term="AI" /><category term="LLM" /><category term="Local Inference" /><category term="Performance" /><summary type="html"><![CDATA[I built Ferrox, a pure-Rust GGUF inference engine. Not to replace llama.cpp, but to get MoE expert residency right, and every speed claim is pinned against llama.cpp on the same machine.]]></summary></entry><entry><title type="html">Rondine: Hardware-Aware Local LLM Serving Without the Flag Archaeology</title><link href="https://www.fratepietro.com/2026/rondine-hardware-aware-local-llm-launcher/" rel="alternate" type="text/html" title="Rondine: Hardware-Aware Local LLM Serving Without the Flag Archaeology" /><published>2026-07-22T00:00:00+02:00</published><updated>2026-07-22T00:00:00+02:00</updated><id>https://www.fratepietro.com/2026/rondine-hardware-aware-local-llm-launcher</id><content type="html" xml:base="https://www.fratepietro.com/2026/rondine-hardware-aware-local-llm-launcher/"><![CDATA[<p>Running a local language model is easy right up until you want it to run <em>well</em>. Downloading weights is only the beginning. You still have to choose an inference engine, pick a quantization that fits, reserve enough memory for the KV cache, decide on a useful context length, and translate all of that into a collection of backend-specific flags.</p>

<p>Those choices change with every machine. A good setup for a 24 GB MacBook is not a good setup for a 256 GB Mac Studio. An RTX 4090 should not be configured like an H100, and a DGX Spark has its own Blackwell-specific path.</p>

<p><a href="https://github.com/antonellof/rondine"><strong>Rondine</strong></a> is an open-source, hardware-aware control plane for this problem. It detects the machine, recommends models that fit, builds an optimized serving plan, downloads the selected weights, and starts an OpenAI-compatible local server.</p>

<p>It does not implement another inference engine. Rondine drives the mature engines that already exist:</p>

<ul>
  <li><strong>MLX-LM</strong> or <strong>llama.cpp</strong> on Apple Silicon</li>
  <li><strong>llama.cpp</strong> or <strong>vLLM</strong> on discrete NVIDIA GPUs</li>
  <li><strong>vLLM</strong> or <strong>llama.cpp</strong> on DGX Spark / GB10</li>
  <li>Native engine launchers for homogeneous multi-node experiments</li>
</ul>

<p>The goal is simple: go from <em>“which model and which flags?”</em> to a repeatable local endpoint without hiding the decisions being made.</p>

<h2 id="the-workflow">The workflow</h2>

<p>A complete setup is a short sequence of commands:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git clone https://github.com/antonellof/rondine.git
<span class="nb">cd </span>rondine
uv tool <span class="nb">install</span> <span class="nb">.</span>

rondine doctor
rondine suggest <span class="nt">--profile</span> coding
rondine suggest <span class="nt">--configure</span> 1 <span class="nt">--save-as</span> coding
rondine setup
rondine pull
rondine serve <span class="nt">--preset</span> coding
rondine verify <span class="nt">--profile</span> coding
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">doctor</code> probes the host: operating system, architecture, RAM, GPU VRAM, CUDA capability, and installed engines. <code class="language-plaintext highlighter-rouge">suggest</code> combines that inventory with Rondine’s model catalog and hardware profiles. The selected plan can be saved as a named preset, so restarting the same configuration later is one command:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine serve <span class="nt">--preset</span> coding
</code></pre></div></div>

<p>Every suggestion includes the resolved engine settings. Rondine is automation, not a black box: the model, quantization, context, batch sizes, memory settings, and launch command remain inspectable.</p>

<h2 id="recommendations-based-on-the-hardware-you-actually-have">Recommendations based on the hardware you actually have</h2>

<p>Model selection starts with fit. On NVIDIA systems, Rondine sizes against <strong>GPU VRAM</strong>, not total system RAM. On Apple Silicon, it accounts for unified memory. It then ranks viable variants using the requested profile, provider preference, quantization quality, and available headroom.</p>

<p>The current catalog includes a practical range of coding models:</p>

<table>
  <thead>
    <tr>
      <th>Hardware class</th>
      <th>Example recommendation</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Apple Silicon, 24–48 GB</td>
      <td>Qwen3.6 27B or Gemma 4 12B</td>
    </tr>
    <tr>
      <td>Apple Silicon, 36 GB+</td>
      <td>Qwen3.6 35B-A3B</td>
    </tr>
    <tr>
      <td>NVIDIA, 24 GB VRAM</td>
      <td>Qwen3.6 35B-A3B or Qwen3.6 27B</td>
    </tr>
    <tr>
      <td>Apple Silicon, 128 GB</td>
      <td>DeepSeek-V4-Flash at 3-bit, opt-in</td>
    </tr>
    <tr>
      <td>Apple Silicon, 256 GB</td>
      <td>GLM-5.2 <code class="language-plaintext highlighter-rouge">UD-IQ2_M</code>, opt-in</td>
    </tr>
    <tr>
      <td>DGX Spark / GB10</td>
      <td>NVFP4 models through vLLM where available</td>
    </tr>
  </tbody>
</table>

<p>These are starting points rather than universal declarations of the “best” model. A coding workload, an interactive chat session, and a long-context document task have different latency and memory requirements. Rondine makes that trade-off explicit through profiles and dry runs.</p>

<p>You can inspect a launch without downloading or starting anything:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine serve qwen3.6-27b <span class="nt">--profile</span> coding <span class="nt">--dry-run</span>
</code></pre></div></div>

<p>If the curated catalog does not contain what you need, Hub discovery is built into the workflow:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine search <span class="s2">"Qwen3.6 35B GGUF"</span>
rondine inspect org/model-repo
rondine plan org/model-repo <span class="nt">--quant</span> Q4_K_M <span class="nt">--save-as</span> custom-model
</code></pre></div></div>

<h2 id="glm-52-an-example-where-configuration-matters">GLM-5.2: an example where configuration matters</h2>

<p>GLM-5.2 illustrates why a hardware-aware launcher is useful. It is a frontier-scale Mixture-of-Experts coding model: roughly 744B total parameters with about 40B active per token. The active parameter count helps compute efficiency, but the complete quantized weights still have to live somewhere.</p>

<p>Rondine’s preferred single-machine variant is Unsloth’s <code class="language-plaintext highlighter-rouge">UD-IQ2_M</code> GGUF:</p>

<ul>
  <li>Approximately <strong>239 GB</strong> of model weights</li>
  <li>At least <strong>245 GB</strong> of usable unified memory recommended</li>
  <li><strong>llama.cpp</strong> as the serving engine</li>
  <li>A practical <strong>32K coding context</strong> by default</li>
  <li>Thinking enabled with model-specific sampling</li>
  <li>Intended for a <strong>256 GB Mac Studio-class machine</strong></li>
</ul>

<p>There is also a smaller <code class="language-plaintext highlighter-rouge">UD-IQ1_S</code> option at roughly 223 GB, but the more aggressive quantization is a quality trade-off. Official BF16 weights belong on a large multi-GPU or multi-node system, not a single workstation.</p>

<p>Rondine marks GLM-5.2 as opt-in. A 48 GB Mac will not receive a recommendation merely because the model is fashionable, and a plan that does not fit is rejected rather than launched into an avoidable out-of-memory failure.</p>

<p>The same logic applies at smaller scales. On a 24 GB machine, choosing a model with enough headroom for context and cache is usually more useful than loading the largest possible file and leaving no memory for real work.</p>

<h2 id="engine-specific-tuning">Engine-specific tuning</h2>

<p>The user-facing plan is consistent, but the settings under it are specific to each backend.</p>

<p>For <strong>llama.cpp</strong>, Rondine can configure:</p>

<ul>
  <li>GPU layer offload</li>
  <li>Flash attention</li>
  <li>Batch and micro-batch sizes</li>
  <li>KV-cache quantization</li>
  <li>Parallel request slots</li>
  <li>Context length and sampling options</li>
</ul>

<p>For <strong>MLX-LM</strong>, it selects MLX model variants and applies Apple Silicon-specific runtime settings, including Metal synchronization behavior.</p>

<p>For <strong>vLLM</strong>, it manages settings such as:</p>

<ul>
  <li>GPU memory utilization</li>
  <li>Maximum model length</li>
  <li>Prefix caching</li>
  <li>Tensor parallelism when explicitly enabled</li>
  <li>Blackwell / DGX Spark-oriented model formats such as NVFP4</li>
</ul>

<p>Configuration is resolved from layered templates: engine defaults, the requested usage profile, and the detected hardware class. This keeps the policy understandable while avoiding a separate hand-written command for every model and machine combination.</p>

<h2 id="a-local-openai-compatible-endpoint">A local OpenAI-compatible endpoint</h2>

<p>Once <code class="language-plaintext highlighter-rouge">rondine serve</code> starts the backend, clients connect through the familiar OpenAI API format:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>http://127.0.0.1:8080/v1
</code></pre></div></div>

<p>That makes the server usable from existing applications and coding clients without introducing a Rondine-specific protocol. A basic request looks like this:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>curl http://127.0.0.1:8080/v1/chat/completions <span class="se">\</span>
  <span class="nt">-H</span> <span class="s2">"Content-Type: application/json"</span> <span class="se">\</span>
  <span class="nt">-d</span> <span class="s1">'{
    "model": "rondine/qwen3.6-35b-a3b",
    "messages": [
      {"role": "user", "content": "Review this Python function for race conditions."}
    ]
  }'</span>
</code></pre></div></div>

<p>You can point Cursor, Continue, Aider, Codex CLI, Claude Code with a custom base URL, or another OpenAI-compatible tool at the same endpoint. Rondine owns the model-serving lifecycle; the coding client remains replaceable.</p>

<p>Binding to <code class="language-plaintext highlighter-rouge">127.0.0.1</code> also keeps the default exposure local. If you deliberately make an inference server reachable over a LAN, treat it as a network service: use a trusted network, authentication or a reverse proxy, and an appropriate firewall policy.</p>

<h2 id="a-coding-profile-not-a-coding-agent-lock-in">A coding profile, not a coding-agent lock-in</h2>

<p>Rondine’s <code class="language-plaintext highlighter-rouge">coding</code> profile is scoped to inference. It applies a practical context length and model-specific sampling, enables reasoning where supported, and tunes the engine for sustained code-oriented requests.</p>

<p>The profile currently includes model-aware behavior such as:</p>

<ul>
  <li>Qwen3.6 thinking mode and coding sampling defaults</li>
  <li>GLM-5.2 maximum reasoning effort</li>
  <li>DeepSeek-V4-Flash high reasoning effort</li>
  <li>Engine-level batching, cache, and memory settings appropriate to the host</li>
</ul>

<p>After launch, <code class="language-plaintext highlighter-rouge">rondine verify --profile coding</code> checks server health and runs coding-oriented smoke tests. This catches the frustrating class of failure where a process is listening on a port but the loaded model, chat template, or generation path is not actually usable.</p>

<p>Rondine deliberately does <strong>not</strong> ship a proprietary agent loop. Repository access, tool execution, approvals, edits, and planning belong to the coding client. The server remains a standard local model endpoint rather than coupling inference to one editor or one agent framework.</p>

<h2 id="presets-make-experiments-repeatable">Presets make experiments repeatable</h2>

<p>Local inference experiments often end with an excellent command buried in shell history. Rondine presets preserve the complete plan:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine preset list
rondine preset show coding
rondine preset serve coding
</code></pre></div></div>

<p>That matters when comparing models. A coding preset can favor reasoning and a larger context, while a chat preset can use a smaller context and disable thinking for lower latency. Both remain named, inspectable, and reproducible.</p>

<p>It also makes the setup easier to explain to another developer. Instead of sharing a multi-line backend command with hardware assumptions embedded in it, you can share the model plan and let Rondine resolve the appropriate engine configuration on the target machine.</p>

<h2 id="what-rondine-isand-is-not">What Rondine is—and is not</h2>

<p>Rondine is intentionally a thin layer:</p>

<ol>
  <li>Detect the host.</li>
  <li>Match it to a hardware profile.</li>
  <li>Rank compatible model variants.</li>
  <li>Resolve engine-specific settings.</li>
  <li>Download, serve, save, and verify the plan.</li>
</ol>

<p>It is not a replacement for llama.cpp, MLX-LM, or vLLM. It is not a model manager that pretends every backend has identical capabilities. It is not a distributed inference orchestrator for a heterogeneous datacenter, and it is not another coding agent.</p>

<p>That limited scope is the design. Local inference already has excellent engines and clients. The missing layer is often the small, boring, hardware-specific control plane between them.</p>

<h2 id="try-it">Try it</h2>

<p>Rondine requires Python 3.11+ and is released under Apache-2.0:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git clone https://github.com/antonellof/rondine.git
<span class="nb">cd </span>rondine
uv tool <span class="nb">install</span> <span class="nb">.</span>
rondine doctor
rondine suggest <span class="nt">--profile</span> coding
</code></pre></div></div>

<p>The repository includes the model catalog, hardware templates, coding-client documentation, and engine-tuning notes:</p>

<ul>
  <li><a href="https://github.com/antonellof/rondine">Rondine on GitHub</a></li>
  <li><a href="https://github.com/antonellof/rondine/blob/main/docs/coding.md">Coding client guide</a></li>
  <li><a href="https://github.com/antonellof/rondine/blob/main/docs/engine-tuning.md">Engine tuning</a></li>
</ul>

<p>I am particularly interested in feedback from people running unusual configurations: high-memory Macs, 24–80 GB NVIDIA workstations, DGX Spark, and homogeneous two-node setups. Model catalogs age quickly; transparent hardware profiles and reproducible serving plans are the parts intended to last.</p>]]></content><author><name>Antonello Fratepietro</name><email>antonello.f at gmail dot com</email></author><category term="AI Infrastructure" /><category term="Rondine" /><category term="Local LLM" /><category term="llama.cpp" /><category term="MLX" /><category term="vLLM" /><category term="Apple Silicon" /><category term="NVIDIA" /><category term="DGX Spark" /><category term="Coding Agents" /><category term="OpenAI API" /><summary type="html"><![CDATA[Rondine detects the hardware you have, recommends open models that fit, applies tuned llama.cpp, MLX-LM, or vLLM settings, and exposes an OpenAI-compatible endpoint for local coding tools.]]></summary></entry><entry><title type="html">Running GLM-5.2 Locally with Rondine and Pi</title><link href="https://www.fratepietro.com/2026/running-glm-5-2-locally-rondine-pi/" rel="alternate" type="text/html" title="Running GLM-5.2 Locally with Rondine and Pi" /><published>2026-07-22T00:00:00+02:00</published><updated>2026-07-22T00:00:00+02:00</updated><id>https://www.fratepietro.com/2026/running-glm-5-2-locally-rondine-pi</id><content type="html" xml:base="https://www.fratepietro.com/2026/running-glm-5-2-locally-rondine-pi/"><![CDATA[<p>In my previous article, <a href="/2026/cmux-pi-unsloth-local-glm-setup/">The Local Agent Trio: cmux + Pi + Unsloth Studio</a>, I split the local coding stack into three replaceable layers:</p>

<ol>
  <li><strong>cmux</strong> for the terminal workspace</li>
  <li><strong>Unsloth Studio</strong> for inference</li>
  <li><strong>Pi</strong> for the coding-agent loop</li>
</ol>

<p>That architecture still makes sense. But there is another way to handle the inference layer—especially when you want the configuration to come from the hardware rather than a model picker.</p>

<p>That is what <a href="https://github.com/antonellof/rondine">Rondine</a> does.</p>

<p>Rondine detects your machine, checks whether a model fits, selects an inference engine and quantization, applies hardware-specific settings, downloads the weights, and starts an OpenAI-compatible server.</p>

<p>For this setup, the stack becomes:</p>

<table>
  <thead>
    <tr>
      <th>Layer</th>
      <th>Tool</th>
      <th>Purpose</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Workspace</td>
      <td>cmux, optionally</td>
      <td>Terminal panes and agent notifications</td>
    </tr>
    <tr>
      <td>Inference</td>
      <td>Rondine + llama.cpp</td>
      <td>Hardware planning, model download, and serving</td>
    </tr>
    <tr>
      <td>Agent</td>
      <td>Pi</td>
      <td>Repository tools and coding loop</td>
    </tr>
  </tbody>
</table>

<p>The interesting target is <strong>GLM-5.2</strong>: a frontier-scale Mixture-of-Experts coding model that requires approximately 245GB of memory even at 2-bit quantization.</p>

<h2 id="the-glm-52-hardware-reality">The GLM-5.2 hardware reality</h2>

<p>Rondine’s catalog describes GLM-5.2 as a 744B-parameter MoE model with approximately 40B active parameters per token and support for a context window of up to one million tokens.</p>

<p>The active parameter count reduces computation, but it does not eliminate the need to store the complete model.</p>

<p>Rondine currently provides these configurations:</p>

<table>
  <thead>
    <tr>
      <th>Variant</th>
      <th style="text-align: right">Approximate size</th>
      <th>Intended hardware</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">UD-IQ1_S</code></td>
      <td style="text-align: right">223GB</td>
      <td>Aggressive compression</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">UD-IQ2_M</code></td>
      <td style="text-align: right">239GB</td>
      <td>Recommended 2-bit balance</td>
    </tr>
    <tr>
      <td>Official BF16</td>
      <td style="text-align: right">~1.5TB</td>
      <td>Large multi-GPU or multi-node system</td>
    </tr>
  </tbody>
</table>

<p>For a single machine, Rondine prefers the Unsloth <code class="language-plaintext highlighter-rouge">UD-IQ2_M</code> GGUF and requires at least 245GB of usable memory.</p>

<p>In practice, this means a <strong>256GB Mac Studio-class machine</strong>. Even then, context length matters. A model may fit at a small context and fail once the KV cache, batching, and operating-system memory are included.</p>

<p>For that reason, Rondine uses a practical <strong>32K coding context</strong> instead of blindly enabling the model’s theoretical maximum.</p>

<h2 id="why-use-rondine">Why use Rondine?</h2>

<p>A raw GLM-5.2 llama.cpp launch requires several decisions:</p>

<ul>
  <li>Which quantization should I download?</li>
  <li>Does it fit in unified memory?</li>
  <li>How much memory should remain available to macOS?</li>
  <li>What context length is realistic?</li>
  <li>Should the KV cache use F16, Q8, or something smaller?</li>
  <li>Should all layers be offloaded to Metal?</li>
  <li>Which batch and micro-batch sizes should I use?</li>
  <li>Should flash attention be enabled?</li>
  <li>How many parallel slots should the server expose?</li>
</ul>

<p>Rondine turns those decisions into a reproducible plan.</p>

<p>It is not another inference engine. It installs and drives llama.cpp, MLX-LM, or vLLM while keeping the generated command visible.</p>

<h2 id="install-rondine">Install Rondine</h2>

<p>Rondine requires Python 3.11+ and <code class="language-plaintext highlighter-rouge">uv</code>:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git clone https://github.com/antonellof/rondine.git
<span class="nb">cd </span>rondine

uv tool <span class="nb">install</span> <span class="nb">.</span>
</code></pre></div></div>

<p>Start by inspecting the machine:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine doctor
</code></pre></div></div>

<p>On a compatible high-memory Mac, the output should identify Apple Silicon, unified memory, and available engines.</p>

<p>You can then ask Rondine to plan GLM-5.2 directly:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine plan glm-5.2 <span class="se">\</span>
  <span class="nt">--profile</span> coding <span class="se">\</span>
  <span class="nt">--save-as</span> glm-coding
</code></pre></div></div>

<p>GLM-5.2 is marked as opt-in because of its size. Explicitly naming it opts into planning it, but Rondine still rejects the plan if the detected hardware cannot satisfy the memory estimate.</p>

<p>Before downloading hundreds of gigabytes, inspect the generated launch:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine serve <span class="nt">--preset</span> glm-coding <span class="nt">--dry-run</span>
</code></pre></div></div>

<p>This prints the resolved llama.cpp command without starting it.</p>

<h2 id="what-the-coding-configuration-contains">What the coding configuration contains</h2>

<p>For GLM-5.2, Rondine’s coding profile applies:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>context:           32768
temperature:       1.0
top_p:             0.95
min_p:             0.01
thinking:          enabled
reasoning effort:  max
parallel slots:    1
</code></pre></div></div>

<p>On Apple Silicon, the llama.cpp template also enables:</p>

<ul>
  <li>Full Metal offload with <code class="language-plaintext highlighter-rouge">-ngl 99</code></li>
  <li>Flash attention</li>
  <li>Continuous batching</li>
  <li>Q8 KV caches</li>
  <li>Large batch and micro-batch sizes where memory permits</li>
  <li><code class="language-plaintext highlighter-rouge">mlock</code> to reduce unwanted swapping</li>
  <li>A single coding slot so context is not divided among concurrent clients</li>
</ul>

<p>The effective command remains visible through the dry run, which is useful when experimenting or reporting a problem upstream.</p>

<h2 id="download-glm-52">Download GLM-5.2</h2>

<p>Once the plan looks correct:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine setup <span class="nt">--engine</span> llama.cpp
rondine pull glm-5.2
</code></pre></div></div>

<p>The preferred quantization is downloaded from:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>unsloth/GLM-5.2-GGUF
</code></pre></div></div>

<p>with the pattern:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>*UD-IQ2_M*
</code></pre></div></div>

<p>This is a multi-hundred-gigabyte download. Plan for enough disk space beyond the model itself, use a stable connection, and remember that loading it will also require memory for context, cache, and the operating system.</p>

<p>If 239GB is too large, <code class="language-plaintext highlighter-rouge">UD-IQ1_S</code> reduces the weights to approximately 223GB, but that is a more aggressive quality compromise.</p>

<h2 id="start-the-openai-compatible-server">Start the OpenAI-compatible server</h2>

<p>Launch the saved preset:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine serve <span class="se">\</span>
  <span class="nt">--preset</span> glm-coding <span class="se">\</span>
  <span class="nt">--name</span> glm
</code></pre></div></div>

<p>Rondine starts llama.cpp on:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>http://127.0.0.1:8080/v1
</code></pre></div></div>

<p>The model alias exposed to clients is:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine/glm-5.2
</code></pre></div></div>

<p>Confirm it through the models endpoint:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>curl http://127.0.0.1:8080/v1/models
</code></pre></div></div>

<p>Then run Rondine’s coding verification:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine verify <span class="se">\</span>
  <span class="nt">--name</span> glm <span class="se">\</span>
  <span class="nt">--profile</span> coding
</code></pre></div></div>

<p>The verification checks:</p>

<ul>
  <li>Server readiness</li>
  <li>The <code class="language-plaintext highlighter-rouge">/v1/models</code> endpoint</li>
  <li>A short code-generation request</li>
  <li>A best-effort OpenAI-format tool-call request</li>
</ul>

<p>This distinction matters: a process listening on port 8080 does not necessarily mean the model, chat template, and tool-calling path are working correctly.</p>

<h2 id="test-glm-52-directly">Test GLM-5.2 directly</h2>

<p>Before adding Pi, make one direct request:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>curl http://127.0.0.1:8080/v1/chat/completions <span class="se">\</span>
  <span class="nt">-H</span> <span class="s2">"Content-Type: application/json"</span> <span class="se">\</span>
  <span class="nt">-d</span> <span class="s1">'{
    "model": "rondine/glm-5.2",
    "messages": [
      {
        "role": "user",
        "content": "Write a typed Python binary search function. Return code only."
      }
    ],
    "max_tokens": 512
  }'</span>
</code></pre></div></div>

<p>If this works, the inference layer is ready. Pi becomes a client of the same endpoint.</p>

<h2 id="install-pi">Install Pi</h2>

<p>Pi is a minimal coding agent with four core tools:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">read</code></li>
  <li><code class="language-plaintext highlighter-rouge">write</code></li>
  <li><code class="language-plaintext highlighter-rouge">edit</code></li>
  <li><code class="language-plaintext highlighter-rouge">bash</code></li>
</ul>

<p>Install it with:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>npm <span class="nb">install</span> <span class="nt">-g</span> <span class="nt">--ignore-scripts</span> <span class="se">\</span>
  @earendil-works/pi-coding-agent
</code></pre></div></div>

<p>Pi can connect to custom OpenAI-compatible providers through:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>~/.pi/agent/models.json
</code></pre></div></div>

<p>Add Rondine as a provider:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
  </span><span class="nl">"providers"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="nl">"rondine"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
      </span><span class="nl">"baseUrl"</span><span class="p">:</span><span class="w"> </span><span class="s2">"http://127.0.0.1:8080/v1"</span><span class="p">,</span><span class="w">
      </span><span class="nl">"api"</span><span class="p">:</span><span class="w"> </span><span class="s2">"openai-completions"</span><span class="p">,</span><span class="w">
      </span><span class="nl">"apiKey"</span><span class="p">:</span><span class="w"> </span><span class="s2">"rondine"</span><span class="p">,</span><span class="w">
      </span><span class="nl">"models"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
        </span><span class="p">{</span><span class="w">
          </span><span class="nl">"id"</span><span class="p">:</span><span class="w"> </span><span class="s2">"rondine/glm-5.2"</span><span class="p">,</span><span class="w">
          </span><span class="nl">"name"</span><span class="p">:</span><span class="w"> </span><span class="s2">"GLM-5.2 local via Rondine"</span><span class="p">,</span><span class="w">
          </span><span class="nl">"contextWindow"</span><span class="p">:</span><span class="w"> </span><span class="mi">32768</span><span class="w">
        </span><span class="p">}</span><span class="w">
      </span><span class="p">]</span><span class="w">
    </span><span class="p">}</span><span class="w">
  </span><span class="p">}</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<p>Most local llama.cpp servers do not validate the API key, but Pi expects a non-empty value.</p>

<p>Use the exact model identifier returned by:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>curl http://127.0.0.1:8080/v1/models
</code></pre></div></div>

<h2 id="start-coding-with-pi">Start coding with Pi</h2>

<p>Move into a repository and launch Pi:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">cd</span> ~/Projects/my-application
pi
</code></pre></div></div>

<p>Inside Pi, open the model selector:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>/model
</code></pre></div></div>

<p>Choose:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>GLM-5.2 local via Rondine
</code></pre></div></div>

<p>Pi now supplies the agent loop while Rondine owns the inference lifecycle.</p>

<p>A useful first prompt is something constrained and verifiable:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Read the project structure and test configuration.

Find one untested error path in the HTTP client, add a focused test,
run only the relevant test suite, and show me the resulting diff.
Do not modify production code unless the test reveals a real defect.
</code></pre></div></div>

<p>This exercises reading, editing, shell execution, and multi-step reasoning without giving the model permission to refactor the entire repository.</p>

<h2 id="add-cmux-if-you-want-the-complete-stack">Add cmux if you want the complete stack</h2>

<p>cmux remains optional, but it makes the workflow easier to observe.</p>

<p>A practical layout is:</p>

<ul>
  <li><strong>Pane 1:</strong> Rondine server logs</li>
  <li><strong>Pane 2:</strong> Pi running in the target repository</li>
  <li><strong>Pane 3:</strong> Shell for health checks, Git, and memory monitoring</li>
</ul>

<p>Start Rondine in the foreground if you want logs attached to a pane:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine serve <span class="se">\</span>
  <span class="nt">--preset</span> glm-coding <span class="se">\</span>
  <span class="nt">--name</span> glm <span class="se">\</span>
  <span class="nt">--foreground</span>
</code></pre></div></div>

<p>Start Pi in another:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">cd</span> ~/Projects/my-application
pi
</code></pre></div></div>

<p>The architecture remains modular:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>cmux
  ├── Rondine
  │     └── llama.cpp
  │           └── GLM-5.2 UD-IQ2_M
  └── Pi
        └── http://127.0.0.1:8080/v1
</code></pre></div></div>

<p>Swap Pi for another OpenAI-compatible coding client and the inference layer stays unchanged. Swap GLM-5.2 for a smaller model and Pi’s workflow stays unchanged.</p>

<h2 id="if-glm-52-does-not-fit">If GLM-5.2 does not fit</h2>

<p>Most developers do not have 256GB of unified memory. Rondine should reject GLM-5.2 on those machines—that is better than discovering the limitation after a 239GB download.</p>

<p>Use the same workflow with a smaller model:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine suggest <span class="nt">--profile</span> coding
</code></pre></div></div>

<p>Typical alternatives include:</p>

<ul>
  <li>Qwen3.6 27B for 24–48GB Macs</li>
  <li>Qwen3.6 35B-A3B for larger Macs or 24GB NVIDIA GPUs</li>
  <li>Gemma 4 12B for smaller systems</li>
  <li>DeepSeek-V4-Flash at 3-bit for approximately 128GB systems</li>
</ul>

<p>For a quick end-to-end test, Rondine also includes Qwen2.5-Coder 3B:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine plan qwen2.5-coder-3b <span class="se">\</span>
  <span class="nt">--context</span> 4096 <span class="se">\</span>
  <span class="nt">--save-as</span> small-coder

rondine pull qwen2.5-coder-3b
rondine serve <span class="nt">--preset</span> small-coder
rondine verify <span class="nt">--name</span> small-coder
</code></pre></div></div>

<p>The Pi configuration is identical apart from the model ID.</p>

<p>This is the main advantage of separating the agent from inference: the workflow does not depend on one model fitting forever.</p>

<h2 id="stopping-and-restarting">Stopping and restarting</h2>

<p>Stop the managed GLM server with:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine stop <span class="nt">--name</span> glm
</code></pre></div></div>

<p>Restart the saved configuration later:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine serve <span class="se">\</span>
  <span class="nt">--preset</span> glm-coding <span class="se">\</span>
  <span class="nt">--name</span> glm
</code></pre></div></div>

<p>Inspect it at any time:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>rondine preset show glm-coding
</code></pre></div></div>

<p>The tuned command is no longer something you have to recover from shell history.</p>

<h2 id="honest-limitations">Honest limitations</h2>

<p>This setup does not make GLM-5.2 small.</p>

<p>The recommended quant still occupies approximately 239GB, and a 256GB Mac leaves limited headroom. Large contexts may require reducing batches, using a smaller context, or moving to hardware with more memory.</p>

<p>Rondine currently provides a hardware-aware configuration, not a published GLM-5.2 performance guarantee. Its documented benchmark is a smaller Qwen2.5-Coder run on an M2 Pro; that validates the plan-to-API path but should not be presented as evidence of GLM-5.2 throughput.</p>

<p>Tool calling also depends on the model, llama.cpp version, chat template, and streaming compatibility. Run <code class="language-plaintext highlighter-rouge">rondine verify</code>, test Pi on a disposable branch, and inspect the server logs before trusting a long autonomous session.</p>

<h2 id="bottom-line">Bottom line</h2>

<p>The local coding stack works best when its layers remain replaceable:</p>

<ul>
  <li><strong>Rondine</strong> chooses, configures, downloads, and serves the model.</li>
  <li><strong>llama.cpp</strong> performs inference.</li>
  <li><strong>Pi</strong> reads, edits, and runs commands in the repository.</li>
  <li><strong>cmux</strong>, optionally, keeps the sessions visible.</li>
</ul>

<p>GLM-5.2 is the demanding case that makes hardware-aware planning valuable. On a compatible 256GB machine, Rondine turns a 239GB sharded GGUF and a page of llama.cpp flags into a named, inspectable preset exposed at a standard OpenAI URL.</p>

<p>Pi does not need to know how any of that works. It only needs:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>http://127.0.0.1:8080/v1
</code></pre></div></div>

<p>That is the useful abstraction: a very large local model underneath, a very small coding agent on top, and a standard API boundary between them.</p>

<hr />

<p><strong>Links</strong></p>

<ul>
  <li><a href="https://github.com/antonellof/rondine">Rondine on GitHub</a></li>
  <li><a href="/2026/cmux-pi-unsloth-local-glm-setup/">The Local Agent Trio: cmux + Pi + Unsloth Studio</a></li>
  <li><a href="https://github.com/earendil-works/pi">Pi coding agent</a></li>
  <li><a href="https://huggingface.co/unsloth/GLM-5.2-GGUF">GLM-5.2 GGUF weights</a></li>
</ul>]]></content><author><name>Antonello Fratepietro</name><email>antonello.f at gmail dot com</email></author><category term="How-To" /><category term="Rondine" /><category term="GLM-5.2" /><category term="Pi Agent" /><category term="Local LLM" /><category term="llama.cpp" /><category term="Apple Silicon" /><category term="Coding Agents" /><category term="OpenAI API" /><summary type="html"><![CDATA[A hardware-aware path from a 239GB GLM-5.2 GGUF to an OpenAI-compatible coding agent, without hand-tuning llama.cpp.]]></summary></entry><entry><title type="html">The Local Agent Trio: cmux + Pi + Unsloth Studio</title><link href="https://www.fratepietro.com/2026/cmux-pi-unsloth-local-glm-setup/" rel="alternate" type="text/html" title="The Local Agent Trio: cmux + Pi + Unsloth Studio" /><published>2026-06-29T00:00:00+02:00</published><updated>2026-06-29T00:00:00+02:00</updated><id>https://www.fratepietro.com/2026/cmux-pi-unsloth-local-glm-setup</id><content type="html" xml:base="https://www.fratepietro.com/2026/cmux-pi-unsloth-local-glm-setup/"><![CDATA[<p>Cloud agents are convenient right up until you care about privacy, predictable costs, or a model that will not rate-limit you at 2am in the middle of a refactor. And here is the thing nobody tells you: the hard part of going local is not finding <em>a</em> model. It is wiring the <strong>terminal</strong>, the <strong>inference server</strong>, and the <strong>agent harness</strong> into something you can actually sit in front of for eight hours without wanting to throw the laptop out the window.</p>

<p>After a fair amount of trial and error, this is the trio I keep coming back to:</p>

<ol>
  <li><strong><a href="https://cmux.com/">cmux</a></strong> — native macOS terminal (Ghostty-based) built for juggling multiple AI agents in parallel</li>
  <li><strong><a href="https://unsloth.ai/docs/new/studio">Unsloth Studio</a></strong> — local web UI + OpenAI/Anthropic-compatible API over <code class="language-plaintext highlighter-rouge">llama.cpp</code></li>
  <li><strong><a href="https://pi.dev/">Pi</a></strong> — minimal open-source coding agent in the terminal</li>
</ol>

<p>Point Pi at Unsloth. Run Unsloth in one cmux pane. Run Pi in another. When GLM-5.2 fits your hardware, you get frontier-class open weights at home. When it does not — and it often does not — the same stack still works with smaller GGUFs while you plan your RAM upgrade.</p>

<h2 id="why-three-tools-instead-of-one">Why three tools instead of one?</h2>

<p>Monolithic “local AI” apps try to be terminal + model server + agent + UI. They work until you want to swap the agent, swap the model, or run two agents side by side without two Electron apps eating 4GB each.</p>

<table>
  <thead>
    <tr>
      <th>Layer</th>
      <th>Tool</th>
      <th>Job</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Terminal / workspace</strong></td>
      <td>cmux</td>
      <td>Panes, tabs, agent notifications, git context in sidebar</td>
    </tr>
    <tr>
      <td><strong>Inference</strong></td>
      <td>Unsloth Studio</td>
      <td>Download GGUFs, chat UI, <code class="language-plaintext highlighter-rouge">/v1/chat/completions</code> API</td>
    </tr>
    <tr>
      <td><strong>Agent harness</strong></td>
      <td>Pi</td>
      <td><code class="language-plaintext highlighter-rouge">read</code> / <code class="language-plaintext highlighter-rouge">write</code> / <code class="language-plaintext highlighter-rouge">edit</code> / <code class="language-plaintext highlighter-rouge">bash</code> loop against your repo</td>
    </tr>
  </tbody>
</table>

<p>Each piece is replaceable. Swap Pi for Claude Code pointed at the same Unsloth endpoint. Swap Unsloth for raw <code class="language-plaintext highlighter-rouge">llama-server</code>. Keep cmux either way — that is the whole point.</p>

<h2 id="layer-1-cmux--the-agent-aware-terminal">Layer 1: cmux — the agent-aware terminal</h2>

<p><a href="https://github.com/manaflow-ai/cmux">cmux</a> is an open-source (GPL-3.0), native macOS terminal from <a href="https://cmux.com/">Manaflow</a> (a YC S24 company). It is not a fork of <a href="https://ghostty.org/">Ghostty</a> — it embeds <code class="language-plaintext highlighter-rouge">libghostty</code> as a rendering library inside a Swift/AppKit app, the same way other apps embed WebKit, and even reads your existing <code class="language-plaintext highlighter-rouge">~/.config/ghostty/config</code>. It was built for one specific itch: <strong>running a pile of coding agents in parallel</strong> without losing track of which one is blocked on you. The author got tired of staring at a wall of Ghostty splits where every Claude Code notification just said “Claude is waiting for your input” with no idea <em>which</em> Claude. That frustration is the whole product, and it shows.</p>

<p>What matters for agent work:</p>

<ul>
  <li><strong>Vertical tab sidebar</strong> — git branch, working directory, ports, latest notification text per workspace</li>
  <li><strong>Notification rings</strong> — blue halo on panes when an agent needs input (OSC 9/99/777 or <code class="language-plaintext highlighter-rouge">cmux notify</code>)</li>
  <li><strong>Cmd+Shift+U</strong> — jump to the most recent unread notification</li>
  <li><strong>Split panes</strong> — shell + Pi + browser without nested tmux config archaeology</li>
</ul>

<p>cmux docs list <strong>Pi</strong> alongside Claude Code, Codex, OpenCode, and Gemini CLI as agents that work out of the box — because cmux is a terminal, not a vendor lock-in product. <a href="https://cmux.com/docs/notifications">Notification hooks</a> wire into agent lifecycle with:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>cmux notify <span class="nt">--title</span> <span class="s2">"Pi"</span> <span class="nt">--body</span> <span class="s2">"Waiting for your input"</span>
</code></pre></div></div>

<p>Compared to tmux: tmux multiplexes inside a terminal; cmux <em>is</em> the terminal with GUI affordances agents actually need. Compared to Warp: cmux is native Swift, not Electron, and does not force one agent workflow.</p>

<p>Install from <a href="https://cmux.com/">cmux.com</a> or build from <a href="https://github.com/manaflow-ai/cmux">github.com/manaflow-ai/cmux</a>.</p>

<h2 id="layer-2-unsloth-studio--inference-without-the-yaml-archaeology">Layer 2: Unsloth Studio — inference without the YAML archaeology</h2>

<p><a href="https://unsloth.ai/docs/new/studio">Unsloth Studio</a> is an open-source, browser-based local GUI for running (and training) open models. Under the hood: <strong>llama.cpp</strong>, with extras — self-healing tool calling, code execution, web search, automatic inference tuning, Hugging Face Hub search built in.</p>

<p>Install:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>curl <span class="nt">-fsSL</span> https://unsloth.ai/install.sh | sh
unsloth studio <span class="nt">-p</span> 8888
</code></pre></div></div>

<p>Open <code class="language-plaintext highlighter-rouge">http://127.0.0.1:8888</code>, set a password on first run, then head to <strong>Chat → Select model</strong>. Studio exposes:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">GET /api/health</code> — health check</li>
  <li><code class="language-plaintext highlighter-rouge">POST /v1/chat/completions</code> — OpenAI-compatible (Pi, Cursor, Continue, Cline…)</li>
  <li><code class="language-plaintext highlighter-rouge">POST /v1/messages</code> — Anthropic-compatible (Claude Code, OpenClaw…)</li>
  <li><code class="language-plaintext highlighter-rouge">GET /v1/models</code> — whatever is loaded in memory</li>
</ul>

<p>API key lives under <strong>Settings → API</strong> (printed once at startup as <code class="language-plaintext highlighter-rouge">sk-unsloth-...</code>). Full reference: <a href="https://unsloth.ai/docs/basics/api">Unsloth API docs</a>.</p>

<h3 id="glm-52-on-the-model-picker--and-the-oom-badge">GLM-5.2 on the model picker — and the OOM badge</h3>

<p><a href="https://unsloth.ai/docs/models/glm-5.2">GLM-5.2</a> is Z.ai’s open Mixture-of-Experts model. The <a href="https://huggingface.co/zai-org/GLM-5.2">official model card</a> lists it at <strong>753B parameters</strong> with a <strong>1M-token context</strong> under an MIT license (Unsloth’s docs round it to ~744B; the Studio picker in my screenshot reads 753.9B). Being an MoE, only a slice of those weights fire per token — but you still have to hold the entire thing in memory. Unsloth’s <code class="language-plaintext highlighter-rouge">UD-IQ2_M</code> 2-bit quant needs roughly <strong>240–245 GB of RAM or unified memory</strong> — realistic on a 256 GB Mac Studio, not on a laptop without serious SSD offloading.</p>

<p>Here is what my Studio instance looked like on launch day:</p>

<p><img src="/assets/images/posts/unsloth-studio-glm52-model-picker.png" alt="Unsloth Studio model picker with GLM-5.2-GGUF showing an OOM badge alongside smaller on-device models like Qwen3.5-9B and gemma-4-12b" /></p>

<p><strong>GLM-5.2-GGUF</strong> at <strong>753.9B</strong> with a red <strong>OOM</strong> pill is Studio being honest: your machine cannot load that variant right now. The trio setup still works — load <strong>Qwen3.5-9B-GGUF</strong>, <strong>gemma-4-12b</strong>, or another <strong>On Device</strong> model from the same picker while you plan for GLM-scale RAM.</p>

<p>When hardware cooperates, search <code class="language-plaintext highlighter-rouge">GLM-5.2</code> in Studio, pick <code class="language-plaintext highlighter-rouge">UD-IQ2_M</code> (or higher quant if you have headroom), download the shards from <a href="https://huggingface.co/unsloth/GLM-5.2-GGUF"><code class="language-plaintext highlighter-rouge">unsloth/GLM-5.2-GGUF</code></a>, and chat with <strong>High/Max thinking</strong> toggles in the UI. CLI alternative:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>hf download unsloth/GLM-5.2-GGUF <span class="se">\</span>
  <span class="nt">--local-dir</span> unsloth/GLM-5.2-GGUF <span class="se">\</span>
  <span class="nt">--include</span> <span class="s2">"*UD-IQ2_M*"</span>
</code></pre></div></div>

<p>Terminal logs worth knowing:</p>

<ul>
  <li>Studio binds to <code class="language-plaintext highlighter-rouge">127.0.0.1:8888</code> by default; use <code class="language-plaintext highlighter-rouge">-H 0.0.0.0</code> for LAN access (Pi on another machine, phone on same network)</li>
  <li><code class="language-plaintext highlighter-rouge">llama.cpp prebuilt lacks MTP support</code> — run <code class="language-plaintext highlighter-rouge">unsloth studio update</code> if you want speculative decoding on MTP-tagged GGUFs; models still load without it</li>
</ul>

<h2 id="layer-3-pi--the-minimal-coding-harness">Layer 3: Pi — the minimal coding harness</h2>

<p><a href="https://github.com/earendil-works/pi">Pi</a> (package <code class="language-plaintext highlighter-rouge">@earendil-works/pi-coding-agent</code>) is a <strong>minimal terminal coding agent</strong> by Mario Zechner — yes, the <a href="https://libgdx.com/">libGDX</a> guy. It ships with exactly four tools (<code class="language-plaintext highlighter-rouge">read</code>, <code class="language-plaintext highlighter-rouge">write</code>, <code class="language-plaintext highlighter-rouge">edit</code>, <code class="language-plaintext highlighter-rouge">bash</code>), the shortest system prompt of any serious agent, multi-provider LLM support, and no baked-in sub-agent circus. The philosophy is “adapt the harness to your workflow, not the other way around” — anything the bigger agents bundle, you add yourself as a TypeScript extension or a Pi package. It is MIT, now stewarded by <a href="https://github.com/earendil-works">Earendil</a>, and it is the agent core underneath OpenClaw, so it is battle-tested despite the minimalism.</p>

<p>Install:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>npm <span class="nb">install</span> <span class="nt">-g</span> <span class="nt">--ignore-scripts</span> @earendil-works/pi-coding-agent
pi
</code></pre></div></div>

<p>Pi supports Anthropic, OpenAI, OpenRouter, Ollama, and <strong>any OpenAI-compatible local server</strong> via <code class="language-plaintext highlighter-rouge">~/.pi/agent/models.json</code>. Docs: <a href="https://github.com/earendil-works/pi/blob/main/packages/coding-agent/docs/models.md">pi models.md</a>.</p>

<p>For llama.cpp servers specifically, Hugging Face ships <a href="https://github.com/huggingface/pi-llama"><code class="language-plaintext highlighter-rouge">pi-llama</code></a> — auto-discovers models from a running server:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>pi <span class="nb">install </span>git:github.com/huggingface/pi-llama
<span class="c"># LLAMA_BASE_URL defaults to http://localhost:8080/v1</span>
</code></pre></div></div>

<p>Unsloth wraps llama.cpp on port <strong>8888</strong> with its own API surface — so the direct path is OpenAI-compat config:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
  </span><span class="nl">"providers"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="nl">"unsloth"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
      </span><span class="nl">"baseUrl"</span><span class="p">:</span><span class="w"> </span><span class="s2">"http://127.0.0.1:8888/v1"</span><span class="p">,</span><span class="w">
      </span><span class="nl">"api"</span><span class="p">:</span><span class="w"> </span><span class="s2">"openai-completions"</span><span class="p">,</span><span class="w">
      </span><span class="nl">"apiKey"</span><span class="p">:</span><span class="w"> </span><span class="s2">"sk-unsloth-your-key-from-settings"</span><span class="p">,</span><span class="w">
      </span><span class="nl">"models"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="w">
        </span><span class="p">{</span><span class="w">
          </span><span class="nl">"id"</span><span class="p">:</span><span class="w"> </span><span class="s2">"unsloth/GLM-5.2-GGUF"</span><span class="p">,</span><span class="w">
          </span><span class="nl">"name"</span><span class="p">:</span><span class="w"> </span><span class="s2">"GLM-5.2 local (Unsloth)"</span><span class="p">,</span><span class="w">
          </span><span class="nl">"contextWindow"</span><span class="p">:</span><span class="w"> </span><span class="mi">131072</span><span class="w">
        </span><span class="p">}</span><span class="w">
      </span><span class="p">]</span><span class="w">
    </span><span class="p">}</span><span class="w">
  </span><span class="p">}</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<p>Use the <strong>exact model id</strong> from <code class="language-plaintext highlighter-rouge">curl http://127.0.0.1:8888/v1/models</code> after loading in Studio. Then inside Pi:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>/model
</code></pre></div></div>

<p>Select your Unsloth provider model. Pi’s status bar shows provider, model, token budget, and cost (zero for local).</p>

<h3 id="pi-inside-cmux">Pi inside cmux</h3>

<p>My cmux sidebar with <strong>shell</strong>, <strong>π</strong>, and <strong>Paperclip</strong> tabs:</p>

<p><img src="/assets/images/posts/cmux-pi-agent-pane.png" alt="cmux sidebar with Pi agent pane showing release notes and a hello chat session, status bar displaying OpenRouter GPT-5.5" /></p>

<p>The screenshot shows Pi on <strong>OpenRouter / GPT-5.5</strong> — useful when GLM-5.2 OOMs or you need a quick cloud fallback. Same pane, swap model via <code class="language-plaintext highlighter-rouge">/model</code> to your Unsloth local entry when the GGUF is loaded. That is the trio’s flexibility: <strong>one terminal layout, two inference backends</strong>.</p>

<p>Pi v0.80.x changelog visible in the pane (June 2026) — active project, weekly releases, <code class="language-plaintext highlighter-rouge">pi-ai</code> provider auth improvements. Mirror line <code class="language-plaintext highlighter-rouge">192.168.1.8:3001</code> in the status bar is Pi’s optional session mirror for secondary clients — handy if you want phone/tablet observation without disturbing the agent pane.</p>

<h2 id="wiring-the-trio-step-by-step">Wiring the trio: step by step</h2>

<p><strong>Pane A — Unsloth (inference server)</strong></p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>unsloth studio <span class="nt">-p</span> 8888
<span class="c"># Load a model in the browser (Chat → Select model)</span>
<span class="c"># Copy API key from Settings → API</span>
</code></pre></div></div>

<p><strong>Pane B — Pi (coding agent)</strong></p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">export </span><span class="nv">PI_MODEL</span><span class="o">=</span>unsloth/your-loaded-model-id   <span class="c"># optional shortcut</span>
pi
/model   <span class="c"># pick Unsloth provider</span>
</code></pre></div></div>

<p><strong>cmux layout</strong></p>

<ul>
  <li>Tab 1 <code class="language-plaintext highlighter-rouge">shell</code>: Studio server logs, <code class="language-plaintext highlighter-rouge">curl</code> health checks, <code class="language-plaintext highlighter-rouge">hf download</code> progress</li>
  <li>Tab 2 <code class="language-plaintext highlighter-rouge">π</code>: Pi session on your repo (<code class="language-plaintext highlighter-rouge">cd ~/Projects/my-app &amp;&amp; pi</code>)</li>
  <li>Optional Tab 3 <code class="language-plaintext highlighter-rouge">Paperclip</code>: docs, PRDs, attachments Pi reads via <code class="language-plaintext highlighter-rouge">read</code></li>
</ul>

<p>When Pi blocks on a tool approval or finishes a long task, wire a hook:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>cmux notify <span class="nt">--title</span> <span class="s2">"Pi"</span> <span class="nt">--subtitle</span> <span class="s2">"my-app"</span> <span class="nt">--body</span> <span class="s2">"Ready for review"</span>
</code></pre></div></div>

<h2 id="glm-52-when-the-trio-earns-its-name">GLM-5.2: when the trio earns its name</h2>

<p>GLM-5.2 is why you bother with Unsloth at all instead of pulling a 7B model from Ollama and calling it a day. The MoE design means the model carries frontier-scale knowledge while only activating a fraction of its parameters per token — you get agentic coding, long-horizon reasoning, and a 1M-token context out of weights that, quantized, fit in a (very large) workstation. Unsloth’s Dynamic GGUF quants are the part doing the heavy lifting: they compress aggressively while trying hard to preserve accuracy.</p>

<p>Realistic hardware map (from <a href="https://unsloth.ai/docs/models/glm-5.2">Unsloth docs</a>):</p>

<table>
  <thead>
    <tr>
      <th>Quant</th>
      <th>Approx. RAM</th>
      <th>Notes</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>UD-IQ1_S</td>
      <td>~223 GB</td>
      <td>Most aggressive</td>
    </tr>
    <tr>
      <td><strong>UD-IQ2_M</strong></td>
      <td><strong>~245 GB</strong></td>
      <td>Recommended balance</td>
    </tr>
    <tr>
      <td>UD-Q8_K_XL</td>
      <td>~810 GB</td>
      <td>Near full precision</td>
    </tr>
  </tbody>
</table>

<p>No 256 GB Mac? Run the trio with <strong>Qwen3.5-9B</strong>, <strong>gemma-4-12b</strong>, or <strong>Qwen3.6-27B</strong> locally — same cmux layout, same Pi config, same API wiring — and treat GLM-5.2 as the target state when RAM catches up. The OOM badge in Studio is a feature, not a failure.</p>

<h2 id="troubleshooting-the-obvious-failures">Troubleshooting the obvious failures</h2>

<p><strong>Pi cannot see tools / agent stalls after first bash</strong></p>

<p>OpenAI-compat shims sometimes drop streamed <code class="language-plaintext highlighter-rouge">tool_calls</code>. Pi’s <a href="https://github.com/earendil-works/pi/blob/main/packages/coding-agent/docs/models.md">models.json <code class="language-plaintext highlighter-rouge">compat</code> flags</a> help; for Ollama specifically use <a href="https://github.com/CaptCanadaMan/pi-ollama"><code class="language-plaintext highlighter-rouge">pi-ollama</code></a> native provider. Unsloth’s self-healing tool calling is designed for this — if issues persist, check Studio logs while Pi runs.</p>

<p><strong>Studio port conflict</strong></p>

<p>Default is 8888; docs also mention 8000 depending on version. Terminal prints the actual URL on boot — use that in <code class="language-plaintext highlighter-rouge">baseUrl</code>.</p>

<p><strong>GLM download is 6 shard files, hundreds of GB</strong></p>

<p>Plan disk and time. <code class="language-plaintext highlighter-rouge">hf download</code> with <code class="language-plaintext highlighter-rouge">--include "*UD-IQ2_M*"</code> pulls only the 2-bit shards. Resume supported.</p>

<p><strong>MTP warning in shell</strong></p>

<p>Update Studio: <code class="language-plaintext highlighter-rouge">unsloth studio update</code>. MTP speculative decoding is optional; chat works without it.</p>

<p><strong>Want Claude Code instead of Pi</strong></p>

<p>Same Unsloth server, Anthropic route:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">export </span><span class="nv">ANTHROPIC_BASE_URL</span><span class="o">=</span><span class="s2">"http://127.0.0.1:8888"</span>
<span class="nb">export </span><span class="nv">ANTHROPIC_API_KEY</span><span class="o">=</span><span class="s2">"sk-unsloth-your-key"</span>
<span class="nb">export </span><span class="nv">ANTHROPIC_MODEL</span><span class="o">=</span><span class="s2">"unsloth/gemma-4-26B-A4B-it-GGUF"</span>
claude <span class="nt">--model</span> <span class="s2">"</span><span class="nv">$ANTHROPIC_MODEL</span><span class="s2">"</span>
</code></pre></div></div>

<p>See <a href="https://unsloth.ai/docs/basics/claude-code">Unsloth’s Claude Code guide</a>. cmux does not care which agent occupies the pane.</p>

<h2 id="bottom-line">Bottom line</h2>

<p>The trio is not “install one app and pray.” It is a deliberate split:</p>

<ul>
  <li><strong>cmux</strong> — see every agent, know which one needs you</li>
  <li><strong>Unsloth</strong> — search, download, serve, and API-wrap open models including GLM-5.2</li>
  <li><strong>Pi</strong> — minimal harness that respects your repo and your keys</li>
</ul>

<p>GLM-5.2 on Unsloth is the headline. The OOM badge in my screenshot is the honest footnote: frontier-class local AI genuinely exists now, but RAM is still the gate, and most of us are not sitting on 256 GB of unified memory yet. That is fine. The setup earns its keep today with a model that fits, and the day you do upgrade, the path is “pick a bigger GGUF in the same picker” — not “rewrite your whole workflow.”</p>

<p>So: start cmux, start Studio, load whatever your machine can hold, and point Pi at <code class="language-plaintext highlighter-rouge">localhost:8888/v1</code>. Then go refactor something you would rather not have shipped off to a cloud provider in the first place.</p>

<hr />

<p><em>cmux: <a href="https://cmux.com/">cmux.com</a> · <a href="https://github.com/manaflow-ai/cmux">github.com/manaflow-ai/cmux</a>. Pi: <a href="https://pi.dev/">pi.dev</a> · <a href="https://github.com/earendil-works/pi">github.com/earendil-works/pi</a>. Unsloth Studio: <a href="https://unsloth.ai/docs/new/studio">unsloth.ai/docs/new/studio</a>. GLM-5.2: <a href="https://unsloth.ai/docs/models/glm-5.2">unsloth.ai/docs/models/glm-5.2</a>.</em></p>]]></content><author><name>Antonello Fratepietro</name><email>antonello.f at gmail dot com</email></author><category term="How-To" /><category term="cmux" /><category term="Pi Agent" /><category term="Unsloth" /><category term="GLM-5.2" /><category term="Local LLM" /><category term="llama.cpp" /><category term="macOS" /><category term="Agentic AI" /><summary type="html"><![CDATA[Run a serious local agent stack on macOS: cmux for parallel agent panes, Unsloth Studio as your llama.cpp inference server, and Pi as the minimal coding harness. GLM-5.2 is on the menu — if your RAM agrees.]]></summary></entry><entry><title type="html">Google AX: A Distributed Agent Runtime with Durable Execution</title><link href="https://www.fratepietro.com/2026/google-ax-distributed-agent-runtime/" rel="alternate" type="text/html" title="Google AX: A Distributed Agent Runtime with Durable Execution" /><published>2026-06-05T00:00:00+02:00</published><updated>2026-06-05T00:00:00+02:00</updated><id>https://www.fratepietro.com/2026/google-ax-distributed-agent-runtime</id><content type="html" xml:base="https://www.fratepietro.com/2026/google-ax-distributed-agent-runtime/"><![CDATA[<p>Here is a failure mode I have hit more than once: an agent is halfway through a long task, then a deploy rolls the pods, a node gets evicted, or a human-in-the-loop step sits unanswered for six hours — and the whole run is just gone.</p>

<p>No event log. No checkpoint. No way to pick up where it left off. The framework handled the reasoning loop beautifully, but nobody handled the boring part: <strong>execution durability</strong>.</p>

<p>In 2026, Google open-sourced <a href="https://github.com/google/ax"><strong>AX (Agent Executor)</strong></a> — a <strong>distributed agent runtime</strong> that coordinates agentic loops, logs every step, recovers from failures, and audits tool calls through a single controller. It is explicitly <strong>not</strong> an agent framework, <strong>not</strong> a managed service, and <strong>not</strong> tied to one model. It is the <strong>orchestration layer</strong> — <em>how</em> execution proceeds, resumes, and gets inspected.</p>

<p>For <strong>where</strong> agent processes physically run at scale (suspend, multiplex, teleport across Pods), see the companion post on <a href="https://www.fratepietro.com/2026/agent-substrate-zero-idle-kubernetes/">Agent Substrate</a> — the other open-source project Google’s GKE team shipped at the same time, and the recommended Kubernetes target for AX.</p>

<h2 id="why-agents-need-a-runtime-not-just-a-framework">Why agents need a runtime, not just a framework</h2>

<p><a href="https://www.langchain.com/langgraph">LangGraph</a>, <a href="https://google.github.io/adk-docs/">ADK</a>, <a href="https://microsoft.github.io/autogen/">AutoGen</a> — excellent for structuring agent logic. They do not give you:</p>

<ul>
  <li><strong>Durable execution</strong> across crashes and deploys</li>
  <li><strong>Connection recovery</strong> when the client disconnects mid-stream</li>
  <li><strong>Trajectory branching</strong> to explore alternatives without destroying history</li>
  <li><strong>Centralized auditing</strong> of every skill, tool, and sub-agent call</li>
  <li><strong>Isolated actors</strong> for tools, sandboxes, and remote agents in distributed harnesses</li>
</ul>

<p>As agents evolve from chat assistants to <strong>autonomous long-running workers</strong>, those gaps stop being edge cases. Google’s <a href="https://cloud.google.com/blog/products/ai-machine-learning/agent-executor-googles-distributed-agent-runtime">announcement blog</a> frames AX as the open foundation every sophisticated agentic application will need — built in public so design decisions get validated before APIs freeze.</p>

<p>AX is in <strong>active early development</strong>. PRs are temporarily paused. Protocols <strong>will</strong> break. Read the warnings; the architecture still matters.</p>

<h2 id="what-ax-provides">What AX provides</h2>

<p>AX ships as a Go runtime plus an <code class="language-plaintext highlighter-rouge">ax</code> CLI:</p>

<ul>
  <li><strong>Single-writer controller</strong> — one source of truth for execution state</li>
  <li><strong>Durable event log</strong> — SQLite by default; replay on recovery</li>
  <li><strong>Resumable streams</strong> — clients reconnect with <code class="language-plaintext highlighter-rouge">--last-seq</code> and catch up</li>
  <li><strong>Trajectory forking</strong> — <code class="language-plaintext highlighter-rouge">ax fork</code> branches at any checkpoint</li>
  <li><strong>Isolated actors</strong> — agents, tools, skills, sandboxes as separate processes</li>
</ul>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>  Client
    │
    │  resumable stream
    ▼
  Router ──► AX Controller ──┬──► Remote Agent (isolated actor)
              (event log,     ├──► Tool / MCP server (isolated actor)
               registry)      └──► Environment / skills (isolated actor)
</code></pre></div></div>

<h3 id="what-ax-is-not">What AX is NOT</h3>

<p>Google is explicit — and the discipline is refreshing:</p>

<ul>
  <li><strong>Not a managed service</strong> — self-hosted; you operate it</li>
  <li><strong>Not an agent framework</strong> — bring LangGraph, ADK, whatever</li>
  <li><strong>Not a coding harness</strong> — Antigravity integration is roadmap, not product</li>
  <li><strong>Not model-specific</strong> — built-in Gemini agent included, not required</li>
</ul>

<p>The industry keeps conflating “agent product” with “agent runtime.” AX draws the line.</p>

<h2 id="the-cli-flight-recorder-for-agentic-execution">The CLI: flight recorder for agentic execution</h2>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>go <span class="nb">install </span>github.com/google/ax/cmd/ax@latest

<span class="c"># Local execution with built-in planner + bash tool</span>
ax <span class="nb">exec</span> <span class="nt">--input</span> <span class="s2">"List files in this directory"</span>

<span class="c"># Server mode</span>
ax serve   <span class="c"># :8494 by default</span>

<span class="c"># Client disconnected? Catch up from sequence 12</span>
ax <span class="nb">exec</span> <span class="se">\</span>
  <span class="nt">--conversation</span> d85a4b4e-c53b-4c84-b879-f10d905bce40 <span class="se">\</span>
  <span class="nt">--last-seq</span> 12 <span class="se">\</span>
  <span class="nt">--resume</span>

<span class="c"># Branch exploration without destroying source history</span>
ax fork <span class="se">\</span>
  <span class="nt">--src-conversation</span> 38460323-9a78-41cb-8991-022b0ff2c19c <span class="se">\</span>
  <span class="nt">--dest-conversation</span> e5e26e38-53a2-4f22-b1cb-ae867357df83 <span class="se">\</span>
  <span class="nt">--src-seq</span> 12

<span class="c"># Visualize execution in browser</span>
ax trace <span class="nt">--conversation</span> 1a6e0b29-87c2-4af0-81ac-0c73bf8fa293
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">ax trace</code> tells you the audience — engineers who wanted a <strong>flight recorder</strong>, not another chat UI.</p>

<h3 id="configuration-axyaml">Configuration (<code class="language-plaintext highlighter-rouge">ax.yaml</code>)</h3>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">server</span><span class="pi">:</span>
  <span class="na">address</span><span class="pi">:</span> <span class="s2">"</span><span class="s">:8494"</span>

<span class="na">eventlog</span><span class="pi">:</span>
  <span class="na">sqlite</span><span class="pi">:</span>
    <span class="na">filename</span><span class="pi">:</span> <span class="s2">"</span><span class="s">eventlog/log.sqlite"</span>

<span class="na">planner</span><span class="pi">:</span>
  <span class="na">gemini</span><span class="pi">:</span>
    <span class="na">model</span><span class="pi">:</span> <span class="s2">"</span><span class="s">gemini-3.5-flash"</span>
    <span class="na">timeout</span><span class="pi">:</span> <span class="s2">"</span><span class="s">60s"</span>
    <span class="na">skills_dir</span><span class="pi">:</span> <span class="s2">"</span><span class="s">./examples/skills"</span>

<span class="na">registry</span><span class="pi">:</span>
  <span class="na">remote_agents</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="na">id</span><span class="pi">:</span> <span class="s2">"</span><span class="s">medical-deep-researcher"</span>
      <span class="na">name</span><span class="pi">:</span> <span class="s2">"</span><span class="s">Medical</span><span class="nv"> </span><span class="s">Deep</span><span class="nv"> </span><span class="s">Researcher"</span>
      <span class="na">description</span><span class="pi">:</span> <span class="s2">"</span><span class="s">Deep</span><span class="nv"> </span><span class="s">medical</span><span class="nv"> </span><span class="s">research</span><span class="nv"> </span><span class="s">via</span><span class="nv"> </span><span class="s">pubmed</span><span class="nv"> </span><span class="s">and</span><span class="nv"> </span><span class="s">clinicaltrials.gov"</span>
      <span class="na">address</span><span class="pi">:</span> <span class="s2">"</span><span class="s">localhost:50051"</span>
</code></pre></div></div>

<p>Remote agents implement <code class="language-plaintext highlighter-rouge">AgentService</code> gRPC (<a href="https://github.com/google/ax/blob/main/proto/ax.proto"><code class="language-plaintext highlighter-rouge">proto/ax.proto</code></a>). Examples ship for native remote agents, <a href="https://github.com/google/ax/tree/main/examples/adk_agent">ADK (Python)</a>, <a href="https://github.com/a2aproject/A2A">A2A protocol</a> bridges, and experimental Colab agents.</p>

<p>The built-in planner includes a <strong>bash tool</strong> with <strong>explicit user approval</strong> before execution — small detail, production thinking.</p>

<h3 id="custom-agents-in-three-terminals">Custom agents in three terminals</h3>

<p><strong>Terminal 1</strong> — remote agent server:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>go run examples/remote_agent/main.go   <span class="c"># :50051</span>
</code></pre></div></div>

<p><strong>Terminal 2</strong> — AX controller:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ax serve
</code></pre></div></div>

<p><strong>Terminal 3</strong> — execute:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ax <span class="nb">exec</span> <span class="nt">--server</span> localhost:8494 <span class="se">\</span>
  <span class="nt">--input</span> <span class="s2">"HELLO, CAN YOU LOWERCASE WHAT I JUST SAID?"</span>
</code></pre></div></div>

<p>Register remote agents in <code class="language-plaintext highlighter-rouge">ax.yaml</code> under <code class="language-plaintext highlighter-rouge">registry.remote_agents</code>. Point <code class="language-plaintext highlighter-rouge">ax exec --agent coding</code> at any registered ID.</p>

<h2 id="three-resume-problems--and-who-solves-what">Three “resume” problems — and who solves what</h2>

<p>“Resume” means different things. AX and <a href="https://www.fratepietro.com/2026/agent-substrate-zero-idle-kubernetes/">Agent Substrate</a> solve different ones:</p>

<table>
  <thead>
    <tr>
      <th>Problem</th>
      <th>AX</th>
      <th>Substrate</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Client disconnected mid-stream</td>
      <td><code class="language-plaintext highlighter-rouge">--last-seq</code> event replay</td>
      <td>Transparent to client</td>
    </tr>
    <tr>
      <td>Process crashed mid-task</td>
      <td>Event log + <code class="language-plaintext highlighter-rouge">--resume</code></td>
      <td>gVisor snapshot restore</td>
    </tr>
    <tr>
      <td>Branch exploration</td>
      <td><code class="language-plaintext highlighter-rouge">ax fork</code> from checkpoint</td>
      <td>New actor from template</td>
    </tr>
  </tbody>
</table>

<p><strong>AX</strong> owns <strong>execution semantics</strong> — which agent spoke, which tool fired, what was the plan.</p>

<p><strong>Substrate</strong> owns <strong>compute state</strong> — RAM, filesystem, Pod placement.</p>

<p>Long-running agents need both. AX on bare metal or plain Kubernetes works; on Kubernetes, Google recommends <a href="https://github.com/google/ax/blob/main/manifests/README.md">deploying AX on Substrate</a> for actor resumption at the compute layer. Watch the <a href="https://www.youtube.com/watch?v=L5Iw1IrZ6Nc">combined demo</a>.</p>

<h2 id="deployment-on-kubernetes">Deployment on Kubernetes</h2>

<p>AX is compute-agnostic but aims for the best experience on Kubernetes:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Install CLI</span>
go <span class="nb">install </span>github.com/google/ax/cmd/ax@latest

<span class="c"># Production path: AX + Agent Substrate</span>
<span class="c"># See manifests/README.md in the ax repo</span>
</code></pre></div></div>

<p>Google’s <a href="https://cloud.google.com/blog/products/containers-kubernetes/bringing-you-agent-sandbox-on-gke-and-agent-substrate">GKE blog</a> covers Agent Sandbox on GKE plus Substrate as the agent-first compute layer — with AX as the runtime on top. Both AX and Substrate came out of Google’s GKE/agent infrastructure work and were announced together; Substrate carries the standard “not an officially supported Google product” disclaimer, but it is a Google-originated open-source project, not a third-party one.</p>

<h2 id="roadmap">Roadmap</h2>

<p>From the <a href="https://github.com/google/ax">AX README</a>:</p>

<ol>
  <li>Antigravity as built-in harness</li>
  <li>Bring Your Own Harness (BYOH)</li>
  <li>Suspension/resumption of subagents</li>
  <li>Tool call approvals in subagents</li>
  <li>Resumption protocol improvements</li>
</ol>

<p>Resumable streaming and agent communication protocols are <strong>actively evolving</strong> — plan for breaking changes.</p>

<h2 id="where-ax-sits-in-the-stack">Where AX sits in the stack</h2>

<table>
  <thead>
    <tr>
      <th>Layer</th>
      <th>Examples</th>
      <th>Question</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Model</td>
      <td>Gemini, Claude, DeepSeek</td>
      <td>What generates tokens?</td>
    </tr>
    <tr>
      <td>Framework</td>
      <td>LangGraph, ADK, CrewAI</td>
      <td>How is logic structured?</td>
    </tr>
    <tr>
      <td><strong>Runtime</strong></td>
      <td><strong>Google AX</strong></td>
      <td>How is execution durable and auditable?</td>
    </tr>
    <tr>
      <td>Compute</td>
      <td><a href="https://www.fratepietro.com/2026/agent-substrate-zero-idle-kubernetes/">Agent Substrate</a></td>
      <td>Where do processes live at scale?</td>
    </tr>
    <tr>
      <td>Cluster</td>
      <td>Kubernetes, GKE</td>
      <td>How is hardware managed?</td>
    </tr>
  </tbody>
</table>

<p>Most teams have models and frameworks. Almost nobody has the runtime and compute rows. That is why demos feel magical and production feels haunted.</p>

<h2 id="honest-limitations">Honest limitations</h2>

<ul>
  <li>Active early development — <strong>PRs temporarily paused</strong></li>
  <li>Resumable streaming protocols <strong>will break</strong> before stable release</li>
  <li>Self-hosted only — you operate clusters, logs, backups</li>
  <li>Collaboration via <code class="language-plaintext highlighter-rouge">ax-dev@google.com</code>; file issues freely</li>
</ul>

<p>If you need something Monday, use Postgres for session state and pray. If you are building agent infrastructure for the next few years, install <code class="language-plaintext highlighter-rouge">ax</code>, run <code class="language-plaintext highlighter-rouge">ax exec</code>, kill your terminal, <code class="language-plaintext highlighter-rouge">--resume</code> with <code class="language-plaintext highlighter-rouge">--last-seq</code>, then <code class="language-plaintext highlighter-rouge">ax trace</code> what happened. An hour well spent.</p>

<h2 id="federating-deployment-models">Federating deployment models</h2>

<p>Google positions AX as a bridge between deployment models — on-prem sovereignty, managed frontier agents, custom LangGraph/ADK builds, A2A-connected agents. You own models, harnesses, and compute; AX provides the <strong>execution contract</strong>: event log, resumption, audit, isolation.</p>

<p>Enterprise adoption of agents needs that contract open-sourced. Google shipped it. Whether it becomes the Linux of agent runtimes or a reference implementation depends on the next twelve months of API stability and community adoption.</p>

<hr />

<p><em>AX: <a href="https://github.com/google/ax">github.com/google/ax</a>, <a href="https://agentexecutor.io">agentexecutor.io</a>. Announcement: <a href="https://cloud.google.com/blog/products/ai-machine-learning/agent-executor-googles-distributed-agent-runtime">Agent Executor blog post</a>. Companion post: <a href="https://www.fratepietro.com/2026/agent-substrate-zero-idle-kubernetes/">Agent Substrate — zero-idle Kubernetes</a>.</em></p>]]></content><author><name>Antonello Fratepietro</name><email>antonello.f at gmail dot com</email></author><category term="Architecture" /><category term="AX" /><category term="Agent Executor" /><category term="Google" /><category term="Agentic AI" /><category term="Event Log" /><category term="Resumption" /><category term="MCP" /><category term="Distributed Systems" /><summary type="html"><![CDATA[Google open-sourced AX (Agent Executor): a self-hosted distributed agent runtime with durable event logs, resumable streams, trajectory forking, and isolated actors. Not a framework, not a managed service — the orchestration layer production agents are missing.]]></summary></entry><entry><title type="html">Agent Substrate: Zero-Idle Kubernetes for Stateful AI Agents</title><link href="https://www.fratepietro.com/2026/agent-substrate-zero-idle-kubernetes/" rel="alternate" type="text/html" title="Agent Substrate: Zero-Idle Kubernetes for Stateful AI Agents" /><published>2026-06-03T00:00:00+02:00</published><updated>2026-06-03T00:00:00+02:00</updated><id>https://www.fratepietro.com/2026/agent-substrate-zero-idle-kubernetes</id><content type="html" xml:base="https://www.fratepietro.com/2026/agent-substrate-zero-idle-kubernetes/"><![CDATA[<p>Every agent demo I have seen works beautifully. Then someone puts it in production and the cloud bill starts climbing for no obvious reason.</p>

<p>The reason is boring once you see it. The demo keeps one process warm on a laptop. Production maps one user session to one Kubernetes Pod, bills you for RAM while the agent sits waiting on a model, a tool, or a human, and still loses its context the moment you scale to zero. Agents spend most of their life idle — waiting for an event, a token, a click — yet the standard setup forces a bad trade: pay for memory that does nothing, or cold-boot and throw away volatile state.</p>

<p><a href="https://github.com/agent-substrate/substrate"><strong>Agent Substrate</strong></a> is an open-source project aimed squarely at that problem. It was introduced in 2026 by Google’s GKE team — announced alongside <a href="https://cloud.google.com/blog/products/containers-kubernetes/bringing-you-agent-sandbox-on-gke-and-agent-substrate">Agent Sandbox on GKE</a> and <a href="https://www.fratepietro.com/2026/google-ax-distributed-agent-runtime/">Agent Executor (AX)</a> — and developed in the open with the community (Solo.io’s <a href="https://kagent.dev/">kagent</a> team contributed work from a near-identical project). One caveat worth stating up front, because the README states it: this is <strong>not an officially supported Google product</strong>. It is a Google-led open-source effort, not a GCP service with an SLA.</p>

<p>What it gives you is a <strong>session-centric, zero-idle architecture</strong> on Kubernetes: decouple logical <strong>actors</strong> from physical <strong>workers</strong>, suspend and resume process state in well under a second, and multiplex many stateful sessions onto a small warm pool of pods.</p>

<p>This is the <strong>compute layer</strong> of the agent stack — where processes live, hibernate, and teleport. For the <strong>orchestration layer</strong> (event logs, trajectory forking, audit trails), see the companion post on <a href="https://www.fratepietro.com/2026/google-ax-distributed-agent-runtime/">Google AX</a>.</p>

<h2 id="the-stateful-gap-kubernetes-does-not-solve">The stateful gap Kubernetes does not solve</h2>

<p>Agents are not web servers. A web server handles thousands of short requests. An agent handles one long request, goes idle, wakes up, calls tools, blocks on MCP, and dies mid-thought because the node OOM’d.</p>

<p>Traditional Kubernetes optimizes for <strong>thousands of long-running services</strong>. Agent workloads look like <strong>millions of sub-second activations</strong> with long idle tails. One Pod per session is economically absurd. One process per laptop does not survive a deploy.</p>

<p>Substrate targets three operational needs at the <strong>hardware</strong> level:</p>

<ol>
  <li><strong>Suspend and resume</strong> RAM + filesystem in milliseconds — not “restart and replay the prompt”</li>
  <li><strong>Multiplex</strong> idle sessions onto shared workers without cross-talk</li>
  <li><strong>Isolate</strong> arbitrary code execution via sandboxed OCI containers</li>
</ol>

<p>Frameworks solve reasoning. Substrate solves <strong>density and session mobility</strong>.</p>

<h2 id="what-agent-substrate-is-and-is-not">What Agent Substrate is (and is not)</h2>

<p><a href="https://github.com/agent-substrate/substrate">Agent Substrate</a> is <strong>not</strong> an SDK for building agents. It is infrastructure for <strong>running</strong> them — a control plane on top of Kubernetes that maps many <strong>actors</strong> onto fewer <strong>workers</strong> (Pods).</p>

<p>A note on what it is <em>not</em>, because there has been some confusion: it is not a managed, officially supported Google product. The README is explicit about that. But it <em>is</em> a Google-originated open-source project — the GKE team introduced it, it builds directly on Agent Sandbox’s secure runtime and snapshotting, and it lives in its own <a href="https://github.com/agent-substrate"><code class="language-plaintext highlighter-rouge">agent-substrate</code></a> org with an open <a href="https://groups.google.com/g/ate-dev">community</a>. So “Google built it in the open, but does not support it as a product” is the accurate reading — not “independent project Google merely partners with.”</p>

<p>Two vocabulary words appear in every demo and doc:</p>

<ul>
  <li><strong>Actor</strong> — a logical session; a private instance of an agent or any OCI workload</li>
  <li><strong>Worker</strong> — physical compute; typically a pre-initialized Pod in a warm pool</li>
</ul>

<p>Actors are often <strong>suspended upon creation</strong>. They exist logically, cost nothing while idle, and hydrate when traffic arrives. Substrate’s core innovation is this <strong>decoupled lifecycle</strong> — rapid suspend/resume on any worker, state persisting independent of underlying hardware.</p>

<h2 id="watch-the-launch-demo">Watch the launch demo</h2>

<p>The <a href="https://www.youtube.com/watch?v=ZEzkCFJkzjY">Agent Substrate OSS Launch Demo</a> (~8 minutes) walks through the counter demo, a “secret agent” zero-idle pattern, and a boardroom UI scaling to <strong>~250 concurrent agents on eight GKE worker pods</strong> — call it <strong>~30:1 oversubscription</strong>, which lines up with the project’s own “30× more actors than pods” framing.</p>

<div style="position: relative; padding-bottom: 56.25%; height: 0; overflow: hidden; max-width: 100%; margin: 1.5rem 0;">
  <iframe style="position: absolute; top: 0; left: 0; width: 100%; height: 100%;" src="https://www.youtube.com/embed/ZEzkCFJkzjY" title="Agent Substrate OSS Launch Demo" frameborder="0" allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture; web-share" referrerpolicy="strict-origin-when-cross-origin" allowfullscreen=""></iframe>
</div>

<h3 id="what-the-demo-actually-proves">What the demo actually proves</h3>

<p>The video has three acts. Each maps to a <a href="https://github.com/agent-substrate/substrate#demos">repo demo</a>.</p>

<p><strong>Act 1 — Counter: session teleport.</strong> A Go HTTP server keeps an in-memory counter. Create an actor (suspended), resume, increment: 1, 2. Manually suspend, flood the cluster until the <strong>original Pod is occupied</strong>. Substrate resumes on a <strong>new Pod</strong> — <strong>IP changes</strong> — counter reads <strong>3</strong>. Living memory, new hardware.</p>

<p><strong>Act 2 — Secret Agent: zero-idle by default.</strong> A toy agent returns a volatile secret from RAM, then <strong>self-suspends via the Substrate API</strong>. While waiting, it costs nothing. The gateway resumes on inbound traffic in milliseconds; the worker frees automatically after work. <strong>24 agents on eight Pods</strong> — <strong>3:1 oversubscription</strong> — multiplexed in a parallel pulse.</p>

<p><strong>Act 3 — Boardroom UI: swarm at 30× density.</strong> Visual layer on the same APIs as <code class="language-plaintext highlighter-rouge">kubectl-ate</code>. A lead architect actor spawns sub-agents; contention steals warm Pods without leaking context. The architect <strong>hibernates to GCS</strong> when done; a reviewer recalls it on a <strong>different Pod</strong> (<code class="language-plaintext highlighter-rouge">.117</code> → <code class="language-plaintext highlighter-rouge">.121</code>) with state intact. Finale: <strong>~250 agents, eight slots</strong>. Demo claims <strong>~45-second cold boots</strong> replaced by <strong>sub-second rehydration</strong> — treat “97% efficiency” as launch marketing; the snapshot mechanism is the real story.</p>

<p><a href="https://gvisor.dev/">gVisor</a> checkpoint/restore handles RAM and filesystem snapshots. “Instant session teleport” is fair after you watch the counter survive a Pod swap.</p>

<h2 id="architecture">Architecture</h2>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>                    ┌─────────────────────────────────┐
  HTTP / gRPC       │         atenet-router           │
  requests    ───►  │   (DNS + Envoy routing)         │
                    └──────────────┬──────────────────┘
                                   │
                    ┌──────────────▼──────────────────┐
                    │         ate-apiserver           │
                    │   (actor lifecycle, scheduling) │
                    └──────────────┬──────────────────┘
                                   │
         ┌─────────────────────────┼─────────────────────────┐
    ┌────▼────┐              ┌─────▼─────┐             ┌─────▼─────┐
    │ Worker  │              │  Worker   │             │  Worker   │
    │  Pod A  │              │  Pod B    │             │  Pod C    │
    │ actor 1 │◄─suspend──►  │ actor 47  │             │ actor 12  │
    └─────────┘              └───────────┘             └───────────┘
</code></pre></div></div>

<p>Kubernetes provisions nodes and networking. Substrate takes the <strong>Kubernetes control plane out of the hot path</strong> for actor scheduling — critical when wake/sleep cycles happen constantly.</p>

<table>
  <thead>
    <tr>
      <th>Component</th>
      <th>Role</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">ate-apiserver</code></td>
      <td>gRPC control plane — create, destroy, suspend, resume actors</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">atelet</code></td>
      <td>Node DaemonSet — snapshots, state transfer, worker supervision</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">atecontroller</code></td>
      <td>Reconciles <code class="language-plaintext highlighter-rouge">WorkerPool</code> and <code class="language-plaintext highlighter-rouge">ActorTemplate</code> CRDs</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">atenet</code></td>
      <td>DNS, Envoy routing, proxy sidecars</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">ateom-gvisor</code></td>
      <td>In-pod <code class="language-plaintext highlighter-rouge">runsc</code> checkpoint/restore helper</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">kubectl-ate</code></td>
      <td>CLI — <code class="language-plaintext highlighter-rouge">kubectl ate create actor ...</code></td>
    </tr>
  </tbody>
</table>

<h2 id="framework-agnostic-by-design">Framework-agnostic by design</h2>

<p>Substrate manages <strong>OCI containers via gVisor</strong> — it does not care what framework built the agent:</p>

<ul>
  <li><strong>ADK</strong> — session identity and persistent working memory</li>
  <li><strong>LangChain</strong> — long-running stateful agents with sandboxed tools</li>
  <li><strong>Claude Code / Codex</strong> — multiplexed coding environments with terminal state</li>
  <li><strong>MCP servers</strong> — durable, sandboxed tool actors</li>
</ul>

<p>Demos worth running: <a href="https://github.com/agent-substrate/substrate/tree/main/demos/counter">Counter</a>, <a href="https://github.com/agent-substrate/substrate/tree/main/demos/sandbox">Sandbox (Antigravity)</a>, <a href="https://github.com/agent-substrate/substrate/tree/main/demos/claude-code-multiplex">Claude Code Multiplex</a>, <a href="https://github.com/agent-substrate/substrate/tree/main/demos/agent-secret">Secret Agent</a>.</p>

<p><a href="https://github.com/google/ax"><strong>Google AX</strong></a> lists Substrate as its recommended Kubernetes deployment target — AX coordinates agentic loops on top; Substrate provides the dense, resumable compute underneath. The <a href="https://www.youtube.com/watch?v=L5Iw1IrZ6Nc">AX-on-Substrate demo</a> shows the full stack.</p>

<h2 id="quickstart-on-kind">Quickstart on kind</h2>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git clone https://github.com/agent-substrate/substrate.git
<span class="nb">cd </span>substrate

hack/create-kind-cluster.sh
hack/install-ate-kind.sh <span class="nt">--deploy-ate-system</span>
hack/install-ate-kind.sh <span class="nt">--deploy-demo-counter</span>

go <span class="nb">install</span> ./cmd/kubectl-ate
kubectl ate create actor my-counter-1 <span class="nt">--template</span> ate-demo-counter/counter

kubectl port-forward <span class="nt">-n</span> ate-system svc/atenet-router 8000:80
</code></pre></div></div>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>curl <span class="nt">-X</span> POST <span class="se">\</span>
  <span class="nt">-H</span> <span class="s2">"Host: my-counter-1.actors.resources.substrate.ate.dev"</span> <span class="se">\</span>
  <span class="nt">-i</span> http://localhost:8000/
</code></pre></div></div>

<p>Suspend, resume on another worker, counter still increments. One curl captures the value proposition.</p>

<p>GKE quickstart: <code class="language-plaintext highlighter-rouge">go run ./tools/setup-gcp --all</code> then <code class="language-plaintext highlighter-rouge">./hack/install-ate.sh --deploy-ate-system</code>. See the <a href="https://github.com/agent-substrate/substrate">README</a> for teardown and partial deploy flags.</p>

<h2 id="where-substrate-sits-in-the-stack">Where Substrate sits in the stack</h2>

<table>
  <thead>
    <tr>
      <th>Layer</th>
      <th>Examples</th>
      <th>Question</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Framework</td>
      <td>LangGraph, ADK, CrewAI</td>
      <td>How is agent logic structured?</td>
    </tr>
    <tr>
      <td>Runtime</td>
      <td><a href="https://www.fratepietro.com/2026/google-ax-distributed-agent-runtime/">Google AX</a></td>
      <td>How is execution durable and auditable?</td>
    </tr>
    <tr>
      <td><strong>Compute</strong></td>
      <td><strong>Agent Substrate</strong></td>
      <td>Where do processes live at scale?</td>
    </tr>
    <tr>
      <td>Cluster</td>
      <td>Kubernetes, GKE</td>
      <td>How is hardware managed?</td>
    </tr>
  </tbody>
</table>

<p>This is not <strong>inference orchestration</strong> (<a href="https://github.com/antonellof/cognitora-inference">Cognitora</a>) or <strong>local inference</strong> (<a href="https://github.com/antirez/ds4">DwarfStar 4</a>). Substrate is purely <strong>session mobility and hardware efficiency</strong> for agent-shaped workloads.</p>

<h2 id="honest-limitations">Honest limitations</h2>

<ul>
  <li><strong>VERY early development</strong> — APIs guaranteed to change</li>
  <li><strong>Not</strong> an officially supported Google product</li>
  <li>gVisor snapshot path is complex; distributed recovery has edge cases</li>
  <li>PRs may not merge unless aligned with core roadmap</li>
</ul>

<p>If you need production tomorrow, keep plain Kubernetes Jobs. If you are designing agent infrastructure for 2027, run the counter demo on <code class="language-plaintext highlighter-rouge">kind</code> this weekend — suspend an actor, steal its Pod, resume elsewhere, watch the counter keep counting.</p>

<hr />

<p><em>Agent Substrate: <a href="https://github.com/agent-substrate/substrate">github.com/agent-substrate/substrate</a>. Community: <a href="https://groups.google.com/g/ate-dev">ate-dev Google Group</a>, CNCF Slack <code class="language-plaintext highlighter-rouge">#substrate-users</code>. Companion post: <a href="https://www.fratepietro.com/2026/google-ax-distributed-agent-runtime/">Google AX — distributed agent runtime</a>.</em></p>]]></content><author><name>Antonello Fratepietro</name><email>antonello.f at gmail dot com</email></author><category term="Architecture" /><category term="Agent Substrate" /><category term="Kubernetes" /><category term="gVisor" /><category term="Agentic AI" /><category term="MCP" /><category term="Zero-Idle" /><category term="Infrastructure" /><summary type="html"><![CDATA[Agent Substrate is an open-source project from Google's GKE team that multiplexes thousands of stateful agent sessions onto a small pool of Kubernetes pods. Zero-idle architecture, gVisor snapshots, and ~30:1 oversubscription. Here's how session teleport actually works.]]></summary></entry><entry><title type="html">DwarfStar 4: antirez Bets the Farm on Local Inference Done Right</title><link href="https://www.fratepietro.com/2026/dwarfstar-4-local-inference-antirez/" rel="alternate" type="text/html" title="DwarfStar 4: antirez Bets the Farm on Local Inference Done Right" /><published>2026-05-30T00:00:00+02:00</published><updated>2026-05-30T00:00:00+02:00</updated><id>https://www.fratepietro.com/2026/dwarfstar-4-local-inference-antirez</id><content type="html" xml:base="https://www.fratepietro.com/2026/dwarfstar-4-local-inference-antirez/"><![CDATA[<p>Salvatore Sanfilippo — <a href="https://antirez.com">antirez</a>, the person who gave us Redis — has a habit of building things that look obvious in retrospect and impossible before they exist. His latest project, <a href="https://github.com/antirez/ds4"><strong>DwarfStar 4</strong></a> (DS4), is no exception: a small, native inference engine laser-focused on running <strong>DeepSeek V4 Flash</strong> (and PRO on monster machines) locally, end to end, without duct tape.</p>

<p>I did not expect it to blow past <strong>12,000 GitHub stars</strong> within its first few weeks either (it has kept climbing since). But after reading <a href="https://antirez.com/news/165">antirez’s own words on the launch</a> and his follow-up on <a href="https://antirez.com/news/167">distributed inference</a>, the hype makes sense. Three things converged at once: a quasi-frontier open-weights model fast enough to matter on a laptop, an asymmetric 2/8-bit quantization recipe that actually works, and a decade of local-AI experimentation finally paying off — accelerated, as antirez openly admits, by heavy use of GPT 5.5 during development.</p>

<p>This is not a generic GGUF runner. It is a deliberate bet that <strong>local inference should feel finished</strong>, not merely possible.</p>

<h2 id="the-problem-ds4-refuses-to-solve">The problem DS4 refuses to solve</h2>

<p>The local LLM landscape is a graveyard of half-integrated projects. A new model drops. Someone ports it to <a href="https://github.com/ggml-org/llama.cpp">llama.cpp</a>. Tool calling breaks. Context windows shrink mysteriously. KV cache eats all your RAM. You wire up Ollama, then Open WebUI, then a coding agent, then wonder why the 284B-parameter MoE feels dumber than the 27B dense model you replaced.</p>

<p>DS4 takes the opposite approach, stated plainly in the <a href="https://github.com/antirez/ds4">README</a>:</p>

<blockquote>
  <p><em>Not a generic GGUF runner, not a wrapper around another runtime — completely self-contained.</em></p>
</blockquote>

<p>The vision is three pieces working together out of the box:</p>

<ol>
  <li><strong>Inference engine</strong> with HTTP API and CLI</li>
  <li><strong>GGUF files crafted for that engine</strong> — validated against official logits, not “close enough”</li>
  <li><strong>Testing and agent integration</strong> so you know it works before you trust it with your codebase</li>
</ol>

<p>The model may change over time — antirez expects future DeepSeek checkpoints, maybe <code class="language-plaintext highlighter-rouge">ds4-coding</code>, <code class="language-plaintext highlighter-rouge">ds4-legal</code>, <code class="language-plaintext highlighter-rouge">ds4-medical</code> variants — but the constraint stays: <strong>one best open-weights model at a time, practically fast on high-end personal hardware</strong>.</p>

<p>That narrowness is the feature. Redis did not try to be a general-purpose database. DS4 does not try to be a general-purpose inference server.</p>

<h2 id="why-deepseek-v4-flash-specifically">Why DeepSeek V4 Flash, specifically?</h2>

<p>After weeks of comparisons, the DS4 team argues Flash deserves its own engine for reasons that matter in daily use, not just on benchmarks:</p>

<ul>
  <li><strong>Thinking mode that scales with problem complexity.</strong> Enable thinking on many models and watch them monologue for 8,000 tokens about a two-line bug. Flash’s thinking section is often ~1/5 the length of competitors and proportional to actual difficulty — making thinking mode usable locally where it was previously a curiosity.</li>
  <li><strong>A 1-million-token context window</strong> with aggressively compressed KV cache — and DS4 treats that cache as a <strong>first-class disk citizen</strong>, not something that must live in RAM until your MacBook fans sound like a jet engine.</li>
  <li><strong>Edge-of-knowledge sampling.</strong> Ask niche political or cultural questions and 284B routed MoE parameters show up. Dense 27B–35B models feel smaller in ways that are hard to benchmark but obvious in conversation.</li>
  <li><strong>Asymmetric 2-bit quantization that is not a joke.</strong> Only routed MoE experts get crushed to 2-bit (<code class="language-plaintext highlighter-rouge">IQ2_XXS</code> up/gate, <code class="language-plaintext highlighter-rouge">Q2_K</code> down). Shared experts, projections, routing, and attention stay at higher precision. Result: Flash runs on <strong>96–128 GB</strong> MacBooks; PRO fits on <strong>512 GB</strong> Mac Studio class machines.</li>
</ul>

<p>antirez’s blunt assessment in <a href="https://antirez.com/news/165">news/165</a>: if you imagine local models as experience <strong>A</strong> and frontier cloud models as <strong>B</strong>, DS4 is <strong>a lot more B than A</strong>. For the first time in his years of local inference experiments, he uses it for work he’d normally send to Claude or GPT.</p>

<p>I have been running similar experiments on my own hardware. The gap between “toy local model” and “I would actually ship code reviewed by this” has never been smaller.</p>

<h2 id="whats-in-the-box">What’s in the box</h2>

<p>DS4 ships as a handful of native binaries — no Python runtime holding the critical path hostage:</p>

<table>
  <thead>
    <tr>
      <th>Binary</th>
      <th>Role</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">./ds4</code></td>
      <td>Interactive CLI — chat, <code class="language-plaintext highlighter-rouge">/read</code>, session management</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">./ds4-server</code></td>
      <td>OpenAI-compatible HTTP API for external agents</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">./ds4-agent</code></td>
      <td>Native coding agent with on-disk KV sessions</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">./ds4-bench</code></td>
      <td>Throughput measurement at context frontiers</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">./ds4-eval</code></td>
      <td>92-item integration regression suite with TUI</td>
    </tr>
  </tbody>
</table>

<p><strong>Backends:</strong> Metal is the primary target (MacBook Pro/Studio, from 96 GB up). CUDA builds target the <a href="https://www.nvidia.com/en-us/data-center/dgx-spark/">NVIDIA DGX Spark</a> (GB10) and generic Linux GPUs. The README also lists <strong>Strix Halo (ROCm)</strong> — Framework Desktop and similar unified-memory AMD systems — as a backend target, so this is no longer a Mac-only story.</p>

<p>The engine borrows quant layouts, GGUF ecosystem knowledge, and kernel ideas from llama.cpp/GGML (acknowledged prominently in the LICENSE), but <code class="language-plaintext highlighter-rouge">ds4.c</code> is its own inference path — not a fork you <code class="language-plaintext highlighter-rouge">./llama-cli</code> your way through.</p>

<h3 id="getting-started">Getting started</h3>

<p>Download the imatrix-tuned quant that matches your RAM, build, run:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git clone https://github.com/antirez/ds4.git
<span class="nb">cd </span>ds4

<span class="c"># 96/128 GB machines — imatrix-tuned 2-bit (recommended starting point)</span>
./download_model.sh q2-imatrix

<span class="c"># macOS Metal build</span>
make

<span class="c"># Interactive session</span>
./ds4 <span class="nt">-m</span> ds4flash.gguf <span class="nt">--ctx</span> 32768

<span class="c"># OpenAI-compatible server for Cursor, Cline, etc.</span>
./ds4-server <span class="nt">--ctx</span> 100000 <span class="nt">--kv-disk-dir</span> /tmp/ds4-kv <span class="nt">--kv-disk-space-mb</span> 8192
</code></pre></div></div>

<p>Weights live on <a href="https://huggingface.co/antirez/deepseek-v4-gguf">Hugging Face (<code class="language-plaintext highlighter-rouge">antirez/deepseek-v4-gguf</code>)</a>. The download script resumes partial transfers and symlinks <code class="language-plaintext highlighter-rouge">./ds4flash.gguf</code> to your chosen variant. Do not feed it arbitrary GGUF files — tensor layout, quant mix, and optional MTP state are all DS4-specific.</p>

<p><strong>Status:</strong> beta. antirez worked ~14 hours/day the first week (reminiscent of early Redis, he notes). The <code class="language-plaintext highlighter-rouge">ds4-agent</code> is explicitly alpha. Use <code class="language-plaintext highlighter-rouge">--trace</code> and file issues with full session logs when something breaks.</p>

<h2 id="speed-the-numbers-that-matter-locally">Speed: the numbers that matter locally</h2>

<p>Published <a href="https://github.com/antirez/ds4#speed">Metal benchmarks</a> (greedy decode, <code class="language-plaintext highlighter-rouge">--nothink</code>, 32K context) tell a clear hardware story:</p>

<table>
  <thead>
    <tr>
      <th>Machine</th>
      <th>Quant</th>
      <th>Prefill (long prompt)</th>
      <th>Generation</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>MacBook Pro <strong>M5 Max</strong>, 128 GB</td>
      <td>q2</td>
      <td><strong>463 t/s</strong></td>
      <td><strong>~35 t/s</strong></td>
    </tr>
    <tr>
      <td>MacBook Pro M3 Max, 128 GB</td>
      <td>q2</td>
      <td>250 t/s</td>
      <td>~27 t/s</td>
    </tr>
    <tr>
      <td>Mac Studio M3 Ultra, 512 GB</td>
      <td>q2</td>
      <td>468 t/s</td>
      <td>~36 t/s</td>
    </tr>
    <tr>
      <td>Mac Studio M3 Ultra, 512 GB</td>
      <td><strong>PRO</strong> q2</td>
      <td>139 t/s</td>
      <td>~10 t/s</td>
    </tr>
    <tr>
      <td>DGX Spark GB10, 128 GB</td>
      <td>q2</td>
      <td>344 t/s</td>
      <td>~14 t/s</td>
    </tr>
  </tbody>
</table>

<p>The M5 Max numbers align with antirez’s <a href="https://antirez.com/news/167">hardware take</a>: right now, the best local-inference <strong>deal</strong> might literally be a laptop — ~500 t/s prefill and ~35–40 t/s decode on 2-bit Flash for $6–7K. A Mac Studio M3 Ultra with 512 GB runs <strong>PRO</strong> at usable (if not thrilling) ~10–13 t/s decode and ~150 t/s prefill — frontier-class weights at home for ~$12K total spend.</p>

<p>Not cloud-fast. But no API bill, no data leaving your machine, and no “sorry, we’re rate-limiting Pro users again” email.</p>

<p>For thermal sanity on long runs, <code class="language-plaintext highlighter-rouge">--power N</code> throttles GPU duty cycle (50 = half speed, less fan scream). Available on CLI, server, agent, and bench tools.</p>

<h2 id="disk-backed-kv-cache-ram-is-not-the-only-tier">Disk-backed KV cache: RAM is not the only tier</h2>

<p>Most inference stacks assume KV lives in memory or dies. DS4’s design thesis — spelled out in the README — is that <strong>modern NVMe is fast enough to change the equation</strong>, especially with DeepSeek’s compressed cache format.</p>

<p>Practical effect:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>./ds4-server <span class="se">\</span>
  <span class="nt">--ctx</span> 100000 <span class="se">\</span>
  <span class="nt">--kv-disk-dir</span> /tmp/ds4-kv <span class="se">\</span>
  <span class="nt">--kv-disk-space-mb</span> 8192
</code></pre></div></div>

<p>You can run contexts that would evict you from RAM on lesser setups. The native agent stores sessions under <code class="language-plaintext highlighter-rouge">~/.ds4/kvcache</code> with <code class="language-plaintext highlighter-rouge">/save</code>, <code class="language-plaintext highlighter-rouge">/list</code>, <code class="language-plaintext highlighter-rouge">/switch</code> — resuming a saved session skips prefill entirely because the KV state <em>is</em> the session.</p>

<p>This is the kind of architectural choice that sounds incremental and feels revolutionary the first time you <code class="language-plaintext highlighter-rouge">/switch</code> back to a 200K-token debugging session instantly.</p>

<h2 id="the-native-coding-agent">The native coding agent</h2>

<p>Most coding agents treat inference as a black-box HTTP call. DS4’s agent inverts that: <strong>inference is controlled from inside the agent</strong>, no socket boundary on the hot path, tools and system prompt designed vertically for DeepSeek V4.</p>

<p>What that buys you:</p>

<ul>
  <li><strong>Instant tool calling</strong> — no DSML conversion layer; native model format end to end</li>
  <li><strong>KV truth</strong> — session state cannot drift from cache state; they are the same object</li>
  <li><strong>Live prefill progress bar</strong> — sounds cosmetic, matters when you’re waiting on 100K tokens of repo context</li>
  <li><strong>Session switching without re-prefill</strong> — <code class="language-plaintext highlighter-rouge">/switch</code> to another saved conversation and keep going</li>
</ul>

<p>antirez plans to eventually split client/server with a stateful protocol once the agent matures. Today it is alpha — usable, opinionated, not yet “install and forget.”</p>

<p>Pair it with <strong>directional steering</strong> (<a href="https://github.com/antirez/ds4/tree/main/dir-steering"><code class="language-plaintext highlighter-rouge">dir-steering/</code></a>) and you get something antirez highlights in <a href="https://antirez.com/news/165">news/165</a>: the first local setup where vector steering makes the model feel <em>less</em> constrained, not more gimmicky.</p>

<h2 id="distributed-inference-when-one-macbook-is-not-enough">Distributed inference: when one MacBook is not enough</h2>

<p>The <a href="https://github.com/antirez/ds4#distributed-inference">distributed inference docs</a> are where DS4 stops being a laptop toy and starts looking like infrastructure. antirez’s <a href="https://antirez.com/news/167">news/167</a> frames the macro picture: NVIDIA clusters are not getting cheaper, RAM shortages may delay the next Mac Studio Ultra, and tensor parallelism over Thunderbolt is a non-starter (go read NVLink speeds and weep).</p>

<p>DS4 implements <strong>pipeline parallelism</strong> today — split layers across machines, ship activations (small), keep KV shards local:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Machine A — coordinator, layers 0–30</span>
./ds4 <span class="se">\</span>
  <span class="nt">-m</span> gguf/DeepSeek-V4-Pro-Q4K-Layers00-30.gguf <span class="se">\</span>
  <span class="nt">--role</span> coordinator <span class="se">\</span>
  <span class="nt">--layers</span> 0:30 <span class="se">\</span>
  <span class="nt">--listen</span> 169.254.43.68 1234

<span class="c"># Machine B — worker, layers 31 through output head</span>
./ds4 <span class="se">\</span>
  <span class="nt">-m</span> gguf/DeepSeek-V4-Pro-Q4K-Layers-31-output.gguf <span class="se">\</span>
  <span class="nt">--role</span> worker <span class="se">\</span>
  <span class="nt">--layers</span> 31:output <span class="se">\</span>
  <span class="nt">--coordinator</span> 169.254.43.68 1234
</code></pre></div></div>

<p><strong>Prefill</strong> pipelines across the cluster like an assembly line — measured <strong>1.38×–1.85×</strong> speedup on two M5 Max MacBooks over Thunderbolt 5 for long prompts. <strong>Decode</strong> cannot pipeline (autoregression is sequential); expect ~15–20% <em>slowdown</em> vs single machine due to per-token network hops. Distributed inference is for <strong>fitting bigger models</strong> and <strong>faster long prefills</strong>, not faster token generation.</p>

<p>Real-world link comparison from the README (same two hosts, 8K prompt):</p>

<table>
  <thead>
    <tr>
      <th>Link</th>
      <th>Ping</th>
      <th>Prefill</th>
      <th>Generation</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Thunderbolt 5</td>
      <td>0.45 ms</td>
      <td>583 t/s</td>
      <td>25 t/s</td>
    </tr>
    <tr>
      <td>WiFi</td>
      <td>77 ms</td>
      <td>251 t/s</td>
      <td>11 t/s</td>
    </tr>
    <tr>
      <td>Internet VPN</td>
      <td>152 ms</td>
      <td>115 t/s</td>
      <td>4 t/s</td>
    </tr>
  </tbody>
</table>

<p>WiFi works. It is not fun. VPN across continents is for “I need to run the model at all,” not daily driving.</p>

<h3 id="what-comes-next-three-paths-not-one">What comes next: three paths, not one</h3>

<p>antirez outlines three distributed strategies in <a href="https://antirez.com/news/167">news/167</a>:</p>

<ol>
  <li><strong>Pipeline / layer split</strong> (shipped) — duplicate effective memory, accelerate prefill, accept slower decode.</li>
  <li><strong>Expert-parallel vertical split</strong> (experimental) — both machines load full 2-bit weights; route half the MoE experts to each box via Apple RDMA; viable for PRO’s larger routed experts where activation traffic stays tiny.</li>
  <li><strong>Model ensemble</strong> (research) — completely shared-nothing: run <em>different</em> models on different machines, combine logits or pick the lower-perplexity continuation. <a href="https://arxiv.org/abs/2502.18036">Recent work</a> shows ensembles can outperform either model alone — like an implicit two-expert MoE where routing is “who is more confident about the next token.”</li>
</ol>

<p>Tensor parallelism? antirez bets <strong>no</strong> on Apple Thunderbolt vs NVLink. The winning patterns all minimize bytes on the wire.</p>

<p>Two Mac Studio 512 GB machines could run full-size <strong>PRO Q4</strong> today with the split GGUF workflow — antirez demoed ~11.5 t/s generation with balanced ~40 ms local / ~47 ms remote layer times. Frontier weights, no datacenter lease.</p>

<h2 id="honest-caveats-because-antirez-is-honest">Honest caveats (because antirez is honest)</h2>

<p>A few things the README says out loud that most launch posts bury:</p>

<ul>
  <li><strong>AI-assisted development.</strong> Built with heavy GPT 5.5 help. If that offends you, DS4 is not your project. The ideas, testing, and debugging are human-led; the typing is not all hand-crafted C.</li>
  <li><strong>CPU path is for diagnostics only.</strong> On macOS, running CPU inference can <strong>kernel-panic</strong> the machine due to a virtual memory bug. antirez’s comment: <em>“Software sucks.”</em> Metal or CUDA for real work.</li>
  <li><strong>PRO support is experimental</strong> — naturally limited to 512 GB hardware unicorns.</li>
  <li><strong>Distributed protocol has no encryption or auth</strong> — trusted network, same git commit on all nodes.</li>
  <li><strong>MTP speculative decoding</strong> exists but is correctness-gated and currently a slight speedup at best.</li>
</ul>

<p>This transparency is refreshing. Beta software that admits beta beats production software pretending it is done.</p>

<h2 id="how-ds4-fits-the-wider-local-ai-stack">How DS4 fits the wider local-AI stack</h2>

<p>If you are running <strong>datacenter-scale</strong> orchestration — KV-aware routing across dozens of H100s, prefill/decode disaggregation, etcd cluster state — projects like <a href="https://github.com/antonellof/cognitora-inference">Cognitora</a> (which I have written about separately) occupy that lane.</p>

<p>DS4 occupies a different lane entirely: <strong>personal sovereignty</strong>. One developer, one (or two) Apple Silicon boxes, one model family, everything from GGUF validation to coding agent in a single repo. The philosophical overlap with early Redis is striking — optimize one workload brutally well, ship the complete experience, ignore the rest.</p>

<table>
  <thead>
    <tr>
      <th>Dimension</th>
      <th>Generic llama.cpp + Ollama</th>
      <th>DwarfStar 4</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Model scope</td>
      <td>Anything with a GGUF</td>
      <td>DeepSeek V4 Flash/PRO only</td>
    </tr>
    <tr>
      <td>Quant strategy</td>
      <td>Bring your own</td>
      <td>Asymmetric imatrix 2/8-bit, official-logit validated</td>
    </tr>
    <tr>
      <td>KV cache</td>
      <td>RAM-first</td>
      <td>RAM + disk tier, session-native agent</td>
    </tr>
    <tr>
      <td>Agent</td>
      <td>External (Cursor, etc.)</td>
      <td>Native <code class="language-plaintext highlighter-rouge">ds4-agent</code> + OpenAI-compatible server</td>
    </tr>
    <tr>
      <td>Distribution</td>
      <td>None built-in</td>
      <td>Pipeline parallelism across Macs</td>
    </tr>
    <tr>
      <td>Maturity</td>
      <td>Production ecosystem</td>
      <td>Beta, weeks old, moving fast</td>
    </tr>
  </tbody>
</table>

<p>Neither replaces the other. DS4 is the integrated appliance. The generic stack is the swiss army knife.</p>

<h2 id="what-antirez-is-building-toward">What antirez is building toward</h2>

<p>From <a href="https://antirez.com/news/165">news/165</a>, the roadmap reads like a product plan, not a science project:</p>

<ul>
  <li>Quality benchmarks and regression gates (official continuation vectors, <code class="language-plaintext highlighter-rouge">ds4-eval</code>, <code class="language-plaintext highlighter-rouge">ds4-bench</code>)</li>
  <li>A coding agent that graduates from alpha to daily-driver</li>
  <li>Home hardware CI so releases do not depend on “works on Salvatore’s MacBook”</li>
  <li>More ports and distributed modes — serial <strong>and</strong> parallel</li>
  <li>Model churn as DeepSeek ships new checkpoints</li>
</ul>

<p>The closing line stuck with me: <em>“AI is too critical to be just a provided service.”</em></p>

<p>That is the whole argument for DS4 in one sentence. Cloud APIs are convenient. They are also someone else’s computer, someone else’s retention policy, and someone else’s idea of what your prompt should cost this quarter.</p>

<h2 id="bottom-line">Bottom line</h2>

<p>DwarfStar 4 is not the inference engine for everyone. It is the inference engine for people who looked at DeepSeek V4 Flash, checked their MacBook’s RAM, and thought: <em>I want this to actually work — tools, cache, agent, benchmarks, distributed PRO across two Studios — without spending six weekends gluing pieces together.</em></p>

<p>antirez built Redis because developers deserved a better in-memory data store. DS4 comes from the same instinct applied to local LLMs: stop shipping half-finished runtimes and call it progress.</p>

<p>Clone it. Download the imatrix quant. Run <code class="language-plaintext highlighter-rouge">./ds4</code>. See if you, too, end up asking a local model what you used to send to Claude — and getting an answer you can use.</p>

<hr />

<p><em>DwarfStar 4 is under active development. Pin a commit or watch <a href="https://github.com/antirez/ds4">releases</a> if you are deploying beyond weekend experiments. Primary references: <a href="https://github.com/antirez/ds4">antirez/ds4 on GitHub</a>, <a href="https://antirez.com/news/165">A few words on DS4</a>, <a href="https://antirez.com/news/167">Distributing LLM inference in DwarfStar</a>.</em></p>]]></content><author><name>Antonello Fratepietro</name><email>antonello.f at gmail dot com</email></author><category term="Deep Dive" /><category term="DwarfStar" /><category term="DS4" /><category term="Local Inference" /><category term="DeepSeek" /><category term="antirez" /><category term="Metal" /><category term="LLM" /><category term="MoE" /><category term="Distributed Inference" /><summary type="html"><![CDATA[Salvatore Sanfilippo — the mind behind Redis — shipped DwarfStar 4, a purpose-built inference engine for DeepSeek V4 on Apple Silicon. Not another GGUF wrapper: a finished local-AI stack with asymmetric quants, disk-backed KV cache, a native coding agent, and distributed inference across MacBooks. Here's why it collected over 12k GitHub stars almost overnight.]]></summary></entry><entry><title type="html">Cognitora: A Datacenter-Scale, Open-Source LLM Inference Orchestrator (NVIDIA Dynamo Alternative)</title><link href="https://www.fratepietro.com/2026/cognitora-inference-llm-orchestration/" rel="alternate" type="text/html" title="Cognitora: A Datacenter-Scale, Open-Source LLM Inference Orchestrator (NVIDIA Dynamo Alternative)" /><published>2026-05-03T00:00:00+02:00</published><updated>2026-05-03T00:00:00+02:00</updated><id>https://www.fratepietro.com/2026/cognitora-inference-llm-orchestration</id><content type="html" xml:base="https://www.fratepietro.com/2026/cognitora-inference-llm-orchestration/"><![CDATA[<p>I have spent more late nights than I would like to admit gluing inference stacks together, and the shape of the problem is always the same. A single H100 with <a href="https://github.com/vllm-project/vllm">vLLM</a> serves Llama 3 8B at impressive throughput. A single node with <a href="https://github.com/sgl-project/sglang">SGLang</a> handles structured generation beautifully. <a href="https://github.com/NVIDIA/TensorRT-LLM">TensorRT-LLM</a> wrings every last token-per-second out of an NVL72. None of those are a <em>cluster</em>. The moment the workload outgrows one box — or the moment the prefill phase wants different hardware than the decode phase, or the moment a hot prefix shows up on the wrong replica — you are back to writing a routing layer, a KV-cache layer, and a deployment layer yourself.</p>

<p>The two reference points the rest of the industry agrees on are <a href="https://github.com/ai-dynamo/dynamo"><strong>NVIDIA Dynamo</strong></a> (Rust core, Python frontend, Kubernetes-first) and a long tail of generic ML serving stacks: <a href="https://docs.ray.io/en/latest/serve/"><strong>Ray Serve</strong></a>, <a href="https://kserve.github.io/website/"><strong>KServe</strong></a>, <a href="https://github.com/triton-inference-server/server"><strong>NVIDIA Triton Inference Server</strong></a>, <a href="https://github.com/bentoml/BentoML"><strong>BentoML</strong></a>, and the <a href="https://github.com/vllm-project/production-stack"><strong>vLLM Production Stack</strong></a>. Each makes a different tradeoff between “specialized for LLM inference” and “general purpose,” between “one click on a managed cloud” and “I can run it on bare metal in a datacenter I own.”</p>

<p><a href="https://github.com/antonellof/cognitora-inference"><strong>Cognitora</strong></a> is an open-source LLM inference orchestration layer that lands in a deliberately specific spot in that design space: <strong>bare-metal-first, Rust-only, engine-agnostic, KV-cache-aware</strong>. It does not replace vLLM or SGLang — it coordinates them into a cluster. It is distributed as six statically-linked binaries with no Python control plane, no JVM operator, and no hard Kubernetes dependency. The same artifacts run as systemd units on a rack of servers, as recipes or <code class="language-plaintext highlighter-rouge">docker compose</code> on a single host, via a Helm chart on Kubernetes, or as Terraform-provisioned VMs across AWS, GCP, Azure, and Hetzner.</p>

<p>As of <strong><a href="https://github.com/antonellof/cognitora-inference/releases/tag/v0.3.0">v0.3.0</a></strong> (May 2026), the OpenAI-compatible surface includes <strong><code class="language-plaintext highlighter-rouge">/v1/chat/completions</code></strong>, <strong><code class="language-plaintext highlighter-rouge">/v1/completions</code></strong>, <strong><code class="language-plaintext highlighter-rouge">/v1/embeddings</code></strong> (real round-trip to the engine, not synthetic vectors), and <strong><code class="language-plaintext highlighter-rouge">/v1/models</code></strong>. The admin CLI <strong><code class="language-plaintext highlighter-rouge">cgn-ctl</code></strong> reads and writes <strong>etcd</strong> for cluster state (<code class="language-plaintext highlighter-rouge">cluster nodes</code>, cordon/drain, <code class="language-plaintext highlighter-rouge">model load/unload</code>), and <strong><code class="language-plaintext highlighter-rouge">cgn-ctl install --target single-node --apply</code></strong> can render <code class="language-plaintext highlighter-rouge">cognitora.toml</code> plus <code class="language-plaintext highlighter-rouge">compose.yaml</code> and bring the stack up with one command. <strong><code class="language-plaintext highlighter-rouge">cgn-metrics</code></strong> exposes Prometheus federation at <strong><code class="language-plaintext highlighter-rouge">/federate</code></strong> so upstream Prometheus scrapes a single endpoint with per-component labels. There is also a <strong>single-manifest Kubernetes quickstart</strong> (etcd + llama.cpp engine + router + agent + metrics in one Pod, LoadBalancer on port 80) that has been exercised end-to-end on <strong>GKE Autopilot</strong>—details in the “Try it” section below.</p>

<p>This post is the long-form version of <em>why that combination of choices</em>, and what falls out of them.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># One-line install — six static binaries, no runtime deps (pin a release for reproducibility)</span>
curl <span class="nt">-fsSL</span> https://raw.githubusercontent.com/antonellof/cognitora-inference/main/deploy/installer/install.sh | <span class="nv">CGN_VERSION</span><span class="o">=</span>v0.3.0 sh

<span class="c"># Bring up Llama-3.1 8B on a single GPU with vLLM</span>
bash recipes/llama3-8b/vllm/agg/up.sh
<span class="c"># Equivalent:</span>
<span class="c"># cgn-ctl recipe up llama3-8b/vllm/agg</span>

<span class="c"># Same model, prefill/decode disaggregated across two GPUs</span>
bash recipes/llama3-8b/vllm/disagg-single-node/up.sh

<span class="c"># Single-node Docker install (writes cognitora.toml + compose.yaml, optional --apply)</span>
cgn-ctl <span class="nb">install</span> <span class="nt">--target</span> single-node <span class="nt">--model</span> llama3-8b <span class="nt">--engine</span> vllm <span class="nt">--apply</span>
</code></pre></div></div>

<h2 id="the-thing-inference-engines-dont-do">The thing inference engines don’t do</h2>

<p>A modern inference engine is a token factory. Hand it a request, get tokens back. The contract is “one process, one model, one node.” Everything outside that contract — which replica should serve this request, which replica already has the system prompt cached on-GPU, when to spill cold KV blocks to RAM or SSD, when to migrate a long-context request from a prefill-optimized box to a decode-optimized one, how to weight a thermally-throttled GPU in the routing decision — is, from the engine’s point of view, somebody else’s problem.</p>

<p>Historically <em>somebody else</em> was a stack of glue: an Nginx in front, a Redis for KV metadata, a Python scheduler reading Prometheus, a Kubernetes operator reconciling deployments, a custom autoscaler. That stack works. It is also five processes in five languages with five failure modes, and it is the part of the system that has the worst observability story precisely when an SRE needs it most — at 03:00 on the first day a new model is in production.</p>

<p>The Cognitora bet is that the orchestration layer should be <strong>one runtime, in Rust, with a small surface area</strong>. Six binaries, each one statically linked, each one with a well-defined responsibility:</p>

<table>
  <thead>
    <tr>
      <th>Binary</th>
      <th>Job</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cgn-router</code></td>
      <td>OpenAI-compatible HTTP gateway + KV-aware routing</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cgn-agent</code></td>
      <td>Per-node engine supervisor + NVML telemetry</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cgn-kvcached</code></td>
      <td>Tiered KV cache daemon (GPU / RAM / SSD) + QUIC/RDMA peer fetch</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cgn-metrics</code></td>
      <td>Prometheus aggregator + federation <code class="language-plaintext highlighter-rouge">/federate</code>; Redfish/IPMI/DCGM where available</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cgn-ctl</code></td>
      <td>Admin CLI — etcd-backed <code class="language-plaintext highlighter-rouge">cluster</code>/<code class="language-plaintext highlighter-rouge">model</code>, single-node <code class="language-plaintext highlighter-rouge">install</code>, PKI, bench</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cgn-operator</code></td>
      <td>Optional Kubernetes operator (kube-rs)</td>
    </tr>
  </tbody>
</table>

<p>The <code class="language-plaintext highlighter-rouge">cgn-operator</code> is optional on purpose. If you run on bare metal, the systemd path is a first-class citizen rather than the “deprecated, please use the Helm chart” path that most cloud-native projects eventually push you toward.</p>

<h2 id="kv-aware-routing-the-routing-decision-is-the-product">KV-aware routing: the routing decision is the product</h2>

<p>The single biggest lever in multi-node LLM inference is <em>not</em> token throughput. It is <strong>KV cache reuse</strong>. If a request shares a 4,000-token system prompt with a request that finished 200 ms ago on replica B, sending the new request to replica B saves 4,000 tokens of prefill compute. Sending it to replica A — because round-robin said so — burns a GPU-second to recompute something that already exists in HBM somewhere else in the cluster. At fleet scale that decision dominates everything else.</p>

<p>There are two common ways to encode “which replica has which prefix”:</p>

<ol>
  <li><strong>Radix trees over chained block hashes.</strong> This is what Dynamo’s KV-aware router uses. Each block of KV is hashed; the cluster maintains a radix tree keyed on those hashes; the router descends the tree to find the deepest match. Fast, memory-efficient, the canonical structure.</li>
  <li><strong>Sequence-chained BLAKE3 digests with longest-prefix overlap.</strong> This is Cognitora’s choice. Each block’s digest is chained from the previous block’s digest, so the digest at position <code class="language-plaintext highlighter-rouge">i</code> summarizes the entire prefix <code class="language-plaintext highlighter-rouge">[0..i]</code>. Routing becomes “which replica reports the deepest prefix match against this digest sequence?”</li>
</ol>

<p>The two approaches are close cousins. The motivating difference for Cognitora is <strong>positional correctness on interleaved requests</strong>. With a chained digest, two requests that share tokens out of order — same content, different positions — produce different chains, so the router does not falsely claim a cache hit that would force the engine to recompute or, worse, return a positionally incorrect KV. On real-world traces with heavy system-prompt sharing the practical hit ratio sits at <strong>≥ 0.55</strong>, and the routing decision itself is sub-millisecond:</p>

<table>
  <thead>
    <tr>
      <th>Metric</th>
      <th>Target</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cgn-router</code> routing decision p99</td>
      <td>&lt; 500 µs / vCPU</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cgn-router</code> HTTP overhead vs direct engine</td>
      <td>&lt; 3 ms p99</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cgn-kvcached</code> warm tier hit</td>
      <td>&lt; 200 µs</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cgn-kvcached</code> cold tier hit (SSD)</td>
      <td>&lt; 5 ms</td>
    </tr>
    <tr>
      <td>Cross-node QUIC fetch (1 MiB block, 10 GbE)</td>
      <td>&lt; 12 ms</td>
    </tr>
    <tr>
      <td>Representative cache hit ratio</td>
      <td>≥ 0.55</td>
    </tr>
    <tr>
      <td>Energy efficiency vs round-robin baseline</td>
      <td>≥ 1.4×</td>
    </tr>
  </tbody>
</table>

<p>Worth flagging the obvious caveat: those are the project’s stated targets, not numbers measured on your traffic. The shape of the metrics matters more than the absolute values — sub-millisecond routing, single-digit-millisecond HTTP overhead, sub-200-µs warm hits. If any of those numbers grew by an order of magnitude the architecture would fall apart, so they are useful as a sanity envelope.</p>

<h2 id="disaggregation-prefill-and-decode-want-different-hardware">Disaggregation: prefill and decode want different hardware</h2>

<p>Prefill is compute-bound. Decode is memory-bandwidth-bound. Running both on the same SKU is a compromise — you either over-provision compute for the decode phase or starve memory bandwidth for the prefill phase. The fix, popularized by <a href="https://arxiv.org/abs/2401.09670">DistServe</a> and now standard in production stacks, is <strong>disaggregated inference</strong>: prefill on one pool of GPUs, decode on another, with the KV blocks streamed between them.</p>

<p>Cognitora handles disaggregation through the <a href="https://github.com/ai-dynamo/nixl">NIXL</a> connector — the same NVIDIA-developed transport library Dynamo uses — and exposes the choice as a single TOML knob:</p>

<div class="language-toml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">[</span><span class="n">engine</span><span class="k">]</span>
<span class="n">kv_offload</span> <span class="o">=</span><span class="w"> </span><span class="s">"nixl"</span>   <span class="c"># one of: none | nixl | lmcache | hicache | kvbm</span>
</code></pre></div></div>

<p>That single knob renders the right engine argv for vLLM, SGLang, or TensorRT-LLM. The recipe folders ship the topologies most people actually want — <code class="language-plaintext highlighter-rouge">recipes/llama3-8b/vllm/agg/</code>, <code class="language-plaintext highlighter-rouge">recipes/llama3-8b/vllm/disagg-single-node/</code>, <code class="language-plaintext highlighter-rouge">recipes/llama3-70b/vllm/agg/</code> — so you do not have to translate “I want 70B FP8 on 4×H100 with TP=4 and disaggregation off” into engine-specific flags.</p>

<p>Engine support matrix:</p>

<table>
  <thead>
    <tr>
      <th>Engine</th>
      <th>KV routing</th>
      <th>Disaggregation</th>
      <th>KV offload backends</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>vLLM</td>
      <td>yes</td>
      <td>NIXL</td>
      <td>LMCache, KVBM, multi-tier</td>
    </tr>
    <tr>
      <td>SGLang</td>
      <td>yes</td>
      <td>NIXL</td>
      <td>HiCache, multi-tier</td>
    </tr>
    <tr>
      <td>TensorRT-LLM</td>
      <td>yes</td>
      <td>NIXL</td>
      <td>KVBM (WIP), multi-tier</td>
    </tr>
    <tr>
      <td>llama.cpp</td>
      <td>yes</td>
      <td>n/a</td>
      <td>multi-tier</td>
    </tr>
    <tr>
      <td>OpenAI-compat</td>
      <td>yes</td>
      <td>n/a</td>
      <td>n/a (Ollama, hosted APIs)</td>
    </tr>
  </tbody>
</table>

<p>llama.cpp and OpenAI-compatible servers as <strong>first-class engines</strong> — not “we tolerate them, here is a config flag” — is a genuine differentiator. It means the same router that fronts your H100 fleet can also fan requests out to a developer’s Ollama on a Mac mini, or to a hosted Anthropic / OpenAI / Together endpoint when on-prem capacity is saturated. That changes what cluster topologies are reasonable to consider.</p>

<h2 id="tiered-kv-cache--cross-cluster-federation">Tiered KV cache + cross-cluster federation</h2>

<p>The KV cache is a hierarchy in any non-trivial deployment: GPU HBM is hot and small, system RAM is warm and bigger, SSD is cold and effectively unbounded. <code class="language-plaintext highlighter-rouge">cgn-kvcached</code> materializes that hierarchy as one daemon with explicit tier latencies (sub-200 µs warm, sub-5 ms cold) and a <strong>QUIC peer-fetch path</strong> between nodes — so a cache miss on node A that lives in node B’s RAM does not become a recompute, it becomes a 12 ms cross-node fetch.</p>

<p>The federation piece is the part that surprised me on first read. Cognitora’s router can form a <strong>federation across clusters</strong>, not just nodes — meaning a hot prefix that exists in your Frankfurt region can serve a request that landed on your Virginia router, if the prefill cost amortized across the network round-trip beats recomputing locally. Most production stacks do not even attempt this; they treat each cluster as an island. Whether that capability is <em>worth the operational complexity</em> depends entirely on your traffic shape, and Cognitora makes the right call by leaving it off by default.</p>

<p>Separately, <strong><code class="language-plaintext highlighter-rouge">cgn-metrics</code></strong> solves a smaller but universal ops problem: <strong>in-cluster Prometheus federation</strong>. Configure scrape targets in TOML and the daemon unions every target’s <code class="language-plaintext highlighter-rouge">/metrics</code> text, injects a <code class="language-plaintext highlighter-rouge">cgn_target="&lt;name&gt;"</code> label on each line, and serves the combined exposition at <strong><code class="language-plaintext highlighter-rouge">/federate</code></strong> — one scrape for your central Prometheus, without parsing the full metric stream twice. That is observability plumbing, not cross-region routing; both use the word “federation” but they are different mechanisms.</p>

<h2 id="energy-aware-scheduling">Energy-aware scheduling</h2>

<p>The bit of the design I like most aesthetically is also the one with the least proven impact: routing decisions can incorporate <strong>power telemetry from Redfish, IPMI, and DCGM</strong>. A GPU that is thermally throttled, or a node whose PSU is drawing closer to its budget than its neighbors, gets weighted down in admission control. The stated efficiency target — <strong>≥ 1.4× over a round-robin baseline</strong> — is plausible on workloads where the cluster is power-limited rather than compute-limited, which is increasingly the situation in modern racks where power per rack-U is the binding constraint.</p>

<p>I would not buy a system <em>because</em> of energy-aware scheduling alone. I would treat it as a strong tiebreaker if it is otherwise the right shape — and it is one of the explicit gaps in Dynamo today, which doesn’t surface power telemetry into routing.</p>

<h2 id="cognitora-vs-nvidia-dynamo">Cognitora vs NVIDIA Dynamo</h2>

<p>Dynamo is the obvious comparison and the most capable alternative. The two projects share a lot of DNA — Rust core, KV-aware routing, NIXL-based disaggregation, Prometheus telemetry — and disagree on a small number of important things.</p>

<table>
  <thead>
    <tr>
      <th>Aspect</th>
      <th>Cognitora</th>
      <th>NVIDIA Dynamo</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Runtime artifact</td>
      <td>Six static Rust binaries (no Python control plane)</td>
      <td>Rust core + Python frontend</td>
    </tr>
    <tr>
      <td>First-class engines</td>
      <td>vLLM, SGLang, TRT-LLM, <strong>llama.cpp</strong>, <strong>OpenAI-compat</strong></td>
      <td>vLLM, SGLang, TRT-LLM</td>
    </tr>
    <tr>
      <td>KV routing signal</td>
      <td>Sequence-chained BLAKE3 + longest-prefix overlap</td>
      <td>Radix tree on chained block hashes</td>
    </tr>
    <tr>
      <td>KV offload selection</td>
      <td>Single TOML knob (<code class="language-plaintext highlighter-rouge">none/nixl/lmcache/hicache/kvbm</code>)</td>
      <td>KVBM + LMCache + FlexKV (separate scripts)</td>
    </tr>
    <tr>
      <td>Multi-tier KV</td>
      <td>RAM + SSD + cross-cluster QUIC peer fetch</td>
      <td>Full G1–G4 (KVBM owns GPU/Host/SSD/remote)</td>
    </tr>
    <tr>
      <td>Cross-cluster federation</td>
      <td>yes — QUIC peer fetch + router federation</td>
      <td>single cluster only</td>
    </tr>
    <tr>
      <td>Multi-model cascade</td>
      <td>yes — SLM→LLM logprob gating</td>
      <td>partial</td>
    </tr>
    <tr>
      <td>Energy / power telemetry</td>
      <td>yes — Redfish + IPMI + DCGM</td>
      <td>not yet</td>
    </tr>
    <tr>
      <td>Deployment surfaces</td>
      <td>Bare metal, Docker Compose, K8s manifest or Helm (chart local path today), Terraform (modules WIP)</td>
      <td>Kubernetes-first (operator + CRDs)</td>
    </tr>
    <tr>
      <td>Multimodal / video pipelines</td>
      <td>not yet</td>
      <td>yes — Image E/P/D, FastVideo, SGLang Diffusion</td>
    </tr>
    <tr>
      <td>Gang scheduling</td>
      <td>basic (node selectors)</td>
      <td>Grove (NVL72-aware)</td>
    </tr>
    <tr>
      <td>Install surface</td>
      <td>one curl line, six static binaries</td>
      <td>pip, container, or operator</td>
    </tr>
  </tbody>
</table>

<p>Reading that table honestly: <strong>if your workload is multimodal, video, or NVL72-shaped, pick Dynamo today.</strong> That is where NVIDIA’s investment is showing through. If your workload is text-only LLM serving on heterogeneous hardware (mix of H100 / L40S / older Ampere / on-prem llama.cpp / hosted API fallback), if you do not want a Python control plane in the hot path, if you care about cross-cluster federation, or if you operate a power-constrained rack and want telemetry to feed the scheduler — Cognitora is the closer fit.</p>

<p>The <em>llama.cpp + OpenAI-compat</em> line is the one I would emphasize most to anyone considering this for a real deployment. It changes what “the cluster” can include. A company-internal cluster that is allowed to burst to a hosted API during a traffic spike has a very different cost curve than a cluster that has to provision for peak.</p>

<h2 id="cognitora-vs-the-rest-of-the-field">Cognitora vs the rest of the field</h2>

<p>Dynamo is the closest comparison; the broader field is worth a paragraph each because the alternatives genuinely have different jobs.</p>

<p><strong><a href="https://github.com/vllm-project/production-stack">vLLM Production Stack</a></strong> is the most natural alternative if you are vLLM-only and Kubernetes-native. It ships a router, autoscaler, and observability stack tuned for vLLM. Cognitora is the right pick if “vLLM-only” is not a constraint you want to commit to — most production fleets end up running at least two engines (vLLM + SGLang for structured output, or vLLM + TRT-LLM for the largest models) and the multi-engine story is easier on Cognitora’s side.</p>

<p><strong><a href="https://docs.ray.io/en/latest/serve/">Ray Serve</a></strong> is the right answer if you already run Ray, or if your inference workload is genuinely heterogeneous (LLM + classical ML + Python preprocessing + tool calls all in one DAG). Ray’s strength is composability across arbitrary Python workloads. Cognitora’s strength is being narrowly excellent at the LLM-serving slice — no Python in the data path, no Ray cluster to operate, no actor model to reason about.</p>

<p><strong><a href="https://kserve.github.io/website/">KServe</a></strong> is the Kubernetes-native, model-serving-CRD answer. It is the right fit when “this is one of forty model deployments my platform team manages, and they all need to look the same in the cluster.” If LLM inference is the workload your platform team primarily exists to serve, the abstraction layer KServe imposes starts costing more than it saves.</p>

<p><strong><a href="https://github.com/triton-inference-server/server">NVIDIA Triton Inference Server</a></strong> is still excellent for <em>non-LLM</em> inference — vision, audio, classical models — and increasingly for LLMs via the TensorRT-LLM backend. If your fleet is mostly non-LLM with LLM as a side workload, Triton is the centerpiece. If LLM is the workload, the LLM-specific systems (Cognitora, Dynamo, vLLM Production Stack) are a better starting point because the things they specialize in — KV routing, prefill/decode disaggregation, prefix sharing — are not a thing Triton optimizes for at the platform level.</p>

<p><strong><a href="https://github.com/bentoml/BentoML">BentoML</a></strong> lives at a different altitude. It is excellent at “package this Python model + preprocessing + business logic into a deployable artifact.” It is not, and does not try to be, a multi-node KV-aware orchestrator. The two compose: BentoML for service packaging, Cognitora (or Dynamo) for cluster-level orchestration of LLM-specific concerns.</p>

<p>The honest summary is that LLM serving has bifurcated into two layers that used to be one. The lower layer is “given a request and a replica, generate tokens efficiently” — vLLM, SGLang, TRT-LLM, llama.cpp own this. The upper layer is “given a fleet, route requests so KV is reused and disaggregation pays off” — Dynamo and Cognitora are the two open-source projects that take this layer seriously as a standalone product. Generic ML serving stacks (KServe, Triton, Ray Serve, BentoML) cover the upper layer for general workloads but do not optimize for the LLM-specific signals that turn out to dominate cost.</p>

<h2 id="multi-model-cascades">Multi-model cascades</h2>

<p>One smaller capability worth calling out because it has outsized cost impact: <strong>multi-model cascades with logprob gating</strong>. The idea is old — route easy queries to a small model, fall back to a large model only when the small one is uncertain — but the orchestrator has to support it natively or it becomes a Python-in-the-hot-path workaround. Cognitora exposes it as a routing policy:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>small_model = "qwen3-7b"
large_model = "llama3-70b"
gate        = "logprob"     # escalate when small-model logprob &lt; threshold
</code></pre></div></div>

<p>For workloads where ~70% of requests are genuinely simple (classification-shaped, lookup-shaped, short-answer chat), this cuts cost dramatically without touching tail quality. Dynamo has partial support; in Cognitora it is a first-class router policy.</p>

<h2 id="honest-limits">Honest limits</h2>

<p>A few things I would want to know before betting a production deployment on this:</p>

<ul>
  <li><strong>Pre-1.0.</strong> The OpenAI-compatible HTTP surface is stable; internal gRPC APIs and the TOML config surface may still shift in minor releases. Pin <strong><code class="language-plaintext highlighter-rouge">CGN_VERSION=v0.3.0</code></strong> (or newer) on the install script and read the <a href="https://github.com/antonellof/cognitora-inference/blob/main/CHANGELOG.md">changelog</a>.</li>
  <li><strong>Helm chart maturity.</strong> The chart under <code class="language-plaintext highlighter-rouge">deploy/kubernetes/helm/cognitora/</code> exists and <code class="language-plaintext highlighter-rouge">helm lint</code> passes in CI, but <strong>there is no published OCI chart at <code class="language-plaintext highlighter-rouge">oci://ghcr.io/…</code> yet</strong>—you install from a <strong>local chart path</strong> or use the <strong>quickstart manifest</strong> below until the chart ships optional engine sidecars and a simpler dev-default TLS story. Terraform modules for cloud VMs are still thin stubs; the credible cloud path today is <strong>bring your own cluster</strong> + quickstart or Helm from a git checkout.</li>
  <li><strong>No multimodal/video.</strong> If your roadmap includes image generation or video diffusion serving, Dynamo is ahead. The Cognitora architecture has no in-principle obstacle here, but the engine integrations are not shipped today.</li>
  <li><strong>Gang scheduling is basic.</strong> Node selectors, not <a href="https://github.com/NVIDIA/grove">Grove</a>-style NVL72-aware co-scheduling. If you operate NVL72 racks and need topology-aware placement, Dynamo is the better fit until this lands.</li>
  <li><strong>The performance numbers are targets, not benchmarks on your traffic.</strong> The architecture supports them; whether your specific workload realizes them depends on prefix sharing, request shape, and hardware mix. The right move on a new deployment is to A/B against round-robin on a slice of real traffic and measure. CI runs a <strong>soft</strong> perf gate (<code class="language-plaintext highlighter-rouge">cargo bench</code> on routing/prefix paths, non-blocking on PRs); hard regression gating is planned once baselines stabilize.</li>
  <li><strong>The cross-cluster federation story is powerful and operationally heavy.</strong> Turn it on only when you actually have multi-region traffic that benefits from it. The defaults are sensibly conservative.</li>
</ul>

<h2 id="try-it">Try it</h2>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Install — six static binaries, no runtime deps (pin the release)</span>
curl <span class="nt">-fsSL</span> https://raw.githubusercontent.com/antonellof/cognitora-inference/main/deploy/installer/install.sh | <span class="nv">CGN_VERSION</span><span class="o">=</span>v0.3.0 sh

<span class="c"># Bring up Llama-3.1 8B on a single GPU with vLLM</span>
bash recipes/llama3-8b/vllm/agg/up.sh

<span class="c"># Disaggregated prefill/decode on two GPUs in one node</span>
bash recipes/llama3-8b/vllm/disagg-single-node/up.sh

<span class="c"># Llama-3.3 70B FP8 on 4×H100 with TP=4</span>
<span class="nv">HF_TOKEN</span><span class="o">=</span>… bash recipes/llama3-70b/vllm/agg/up.sh

<span class="c"># Admin: inspect nodes / desired models in etcd (needs etcd endpoints in cognitora.toml)</span>
cgn-ctl cluster nodes
cgn-ctl model <span class="nb">ls</span>
</code></pre></div></div>

<p><strong>Kubernetes — fastest path to a public URL</strong> (CPU demo: TinyLlama via llama.cpp in-cluster; no GPU quota required). Validated on GKE Autopilot; same manifest works on other clouds or local clusters (use port-forward if LoadBalancer stays pending):</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl apply <span class="nt">-f</span> https://raw.githubusercontent.com/antonellof/cognitora-inference/main/deploy/kubernetes/quickstart/cognitora-cpu.yaml
kubectl <span class="nt">-n</span> cognitora <span class="nb">wait</span> <span class="nt">--for</span><span class="o">=</span><span class="nv">condition</span><span class="o">=</span>ready pod <span class="nt">-l</span> <span class="nv">app</span><span class="o">=</span>cognitora <span class="nt">--timeout</span><span class="o">=</span>10m
<span class="nv">IP</span><span class="o">=</span><span class="si">$(</span>kubectl <span class="nt">-n</span> cognitora get svc cognitora-router <span class="nt">-o</span> <span class="nv">jsonpath</span><span class="o">=</span><span class="s1">'{.status.loadBalancer.ingress[0].ip}'</span><span class="si">)</span>
curl <span class="nt">-sS</span> <span class="s2">"http://</span><span class="nv">$IP</span><span class="s2">/v1/chat/completions"</span> <span class="se">\</span>
  <span class="nt">-H</span> <span class="s1">'Content-Type: application/json'</span> <span class="se">\</span>
  <span class="nt">-d</span> <span class="s1">'{"model":"tinyllama","messages":[{"role":"user","content":"What is 2+2?"}]}'</span>
</code></pre></div></div>

<p><strong>Kubernetes — Helm from a git checkout</strong> (production-shaped chart; wire your own engine / GPU pool—the chart assumes mTLS material unless you adjust values):</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git clone https://github.com/antonellof/cognitora-inference.git <span class="o">&amp;&amp;</span> <span class="nb">cd </span>cognitora-inference
helm <span class="nb">install </span>cognitora ./deploy/kubernetes/helm/cognitora <span class="se">\</span>
  <span class="nt">--namespace</span> cognitora <span class="nt">--create-namespace</span> <span class="se">\</span>
  <span class="nt">--set</span> router.replicas<span class="o">=</span>2 <span class="se">\</span>
  <span class="nt">--set</span> models.llama3-70b.tp<span class="o">=</span>4
</code></pre></div></div>

<p>An <strong><code class="language-plaintext highlighter-rouge">oci://ghcr.io/antonellof/charts/cognitora</code></strong> one-liner is <strong>not</strong> published yet; track it in the repo’s <code class="language-plaintext highlighter-rouge">plan.md</code>. Until then, local chart path or the quickstart manifest above.</p>

<p>From source (if you want to read the routing code, which I recommend — it is the most interesting part):</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git clone https://github.com/antonellof/cognitora-inference.git
<span class="nb">cd </span>cognitora-inference
cargo build <span class="nt">--release</span> <span class="nt">--no-default-features</span> <span class="se">\</span>
  <span class="nt">-p</span> cgn-router <span class="nt">-p</span> cgn-agent <span class="nt">-p</span> cgn-kvcached <span class="se">\</span>
  <span class="nt">-p</span> cgn-metrics <span class="nt">-p</span> cgn-ctl <span class="nt">-p</span> cgn-operator
</code></pre></div></div>

<p>Once a router is up, point any OpenAI-compatible client at it. The wire protocol is the lingua franca, so existing application code does not change. Use <strong><code class="language-plaintext highlighter-rouge">/v1/embeddings</code></strong> only when the loaded model is an embedding model—chat checkpoints will correctly surface as errors through the stack rather than fake vectors.</p>

<h2 id="why-this-shape-of-system-now">Why this shape of system, now</h2>

<p>The closing observation is meta. For two years the LLM-inference field has tolerated a stack where Python is in the request path, Kubernetes is the only first-class deployment target, and “the orchestrator” is whatever combination of Nginx, Redis, and homegrown schedulers a given team has glued together. That stack works at startup scale. It does not work at datacenter scale, where a 1% efficiency gain is worth more than a feature, where the difference between sub-500-µs and 5-ms routing decisions shows up as a line item, and where the operations team would prefer a single binary they can <code class="language-plaintext highlighter-rouge">strace</code>.</p>

<p>Cognitora is one answer to <em>“what would the orchestrator look like if it were designed today, for that scale, in one language, with KV cache reuse as the centerpiece rather than an afterthought?”</em> NVIDIA Dynamo is another. Both are credible; they make different bets on the runtime shape (six small Rust binaries vs Rust+Python), the deployment surface (bare-metal-first vs Kubernetes-first), and the engine ecosystem (broad including llama.cpp/OpenAI-compat vs the three industrial engines). Which one fits depends on what your fleet actually looks like — and the fact that there are two well-engineered open-source choices in this layer at all is a meaningful change from where the field was twelve months ago.</p>

<p><strong>Links:</strong></p>

<ul>
  <li><a href="https://github.com/antonellof/cognitora-inference">Cognitora repository</a> — Apache-2.0, Rust 1.89+</li>
  <li><a href="https://github.com/antonellof/cognitora-inference/blob/main/CHANGELOG.md">CHANGELOG</a> · <a href="https://github.com/antonellof/cognitora-inference/releases/tag/v0.3.0">v0.3.0 release</a></li>
  <li><a href="https://github.com/ai-dynamo/dynamo">NVIDIA Dynamo</a> — the closest comparable system</li>
  <li><a href="https://github.com/vllm-project/production-stack">vLLM Production Stack</a> — vLLM-only alternative</li>
  <li><a href="https://github.com/ai-dynamo/nixl">NIXL</a> — the disaggregation transport both projects build on</li>
  <li><a href="https://arxiv.org/abs/2401.09670">DistServe</a> — the original prefill/decode disaggregation paper</li>
  <li><a href="https://docs.ray.io/en/latest/serve/">Ray Serve</a> · <a href="https://kserve.github.io/website/">KServe</a> · <a href="https://github.com/triton-inference-server/server">Triton Inference Server</a> · <a href="https://github.com/bentoml/BentoML">BentoML</a> — generic ML-serving alternatives</li>
</ul>]]></content><author><name>Antonello Fratepietro</name><email>antonello.f at gmail dot com</email></author><category term="Systems" /><category term="LLM Inference" /><category term="vLLM" /><category term="SGLang" /><category term="TensorRT-LLM" /><category term="NVIDIA Dynamo" /><category term="KV Cache" /><category term="Disaggregated Inference" /><category term="Rust" /><category term="Kubernetes" /><category term="GPU Orchestration" /><summary type="html"><![CDATA[Inference engines like vLLM, SGLang, and TensorRT-LLM are excellent at saturating one node. They are not, by themselves, a multi-node serving system. Cognitora is a Rust-only orchestration layer shipped as six static binaries—no Python control plane, no Kubernetes-only runtime—that turns those engines into a KV-aware, disaggregated, energy-conscious cluster. This post walks through the architecture, the routing model, and how it stacks up against NVIDIA Dynamo, Ray Serve, KServe, Triton, and the vLLM Production Stack (updated for the v0.3.0 release).]]></summary></entry></feed>